
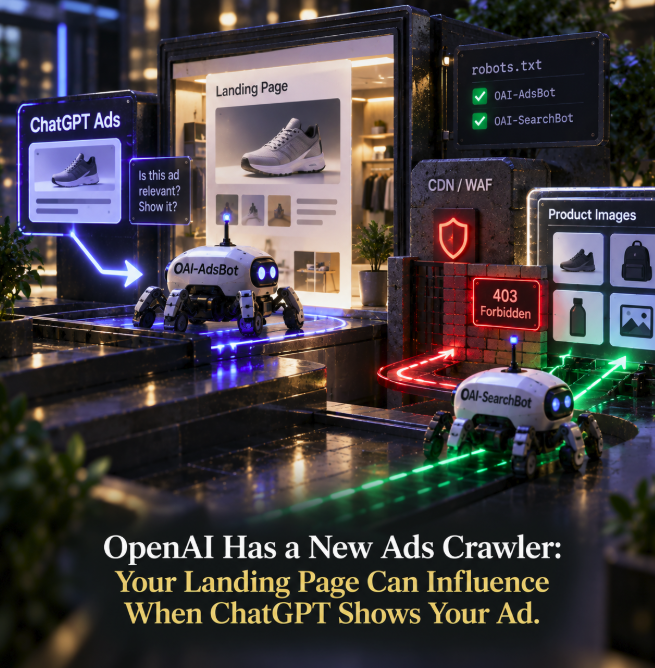
OpenAI now has a dedicated crawler for ChatGPT advertising. The newly documented OAI-AdsBot is used to access and validate landing pages submitted with ChatGPT Ads, and OpenAI says the content it reads can do more than determine whether a destination passes policy review: landing-page content may also help the company decide when an ad is relevant enough to show to users.
The details appear in OpenAI’s newly updated Advertiser Guidance for Allowing OpenAI Web Crawlers. The documentation says advertisers must allow OAI-AdsBot and recommends allowing both OAI-AdsBot and OAI-SearchBot. For advertisers using product feeds, OpenAI adds another technical requirement: OAI-SearchBot needs to be able to crawl product-image URLs, and a 403 response from a CDN, firewall or bot-protection layer can prevent feed processing.
This turns crawler access into an advertising-readiness issue. A landing page can be perfectly accessible to human customers and still fail ChatGPT Ads review if infrastructure blocks OpenAI’s crawler. For product advertisers, the same problem can occur one layer deeper when the page loads but the image host rejects OAI-SearchBot.
OAI-AdsBot is specifically required for ChatGPT Ads
OpenAI’s documentation draws a clear distinction between its advertising crawler and its broader search crawler. OAI-AdsBot is the crawler advertisers need to prioritize for ChatGPT Ads landing-page validation and review. OAI-SearchBot is recommended because it can help OpenAI understand public web content, but it is not presented as a substitute for OAI-AdsBot in the advertising review process.
OpenAI says it may visit a submitted landing page to verify that the destination complies with its advertising policies. If OAI-AdsBot cannot access the page, the advertiser should not assume that support can simply bypass the crawler check manually. The company explicitly advises advertisers to make the destination crawlable and then re-upload or resubmit affected ads if necessary.
For technical teams, that means ChatGPT Ads now has a crawler-access requirement that belongs in the same deployment checklist as page availability, tracking and conversion instrumentation.
The landing page can affect when the ad is shown
The most consequential sentence in the new crawler documentation goes beyond compliance. OpenAI says it may use content from the landing page to determine when the advertisement is most relevant to show to users.
That confirms a direct connection between crawlable landing-page content and ChatGPT’s ad-delivery system. The destination is not simply inspected once for prohibited content and then ignored. Its meaning can participate in the system’s understanding of whether the advertisement fits a user’s conversational context.
This reinforces what OpenAI has already documented about ad selection. As NetContentSEO reported in our analysis of ChatGPT Ads ranking, OpenAI says ad delivery can consider the context and intent of the conversation together with the advertiser’s landing page, title, copy, targeting selections and advertiser-provided Context Hints. The new crawler documentation now explains part of the technical mechanism that makes the landing-page signal possible: OpenAI needs to be able to fetch the destination.
This is not evidence of a simple SEO-style ranking factor
The new documentation does not say that keyword density, schema markup, page length, backlinks or any conventional SEO signal increases ChatGPT ad rank. Nor does OpenAI publish a weighting formula for landing-page content relative to bids, creative, targeting or conversational relevance.
The confirmed claim is narrower and more useful. OpenAI crawls the landing page for advertising review and may use its content to determine when the ad is relevant to show. Advertisers should therefore make the destination technically accessible and semantically clear about the product, service or offer it represents.
That is a content-understanding requirement, not permission to invent a new checklist of unconfirmed “OAI-AdsBot optimization factors.”
robots.txt can stop the review immediately
OpenAI says its crawlers respect robots.txt. If the relevant page or path is disallowed, crawling stops immediately.
The company’s example configuration explicitly allows both user agents:
User-agent: OAI-SearchBot
Allow: /

User-agent: OAI-AdsBot
Allow: /
Advertisers do not necessarily need to expose every path on a site if their security model requires narrower rules, but the pages and assets needed for the campaign must be reachable. A blanket bot-blocking policy can therefore become an advertising deployment problem even when it was originally introduced for anti-scraping or security reasons.
WAFs and CDNs can block a crawler that robots.txt allows
A correct robots.txt file is only the first layer. OpenAI warns that Cloudflare, Akamai and other web-protection systems can classify legitimate crawler traffic as automated abuse and return 403 Forbidden responses.
The documentation tells engineering and security teams to inspect firewall rules, CDN configuration and bot-mitigation systems and to allowlist OpenAI crawler traffic where appropriate. Human-verification systems such as CAPTCHAs, JavaScript challenges, behavioral checks and session-validation requirements can create the same problem because an automated crawler cannot complete a human challenge in the normal way.
OpenAI notes specifically that OAI-AdsBot is officially verified and allowlisted by Cloudflare. Even so, advertisers should verify their own configuration because custom firewall rules and additional security layers can still interfere with access.
Product feeds introduce a second crawler dependency
For product-feed advertisers, allowing OAI-AdsBot to reach the landing page is not the entire job. OpenAI says OAI-SearchBot should also be able to crawl the URLs hosting product images.
This creates a common infrastructure edge case. A merchant’s HTML pages may be served from the main domain while product images come from a separate CDN, image optimization service or media hostname with different bot rules. The landing page can therefore pass crawler access while the product feed still fails because its images return 403 responses.
OpenAI is explicit about the consequence: a 403 response on product-image URLs can block feed processing.
The image CDN is now part of ChatGPT Ads readiness
That detail should matter to ecommerce teams because image infrastructure is often managed separately from the marketing site. Security rules optimized to block scraping may not distinguish OAI-SearchBot from unwanted automation.
Before diagnosing a feed-format problem, advertisers should test whether the image URLs actually return successful responses to the required crawler. OpenAI specifically recommends reviewing firewall, CDN and bot-protection rules on the image host.
The operational lesson is straightforward: product-feed debugging should include the asset-delivery layer, not only the feed file and landing-page HTML.
A 403 can mean infrastructure is blocking the ad pipeline
HTTP 403 errors are especially important because they can be generated at several points. The origin application might reject the request, but so can a WAF, CDN, geo rule, authentication layer or automated bot-defense product.
OpenAI recommends checking whether the landing page returns a successful HTTP response to OAI-AdsBot, whether robots.txt permits the path and whether any WAF, CDN, JavaScript challenge, CAPTCHA, authentication requirement or geographic restriction blocks automated access.
This is a useful diagnostic sequence because a page that works in an advertiser’s browser does not prove it is crawlable. Human and automated requests can take different paths through the security stack.
OpenAI also documents stable IP files for crawler verification
Some security environments require IP-based allowlisting. OpenAI cautions against relying solely on short-term IP observations because crawler infrastructure can evolve, but it now points advertisers to its published crawler IP data at adsbot.json and searchbot.json.
The company recommends combining user-agent identification with verified-bot programs, firewall rules, robots.txt behavior and provider-level verification rather than assuming a manually observed IP address will remain sufficient indefinitely.
That gives infrastructure teams an official reference point when their security policy cannot rely on user-agent strings alone.
Rate limiting can break large campaign uploads
Crawler access can also fail without a permanent block. OpenAI warns that large batch uploads or sudden spikes in crawler traffic can trigger automated rate limits and bot-protection systems.
Teams investigating these failures should look for HTTP 429 responses, firewall or CDN events, request-throttling rules and traffic spikes around the time OpenAI attempted to crawl the destinations. The company suggests that uploading ads in smaller batches over a longer period can reduce these triggers while access is being validated.
This is particularly relevant for large advertisers submitting many landing pages or product destinations at once. A configuration that tolerates occasional crawling may still fail when campaign submission generates a burst of requests.
Non-web destinations can create validation problems
OpenAI recommends using a directly reachable web landing page whenever possible. App-store links, deep links, documents, login-gated destinations, region-specific pages and unsupported redirect chains may not provide enough crawlable content for validation or review.
This again connects ad operations with technical accessibility. A destination can be legitimate for a human user while still being unsuitable for automated validation if reaching its meaningful content requires an app, authentication or interaction that OAI-AdsBot cannot perform.
Advertisers should therefore test the exact submitted destination rather than assuming the broader domain’s accessibility is sufficient.
OAI-AdsBot gives advertisers a new machine audience to design for
Landing pages already serve several audiences: prospective customers, search engines, analytics systems, accessibility tools and security scanners. ChatGPT Ads adds another machine reader with a specific commercial purpose.
OAI-AdsBot needs to understand enough of the destination to validate it, and OpenAI may use the page content when determining ad relevance. That makes clear product identity, offer clarity and crawlable content operationally valuable even before a human clicks the ad.
This does not replace conversion optimization. A page still has to persuade the visitor after the click. But the same page may now also help OpenAI understand whether the ad belongs in a particular conversational context before that click occurs.
The crawler connects technical SEO, paid media and infrastructure
The practical ownership of this issue crosses traditional team boundaries. Paid-media teams control campaigns, content teams shape landing-page meaning, SEO teams understand crawler directives, and engineering or security teams control the WAF, CDN and bot rules that determine whether OpenAI can actually fetch the content.
A campaign can therefore fail even when the media configuration is correct. If OAI-AdsBot is blocked, ad validation can fail. If OAI-SearchBot cannot retrieve product images, feed processing can fail. If the destination is crawlable but semantically vague, OpenAI has less useful landing-page information available when evaluating relevance.
ChatGPT Ads readiness is becoming a cross-functional technical requirement rather than a task that lives entirely inside an advertising dashboard.
This adds a crawler layer to ChatGPT’s paid visibility stack
OpenAI has rapidly been making the mechanics of ChatGPT advertising more visible. NetContentSEO has already covered how Ads Manager opened a self-service paid layer in Italy and how landing pages participate in the ad-selection system.
OAI-AdsBot now adds the technical acquisition layer beneath those systems. Before a landing page can contribute useful information to ad review and relevance, OpenAI must be able to access it.
That creates a simple dependency chain: campaign submission leads to crawler access, crawler access enables validation and content understanding, and that content can then participate in decisions about where the advertisement is relevant.
For ChatGPT advertisers, crawlability is now part of media performance
The new documentation turns what might look like a niche bot-management detail into a direct advertising concern. OAI-AdsBot is required for ChatGPT Ads landing-page validation. OpenAI recommends allowing OAI-SearchBot as well, and product-feed advertisers need OAI-SearchBot to reach product-image URLs.
Most importantly, OpenAI confirms that landing-page content may help determine when an ad is relevant enough to show. The destination therefore participates before the click as well as after it.
ChatGPT Ads now has a crawler layer that advertisers cannot safely ignore. If robots.txt, a WAF, CDN or anti-bot system blocks OpenAI, the problem may not merely reduce machine visibility: it can interfere with ad review, product-feed processing and the information OpenAI uses to understand when the campaign belongs in a conversation.