Microsoft has made Web IQ broadly available to Azure customers, expanding the retrieval infrastructure that gives AI agents access to current, cited information from the web. Announced on November 17, 2026, during Microsoft Ignite, the release adds automated multi-source research, iterative evidence gathering and structured data for places and weather. Commerce capabilities remain in private preview. For SEO and AI Search, the significance lies in how agents discover and attribute information—not in a new Bing ranking update.
What Microsoft announced
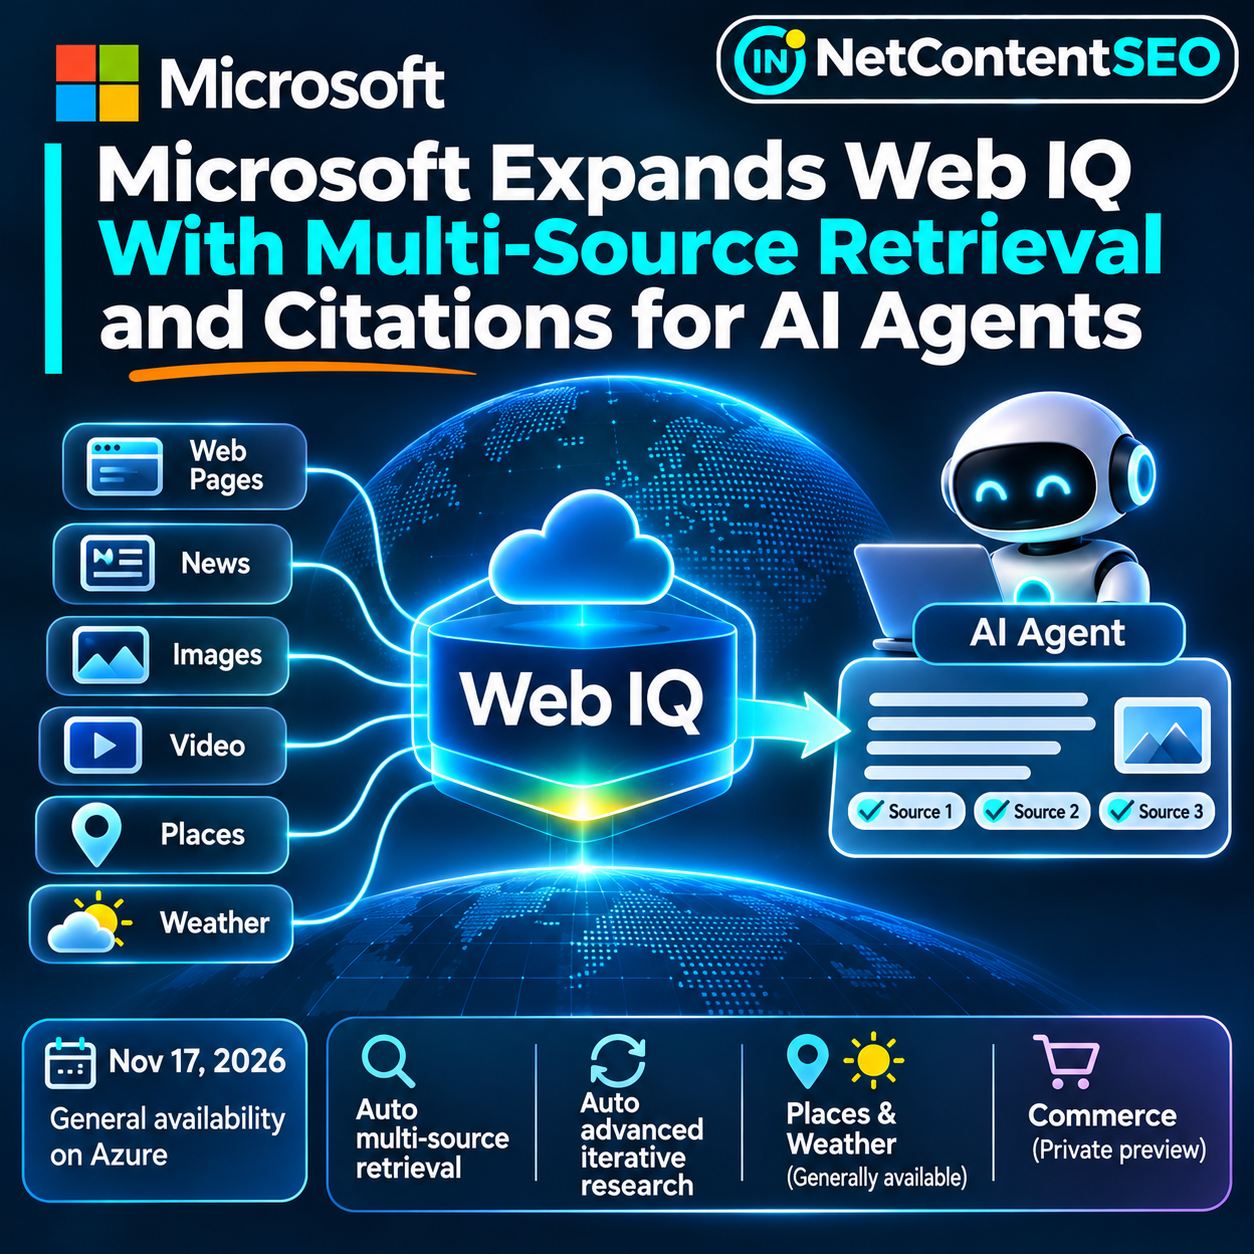
In its official Web IQ announcement, Microsoft confirmed that the service is now available to all Azure customers with lower pricing. Web IQ was originally introduced in June 2026 as a retrieval and grounding layer built on Microsoft's search infrastructure. Its purpose is to supply AI applications with current external evidence rather than relying solely on what a language model learned during training.
General availability does not mean free access: Microsoft's documentation specifies that Web IQ requires a paid Azure subscription and that Azure credits do not apply to the service. Developers can integrate through REST, MCP and supported SDKs, with capability differences between endpoints.
Web IQ Auto: one request, multiple information sources
Web IQ Auto is Microsoft's default orchestration approach. An agent sends a natural-language question, and the retrieval service selects relevant sources across web pages, news, images, videos, weather and places. It returns focused evidence and source references instead of indiscriminately sending entire documents to the model. This design can reduce irrelevant context and the number of tokens the model must process.
For example, a travel-planning assistant could combine current weather conditions with structured opening hours for attractions and recent transport-related news. A business-research assistant could retrieve news, relevant pages and supporting visual information in one workflow. Those examples illustrate the architecture; they do not guarantee every result is accurate or available in every market.
Auto Advanced adds iterative research
Some questions cannot be answered reliably with one retrieval pass. Auto Advanced evaluates whether the collected evidence is sufficient, refines the query and performs additional retrieval when necessary. Microsoft's technical companion article explains that developers can select advanced mode rather than building every search-and-retry step themselves.
The distinction matters because an AI agent needs more than a search result list. It may need to recognize missing facts, search again, compare conflicting sources and retain provenance for its final answer. Microsoft packages more of that research loop into the retrieval layer, while the consuming application remains responsible for interpreting evidence, enforcing business rules and producing an appropriate response.
Structured data: Places, Weather and Commerce
Web IQ Places provides structured information for more than 207 million businesses, landmarks and other locations worldwide, including available addresses, coordinates, phone numbers and opening hours. Weather delivers current conditions and forecasts through Auto. Both are generally available, according to Microsoft's November 17 documentation.
Commerce is different. Its product and offer APIs remain in private preview, with Microsoft describing a corpus exceeding 40 billion structured offers. Developers should not describe Commerce Search or Commerce Offers as universally accessible. Microsoft's claims about offer matching and retrieval quality are based on its own reported tests, not an independent guarantee for all merchants or product categories.
Grounding, citations and publisher controls
Web IQ uses Microsoft's Bing-derived index and returns source-linked evidence so downstream agents can identify where information came from. Microsoft says Bingbot follows robots.txt, while publishers also have separate mechanisms for indexing and AI-grounding preferences. The company introduced page-level AI-grounding controls in October 2026, giving publishers a way to express how content may be used for grounding.
Developers can also configure Web IQ Scopes to include or exclude approved sources. This is especially relevant to enterprise research applications that must prioritize official documentation or a vetted set of websites. Scope controls are not a substitute for checking factual accuracy: a cited source can still be outdated, incomplete or misinterpreted.
Performance and cost: read the benchmarks carefully
Microsoft reports favorable latency, grounding quality, token efficiency and freshness results for Web IQ against several competing retrieval services. It also published a FreshSearch methodology intended to evaluate how quickly providers discover and return newly published information. These are vendor-reported benchmarks with specific query sets, settings and measurement periods. They should not be interpreted as proof that Web IQ will be fastest or most accurate for every application.
Real operating costs depend on API usage, query complexity, retrieved context, model inference, retries and the number of successful completed tasks. A retrieval service that sends fewer tokens may reduce inference costs, but developers still need workload-specific evaluations before drawing conclusions about total cost of ownership.
Why this matters for SEO and AI Search
There is no new SEO ranking factor in the Web IQ announcement. Web IQ is a developer-facing retrieval service, not a public update to Bing's organic ranking system. Nevertheless, its architecture illustrates how AI agents may increasingly discover information: retrieve focused passages, combine sources, inspect evidence and cite original publishers in generated responses.
For publishers, that raises three practical questions. Can a retrieval system discover and access the page? Does the page provide reliable, current information that directly addresses the user's question? And does the AI application actually present a citation or send a visit to the publisher? Those are separate outcomes. Being present in a retrieval index does not guarantee a citation, and being cited does not guarantee traffic or conversions.
SEO teams should continue prioritizing accessible pages, original expertise, precise factual answers, descriptive titles, accurate structured data where appropriate and clear update dates. There is no evidence that Web IQ requires a new proprietary SEO markup format or that participating in its retrieval system automatically improves Google or Bing rankings.
A concrete architecture lesson for independent AI builders
Web IQ demonstrates the value of separating three responsibilities: the language model reasons and drafts; the retrieval layer discovers external evidence; and the application validates sources, manages permissions and decides what action to take. That modularity allows developers to replace a model without necessarily replacing their search stack—or to compare retrieval engines without rebuilding the entire application.
A smaller independent AI system can adopt the same design principles without adopting Azure. A local multi-engine search service could gather candidate sources; a verification component could check URLs, dates and source authority; a retrieval layer could extract relevant passages; and an LLM could then answer with traceable citations. Such an implementation would need its own tests and safeguards. It would not automatically reproduce Web IQ's proprietary index, structured datasets or performance.
What developers should test before deployment
- Freshness: can the service retrieve information published recently, and does it correctly distinguish publication dates from update dates?
- Source provenance: are URLs, titles and citations preserved accurately through every processing stage?
- Evidence sufficiency: does the agent search again when initial results leave important questions unanswered?
- Contradictions: can the workflow identify disagreements between official sources, secondary reports and outdated pages?
- Cost per successful task: measure retrieval fees, tokens, retries and human review rather than only cost per API request.
- Publisher controls: respect applicable access restrictions, licensing requirements and site-specific policies.
- Safety: treat retrieved text as untrusted content and prevent it from becoming executable instructions for tools or agents.
What remains uncertain
The release does not establish how often Web IQ citations lead to publisher visits, whether participating publishers receive more visibility, or whether its commercial datasets will become generally available on a particular date. Microsoft's reported benchmarks also require independent reproduction across representative workloads. Availability and pricing for individual features should be checked against the current Azure documentation before procurement.
The bigger picture
Microsoft's November 2026 Web IQ expansion reflects a broader transition from language models that answer from static knowledge toward AI systems that retrieve and reason over current external evidence. The important advance is not merely adding another search API. It is packaging source selection, multi-step retrieval, structured knowledge and citations into an infrastructure layer designed for agentic workloads. For SEO professionals, that makes source quality and attribution increasingly relevant. For AI developers, it reinforces a simple engineering principle: reliable answers depend on the quality of the retrieval and verification system as much as on the model generating the final text.
Primary sources: Microsoft Bing Web IQ announcement, November 17, 2026; Microsoft technical companion, November 17, 2026; Microsoft Learn: Web IQ overview; Microsoft Web IQ original announcement, June 2, 2026.