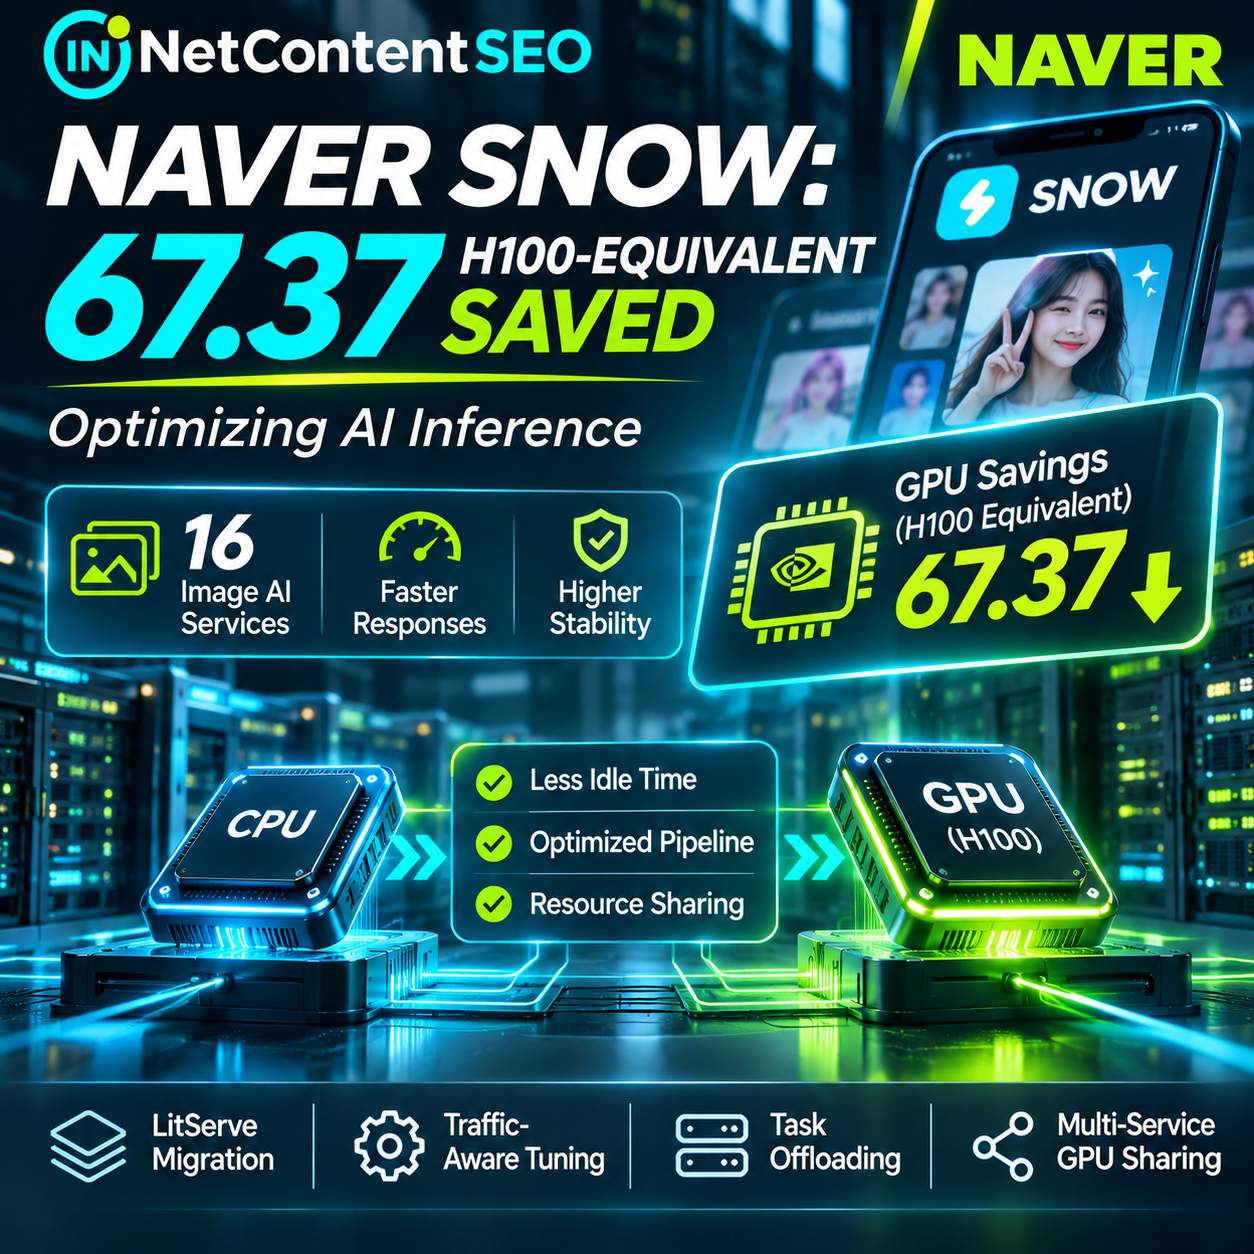
SNOW, the image-AI company within South Korea's NAVER ecosystem, says it freed capacity equivalent to 67.37 NVIDIA H100 GPUs while improving the serving of 16 Image AI services. The result, described in a NAVER Engineering Day 10th technical session, is a striking reminder that AI infrastructure efficiency is not determined by model size or accelerator speed alone. A surprising amount of capacity can be wasted in repeated image conversions, CPU preprocessing queues, idle GPU intervals, inappropriate concurrency settings and isolated deployments.
Evidence note: The numerical result and optimization steps below come from the NAVER D2 session description supplied for this report. The original NAVER D2 session page and its English-version link were not directly retrievable during our check. Related first-party NAVER D2 engineering publications and a CNCF SNOW case study corroborate the broader production GPU infrastructure context, but they are not independent verification of the exact 67.37 figure. We therefore attribute that figure to SNOW's presentation rather than describing it as an independently audited measurement.
What does “67.37 H100 GPUs saved” actually mean?
The reported total is an H100-equivalent resource saving aggregated across 16 Image AI services. It does not, by itself, establish that 67 physical H100 boards were removed from a data center, that the company sold or decommissioned 67 GPUs, or that a fixed dollar amount was saved. The session summary does not supply a full baseline inventory, a normalization formula, before-and-after energy consumption, unit cost, or the time period used to calculate the total.
Those distinctions matter. GPU-equivalent capacity is useful for capacity planning, but it is not interchangeable with purchased hardware, electricity savings or cloud-billing reductions. It is also not a percentage improvement unless the original baseline is known.
The original bottleneck: GPU time lost between useful computations
Image inference is a pipeline, not a single GPU kernel. An incoming request may need decoding, resizing, normalization, CPU-side preprocessing, transfer to GPU memory, model execution, postprocessing, encoding and response delivery. If these stages run serially or compete for limited CPU threads, a powerful GPU can spend time waiting for work.
SNOW's presentation identifies redundant image encoding and decoding, CPU–GPU waiting time, and unnecessary operations as areas for optimization. This suggests a broader lesson: the limiting resource can be outside the accelerator. Increasing GPU count will not necessarily solve a preprocessing bottleneck or an overloaded request queue.
1. Moving the serving stack to LitServe
The first major intervention was a transition to LitServe, an open-source model-serving framework. In the session description, this migration enabled work on repeated image encode/decode steps and CPU preprocessing delays. The engineering principle is to reduce redundant transformations and allow stages of the request path to overlap where safe and useful.
For example, when CPU preprocessing for request B can proceed while the GPU computes request A, end-to-end throughput may improve even without changing the neural network weights. This is a conceptual illustration of pipeline overlap, not a benchmark or architecture diagram claimed to have been published by SNOW.
2. Tuning concurrency for actual traffic
The team adjusted worker counts, thread counts, CPU limits and CPU core affinity. These parameters interact: too few workers can leave GPUs idle, while too many can increase contention, memory pressure and context-switch overhead. The right configuration depends on request size, model execution characteristics, arrival patterns and latency objectives.
SNOW also describes improvements to autoscaling logic and iterative experiments with agent-assisted review. The session summary does not specify the agent model, optimization algorithm, test methodology or exact contribution of agent assistance, so those details should not be invented. The actionable idea is to tune against observed traffic rather than assume that a single default configuration fits every image-AI endpoint.
3. Moving lightweight tasks away from the GPU
Not every operation in an image-processing request requires GPU acceleration. Some inexpensive or irregular tasks may be more efficient on CPU, especially if placing them on the GPU adds synchronization or scheduling overhead. SNOW's account describes separating lightweight work onto CPUs to preserve accelerator time for operations that benefit from parallel GPU computation.
This is not a universal rule that CPU processing is always cheaper or faster. Transfers between CPU and GPU can themselves be costly. Teams should profile each stage and compare end-to-end latency and throughput before deciding where work belongs.
4. Sharing GPUs across multiple services
The team also worked to co-locate multiple services on shared GPU capacity. An isolated service can reserve substantial accelerator memory or compute while experiencing intermittent demand. Pooling compatible workloads may improve aggregate utilization, provided isolation, memory limits, scheduling fairness and latency are controlled.
This fits the larger infrastructure direction documented by CNCF's SNOW case study, which discusses GPU orchestration for a large fleet of AI workflows and volatile traffic. However, that separate case study should not be conflated with the specific 16-service, 67.37-H100-equivalent presentation. The scopes and reported measurements are not demonstrated to be identical.
What the team says improved
The presentation summary reports cumulative improvements in response speed, throughput, first-request warm-up, error rate, cancellation rate and GPU utilization. It does not provide numeric before-and-after values for those indicators in the material available to us. Accordingly, a responsible summary cannot state a specific latency reduction, throughput multiplier or error-rate percentage.
| Metric | Reported direction | Verified numeric delta |
|---|---|---|
| GPU capacity | Lower requirement | 67.37 H100-equivalent, reported by SNOW |
| Response latency | Improved | Not provided |
| Throughput | Improved | Not provided |
| First-request warm-up | Improved | Not provided |
| Error and cancellation rates | Improved | Not provided |
| GPU utilization | Improved | Not provided |
Why this matters beyond image generation
The same systems-level reasoning can apply to text inference, multimodal applications, search rerankers and retrieval-augmented generation pipelines, although the implementation and optimal serving framework differ. A local Ollama installation on a Windows mini-PC is not equivalent to a fleet of H100 servers, and SNOW's reported savings cannot be extrapolated to it. But profiling prompt preparation, document retrieval, CPU load, model loading, queueing and accelerator occupancy can reveal similar categories of waste.
For AI Search infrastructure, this matters because latency and cost affect how many model calls a service can afford per query. Faster reranking or image inference could support richer experiences at a given compute budget. That is a general architectural implication, not evidence that this particular SNOW project changed NAVER's public search rankings, AI Briefings or SEO algorithms.
What an engineering team can test
- Establish a baseline: measure p50, p95 and p99 latency, requests per second, failure and cancellation rates, CPU saturation, GPU utilization and memory occupancy under representative traffic.
- Profile the full request path: distinguish image decoding, preprocessing, transfers, inference, postprocessing and encoding. Identify where the GPU is waiting.
- Remove duplicate transformations: test whether data can stay in a suitable representation between stages without repeated encode/decode cycles.
- Test pipeline overlap: compare serial and concurrent preprocessing/inference paths, checking correctness and memory use.
- Sweep worker and thread settings: change one variable or controlled parameter group at a time; include CPU affinity and autoscaling thresholds.
- Evaluate workload placement: benchmark lightweight CPU offloading against GPU execution including transfer overhead.
- Test safe co-location: place compatible services together only after validating isolation, memory headroom, peak-load latency and failure recovery.
- Repeat at production-like traffic levels: test cold starts, bursts and sustained load; document the baseline and any regression.
These are recommended evaluation steps derived from the reported engineering themes, not a claim that SNOW used this exact test protocol.
What comes next: Image Harness and automatic tuning
The session lists an Image Harness and automatic optimization based on real traffic among future tasks. The supplied summary does not define Image Harness's complete architecture or announce a public product launch. It is best understood here as a named future engineering direction rather than a generally available framework.
Traffic-aware tuning could eventually reduce the manual effort required to choose worker counts, autoscaling thresholds and service placement. But automated optimization also needs guardrails: it must not trade away response quality, reliability or predictable tail latency merely to raise GPU utilization.
Frequently asked questions
Did SNOW physically eliminate 67 NVIDIA H100 cards?
The supplied NAVER presentation describes a saving of 67.37 H100-equivalent GPU resources. It does not establish that 67 physical cards were removed or sold.
How many Image AI services were optimized?
Sixteen services, according to the NAVER Engineering Day session description.
What is LitServe's role?
SNOW describes a serving-stack transition involving LitServe and optimization of repeated image transformations and CPU–GPU waiting time. The available summary does not quantify LitServe's isolated contribution to the total saving.
Did AI agents perform the optimization automatically?
The presentation mentions agent experiments and review as part of iterative optimization. It does not demonstrate that agents autonomously produced the entire result or identify their exact contribution.
Does this change NAVER Search ranking?
No such claim is supported. The case concerns image-AI model serving infrastructure, not a documented Search ranking update.
Can small local AI systems benefit from the same ideas?
Potentially, yes: profiling, reducing redundant work and matching concurrency to actual hardware can help. The achievable gains and appropriate tools must be measured independently for each environment.
The bigger lesson
SNOW's reported achievement is a case for engineering efficiency before hardware expansion. The headline number attracts attention, but the durable lesson is how latency, reliability and capacity can be improved together by looking beyond the GPU kernel. As AI services multiply, the ability to identify idle time, avoid unnecessary work and share resources safely may become as important as access to faster chips.
Sources and disclosure: NAVER D2, “Image AI 서빙 최적화: CPU와 GPU의 빈 시간을 줄여 H100 67장을 절감하기까지” (session description supplied to NetContentSEO; full page not directly retrievable during verification); English version listed by NAVER; NAVER D2, SNOW Kubernetes GPU cluster engineering; CNCF, SNOW Corp. GPU orchestration case study. The 67.37 figure is attributed to the source presentation and should not be represented as independently audited. Barry Schwartz coverage was not checked.