November 9, 2026 | NetContentSEO Research
Amazon researchers have introduced HOPE, short for Higher-Order Pruning of Experts, a method for making large Mixture-of-Experts (MoE) language models smaller without treating their individual experts as isolated components. The approach matters because the memory required to host a large model can be a major constraint on inference, even when only a small fraction of its experts are activated for each token.
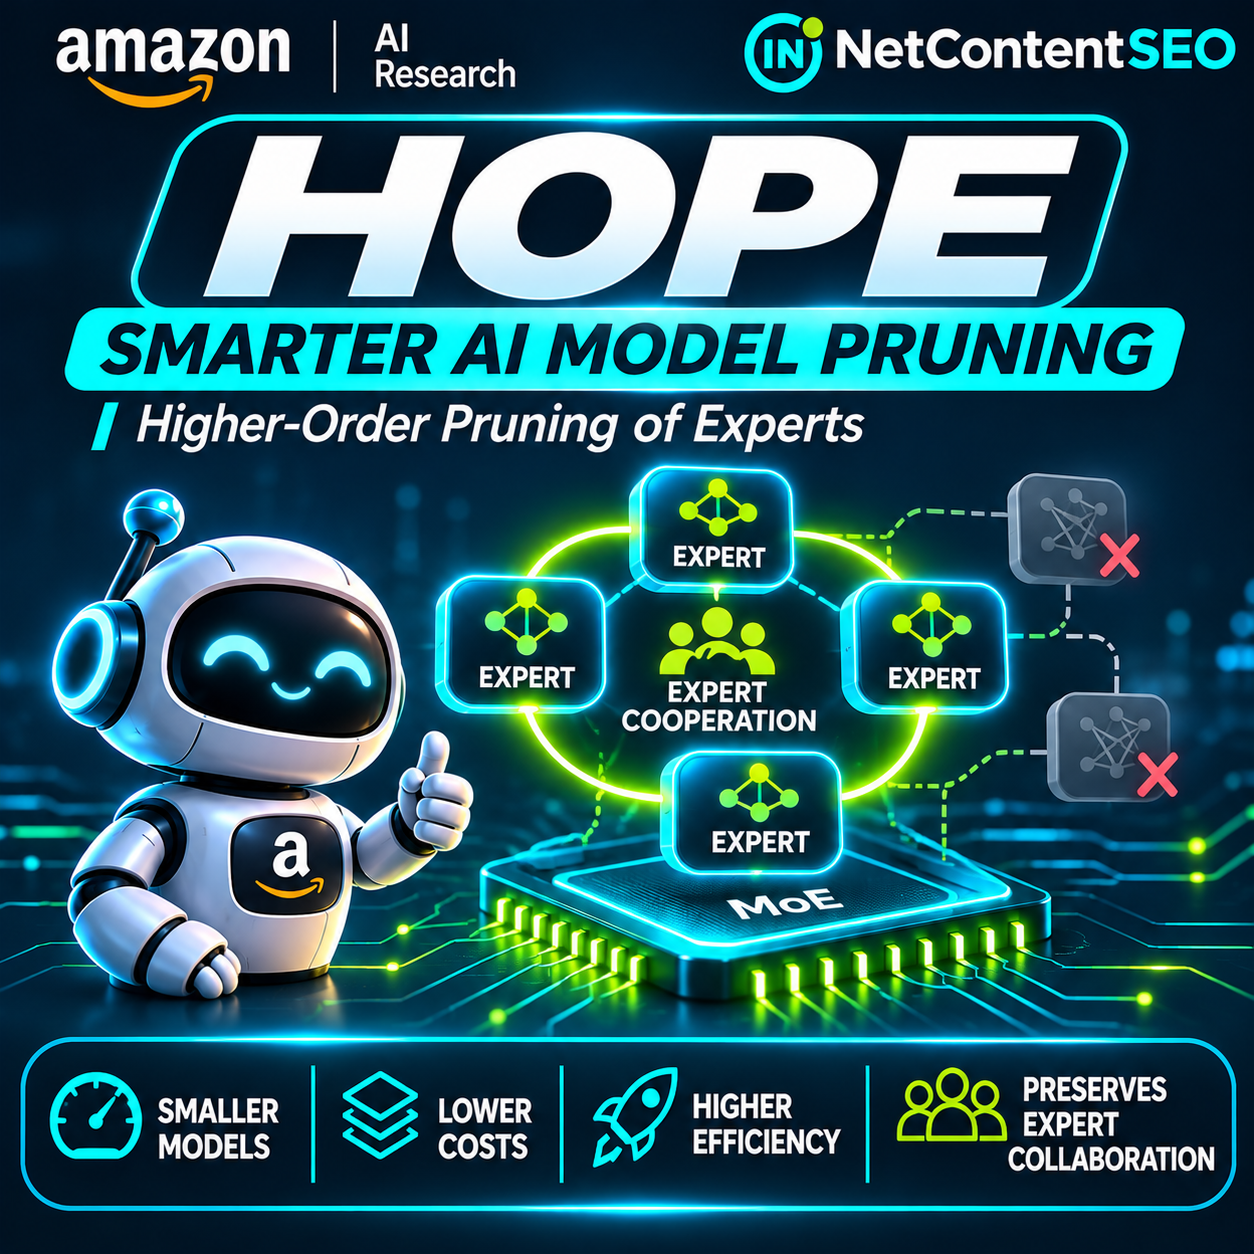
The research, published as Higher-order pruning of experts in mixture-of-experts language models, argues that experts often work in cooperative groups. Removing one apparently unimportant expert may damage the contribution of another expert with which it frequently interacts. HOPE attempts to preserve those relationships when selecting experts for removal.
Why MoE models have a memory problem
Mixture-of-Experts models route each input token to a subset of specialised neural-network components rather than activating every component for every token. This makes it possible to increase total parameter capacity without increasing active computation in the same proportion. But the inactive experts still occupy storage and, depending on deployment architecture, substantial accelerator memory.
The researchers use Qwen3.5-122B as an example: it has 256 experts per MoE layer across 48 layers, yet only eight experts per layer are selected for an individual token. The authors say expert weights account for roughly 95% of the model's approximately 250 GB parameter-memory footprint. That creates pressure on GPU capacity otherwise available for context caching, concurrent requests and other inference workloads.
Expert pruning addresses this problem by permanently removing selected experts. Unlike dynamically loading and unloading experts, a pruned model has fewer parameters to store and serve. The central challenge is deciding which experts can be removed without degrading the tasks that matter.
What HOPE changes: preserving cooperation instead of ranking experts alone
Traditional first-order pruning methods give each expert an individual importance score and remove those ranked lowest. That approach is simple, but it assumes the value of each expert can be assessed independently. The Amazon team's central observation is that experts are frequently co-activated in stable combinations.
HOPE measures pairwise interactions between experts during a calibration pass. It builds an interaction matrix whose diagonal reflects individual contributions and whose off-diagonal entries capture the relationships between expert pairs. It then selects a group of experts to remove by optimising a quadratic objective that accounts for those interactions.
This is not a method that merely keeps the most frequently used experts. It may preserve an expert with a lower standalone score because that expert contributes to a valuable cooperative group. The paper also shows that the earlier REAP approach can be understood as a special case when the pairwise interaction terms are ignored.
What the experiments actually found
The authors tested HOPE on three MoE models: Qwen3.5-122B, Qwen3.5-35B and GLM-4.5-Air. They used two calibration datasets and evaluated the resulting models across benchmarks for mathematics, instruction following, coding and agentic software engineering.
At a 50% expert-pruning rate, HOPE achieved an average rank of 1.58 among five compared methods, versus 2.42 for the next-best method, REAP. The researchers reported improvements of up to 6.1 percentage points on agentic coding workloads. These are results from the tested models and benchmarks, not a guarantee for every MoE architecture.
One example is particularly revealing. On SWE-bench Pro with Qwen3.5-35B-A3B pruned by 50%, the authors report a score of 42.3 for HOPE, compared with 36.2 for REAP and 41.8 for the unpruned model. A pruned model matching or slightly exceeding its original score on a specific benchmark is possible, but it does not mean pruning universally improves model quality.
The advantage was strongest at aggressive pruning rates of around 40–50%. At 10–20%, simpler first-order approaches could remain competitive. HOPE also optimises experts within each layer rather than fully modelling interactions across all layers.
Does pruning half the experts mean halving inference costs?
No. A 50% pruning rate refers to the number of experts removed under the experiment's pruning configuration. It is not equivalent to a measured 50% reduction in end-to-end inference cost, latency or electricity consumption. Total resource use depends on remaining model components, memory movement, hardware, batching, quantisation, context length and serving software.
The authors' main claim is better quality retention at a given pruning level. Reduced parameter memory may create opportunities for lower-cost serving or greater concurrency, but those deployment benefits require separate measurement on real workloads. HOPE is a model-compression technique, not an announcement of a new consumer AI search engine.
Why agentic workloads are an important test
Long-running agents do more than answer a single question. They may read documents, call tools, inspect results, write code and revise their plans across many steps. Such tasks can exercise a wider range of expert combinations than simple short-form prompts.
The researchers found that preserving cooperative expert structures was particularly useful on challenging agentic coding tasks. That result suggests a possible route to making smaller MoE models more capable on complex workflows, but it does not establish equivalent gains for web search, citation accuracy or brand recommendations.
What this means for SEO and AI Search
For SEO professionals, HOPE is relevant at the infrastructure layer rather than the ranking layer. If future deployments can retain more reasoning and tool-use capability with smaller memory footprints, providers may be able to run agents more economically, support more simultaneous sessions or offer specialised models in additional environments.
That could eventually influence the economics of AI-powered discovery, including agents that retrieve pages, compare products or research businesses. However, the study did not test search ranking, retrieval quality, source attribution, publisher traffic or AI citations. There is no evidence here that HOPE directly changes which websites ChatGPT, Grok, Gemini or other systems recommend.
For brands and publishers, the correct conclusion is not to change schema markup or content strategy in response to this paper. It is to recognise that the cost and capability of the underlying models can affect how quickly agentic search experiences evolve.
How developers can test HOPE
The researchers released an Apache-2.0-licensed implementation on GitHub. The documented workflow has three stages: calibrate a supported MoE model with representative prompts, solve for the pruning set, and produce a smaller checkpoint. The repository includes commands and a Python API.
Before testing, developers should verify model architecture compatibility, GPU memory requirements and the version of Hugging Face Transformers supported by the repository. Calibration data should resemble the intended production workload; a model optimised only for coding prompts may behave differently on multilingual search or customer-support tasks.
A meaningful evaluation should compare the original model, HOPE and at least one first-order pruning baseline at the same pruning rate. Measure task accuracy, tool-use reliability, long-context performance, throughput, latency, GPU memory and cost per successful task. For retrieval-based systems, add source fidelity and citation verification rather than assuming benchmark improvements translate automatically to better grounded answers.
Limitations and unanswered questions
The results are promising but remain bounded by the models, calibration sets and benchmarks in the study. HOPE captures pairwise relationships, not all possible higher-order interactions. Its standard implementation prunes each layer independently. The authors also note that the advantage over simpler methods is smaller at low pruning rates.
Another important distinction is between the mathematical pruning objective and complete downstream behaviour. The paper provides a theoretical treatment of a bound on pruning-related error, but this does not constitute a universal guarantee of unchanged model accuracy, hallucination rates or retrieval behaviour after compression.
Frequently asked questions
What is HOPE in AI?
HOPE stands for Higher-Order Pruning of Experts. It is a technique for compressing Mixture-of-Experts language models by considering interactions between experts when deciding which to remove.
Who developed HOPE?
The paper is authored by Alex M. Tseng, Prannay Kaul, Luca Zancato, Wei Xia and Stefano Soatto. The accompanying implementation is published through the AWS Labs GitHub organisation.
Does HOPE make language models more accurate?
It aims to preserve more capability than competing pruning methods at the same compression level. Some benchmark scores matched or exceeded the unpruned baseline, but results depend on model, task and pruning rate.
Can HOPE reduce GPU memory requirements?
Removing experts reduces the parameter footprint of supported MoE checkpoints. Actual accelerator memory savings and deployment costs depend on the serving configuration and must be measured.
Does HOPE improve AI search citations or Google rankings?
No such effect was demonstrated. The study evaluates model pruning and downstream tasks, not search engine rankings, citation selection or publisher visibility.
Is HOPE open source?
Yes. The researchers provide an implementation in the AWS Labs GitHub repository under the Apache 2.0 licence, with documented calibration, optimisation and pruning steps.
The larger signal
HOPE adds evidence that compressing AI models is not simply a matter of deleting the least active components. Preserving relationships among specialised experts can be important, particularly when models are used for long, multi-step agentic tasks.
For AI Search, the significance is prospective: more efficient models could change the economics of deploying agents and retrieval systems. But better compression is not the same thing as better search relevance or greater brand visibility. Those outcomes still require their own tests.