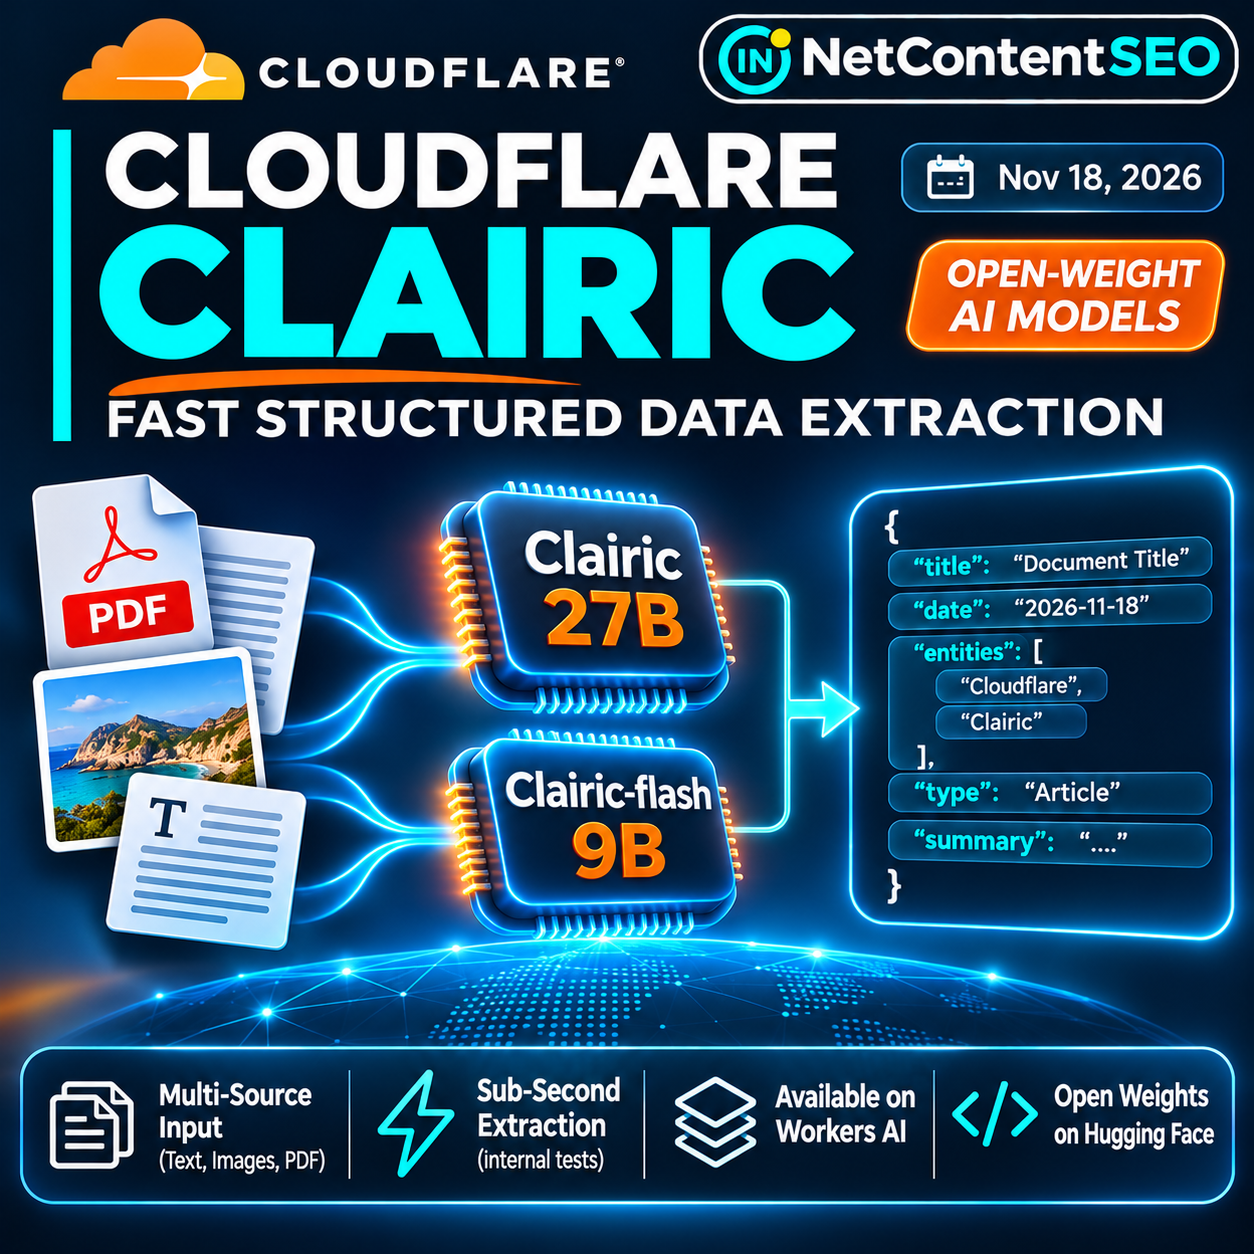
Cloudflare has released two open-weight models built specifically to extract structured information from unstructured documents. Announced on November 18, 2026, the updated 27-billion-parameter Clairic and the new 9-billion-parameter Clairic-flash can process text, images and PDF pages, returning typed fields rather than long free-form answers. Both are available through Cloudflare Workers AI and as downloadable model weights on Hugging Face. Their potential value for SEO and AI Search is indirect but concrete: they could make evidence extraction, document processing and retrieval pipelines faster and easier to audit.
What Cloudflare released
Cloudflare's official announcement describes an updated Clairic model, redesigned after an October preview, and a new smaller Clairic-flash. The 27B model focuses on extraction accuracy, while the 9B variant targets lower latency and cost. Both support structured fields such as names, dates, numbers, lists and line items, including data extracted from images and PDFs. A request can include up to four images or PDF pages in total under the documented limits.
The models belong to Cloudflare's System One research effort, which specializes smaller models for defined tasks instead of asking a general-purpose LLM to handle every step of an application. Cloudflare also announced the Workers AI Superintelligence team, responsible for this work and related decision models such as Clef.
How Clairic differs from a conventional chatbot
A standard generative model may receive an invoice and be prompted to describe its contents. Clairic instead accepts an input state and a schema specifying exactly which fields should be extracted. For example, a developer can request supplier name, invoice date, individual line items and total amount. The response provides typed values, confidence information and character spans where applicable, allowing downstream software to validate the result.
This approach helps separate data extraction from explanation or decision-making. The output is still probabilistic and may contain mistakes; a well-formed field is not automatically a correct field. Cloudflare recommends using confidence and null probabilities to determine which results can be automated and which need additional checks.
What changed in the new architecture?
Cloudflare redesigned the extraction process after its initial preview. For ordinary text and numeric fields, the models now use parallel slot autoregressive generation rather than a single forward pass. Each field generates its own sequence of tokens while fields advance together in a serving batch. Cloudflare says this improves accuracy for complex inputs, including tables, lists, dates and images, with a modest latency trade-off.
Specialized components also handle estimates, forecasts, durations, calculated dates and arithmetic. These capabilities are not a replacement for deterministic calculations or specialist forecasting systems. For financial or operational decisions, extracted values should be checked and calculations should be performed in code when possible.
Cloudflare's benchmark results: promising but self-reported
Cloudflare explicitly states that there are no public extraction benchmarks yet and characterizes its internal comparisons as directional. On its fresh-text-fields evaluation, the updated 27B Clairic extracted 335 of 336 fields correctly, compared with 328 of 336 for Clairic-flash and 295 of 336 for the earlier preview. On a synthetic receipt evaluation, both new models achieved 576 of 576 fields, while the preview reached 369 of 576. These are results on Cloudflare's own evaluation sets, not independently replicated evidence of universal accuracy.
The company also measured full HTTP-response latency on a self-hosted server. For fresh text fields, Clairic recorded a median of 358 milliseconds and a 95th-percentile latency of 736 milliseconds. Clairic-flash recorded 155 milliseconds median and 328 milliseconds at the 95th percentile. On image-field tasks, the reported medians were 453 and 305 milliseconds respectively. Hardware, serving configuration, input length and request mix can change these figures significantly.
These numbers should not be interpreted as a promise that a 9B or 27B model will run at sub-second speed on a typical laptop or CPU-only server. Independent benchmarks and workload-specific testing are needed.
Workers AI pricing and open-weight availability
Cloudflare hosts the models at @cf/cloudflare/clairic and @cf/cloudflare/clairic-flash. The standard prices are $0.24 per million input tokens for Clairic and $0.10 for Clairic-flash. Through November 30, 2026, both receive a promotional price of $0.10 per million input tokens; the larger model returns to $0.24 on December 1. Cloudflare says it charges only for input tokens for these endpoints, absorbing output-generation costs.
Both sets of weights are published on Hugging Face, including Clairic 27B and Clairic-flash 9B. The published repositories provide the model files and usage instructions for self-hosted inference. Open-weight availability offers deployment flexibility, but the real resource requirements depend on quantization, framework, memory and acceleration. Developers should verify the license and technical dependencies for their intended deployment.
Why structured extraction matters for AI Search
AI Search systems often combine retrieval, extraction, reasoning and answer generation. A search engine or research agent may discover a source page, but it still needs to identify dates, entities, prices, eligibility rules or other factual details before producing a useful answer. A specialized extraction model can turn unstructured content into a typed intermediate representation that downstream software can validate.
For example, a travel research pipeline might extract opening hours, seasonal restrictions and contact details from official documents, then compare those fields with other sources before drafting a visitor guide. An SEO audit pipeline could identify document titles, dates, canonical references or product attributes from heterogeneous inputs. These are potential applications, not benchmarked Clairic use cases demonstrated for SEO by Cloudflare.
Crucially, extracting a field is not the same as verifying that it is true. A document may be outdated, a scanned table may be ambiguous or two official sources may disagree. A robust workflow must retain the original URL or document, record extraction confidence, check dates and resolve contradictions before publication.
Does Clairic change SEO rankings or GEO citations?
No direct ranking change has been announced. Clairic is a developer-facing model family, not a Google or Bing ranking update. Publishing structured data or using Clairic to process documents does not guarantee inclusion in AI Overviews, AI Mode or other generated answers.
The indirect SEO value comes from operational quality. Publishers and technical teams can potentially process more source material, identify missing facts and maintain accurate content more efficiently. AI applications can also use structured extraction to ground answers in explicit evidence rather than relying on a language model to infer every detail from raw text.
For GEO, the important distinction remains between discoverability, extraction, citation and referral traffic. A model that extracts a page's facts more reliably does not necessarily cite the page or send users to it. Attribution and user behavior must be measured separately.
A practical architecture for document-grounded agents
A reliable pipeline can separate responsibilities into stages. First, a search or crawling component discovers candidate sources. Second, a retrieval service downloads permitted pages or documents and records provenance. Third, an extraction model such as Clairic converts relevant passages or images into structured fields. Fourth, deterministic code validates formats, dates, arithmetic and consistency. Finally, a generative model writes a user-facing explanation with traceable citations and appropriate uncertainty.
This modular approach is useful because each stage can be evaluated independently. Teams can compare Clairic with OCR-plus-LLM pipelines, swap models without rewriting their search service and route low-confidence results to human review. It also reduces the temptation to ask one large model to browse, extract, calculate, verify and publish in a single opaque step.
What developers should test before adoption
- Representative documents: evaluate actual invoices, reports, scanned PDFs, tables and multilingual documents from the intended workflow.
- Field-level accuracy: measure missing values, false positives, date parsing, table alignment and numerical errors rather than only overall task completion.
- Source traceability: retain the document, page and extracted span where available so a reviewer can inspect the evidence.
- Performance on target hardware: benchmark model loading, memory, latency and throughput, including cold starts and batch sizes.
- Total operating cost: compare Workers AI pricing with local inference costs, infrastructure, retries and human validation.
- Security and privacy: apply access controls, review data-handling requirements and treat external documents as untrusted input.
- Failure handling: use confidence thresholds, null values and human review for uncertain or high-stakes extractions.
What remains uncertain
Cloudflare's extraction and latency results have not yet been established by independent public benchmarks. The reported performance depends on its internal test sets and serving infrastructure. The announcement also does not demonstrate how the models perform across all languages, complex multi-page documents beyond the stated input limit, or every real-world document layout. Their suitability for local deployments must be tested on the actual hardware.
The bigger picture
Clairic and Clairic-flash illustrate a growing pattern in AI infrastructure: using specialized, relatively compact models for defined tasks instead of relying on a large generative model for every operation. If their reported strengths hold across independent workloads, structured extraction could become a more efficient building block for document analysis and agentic retrieval. For SEO and AI Search, the practical opportunity is to build systems that preserve source evidence, validate facts and produce more dependable answers—not to chase an unproven ranking advantage.
Primary sources: Cloudflare, “An updated Clairic and Clairic-flash are now open-weight,” November 18, 2026; Cloudflare, “Introducing Clairic,” October 19, 2026; Clairic model repository; Clairic-flash model repository.