

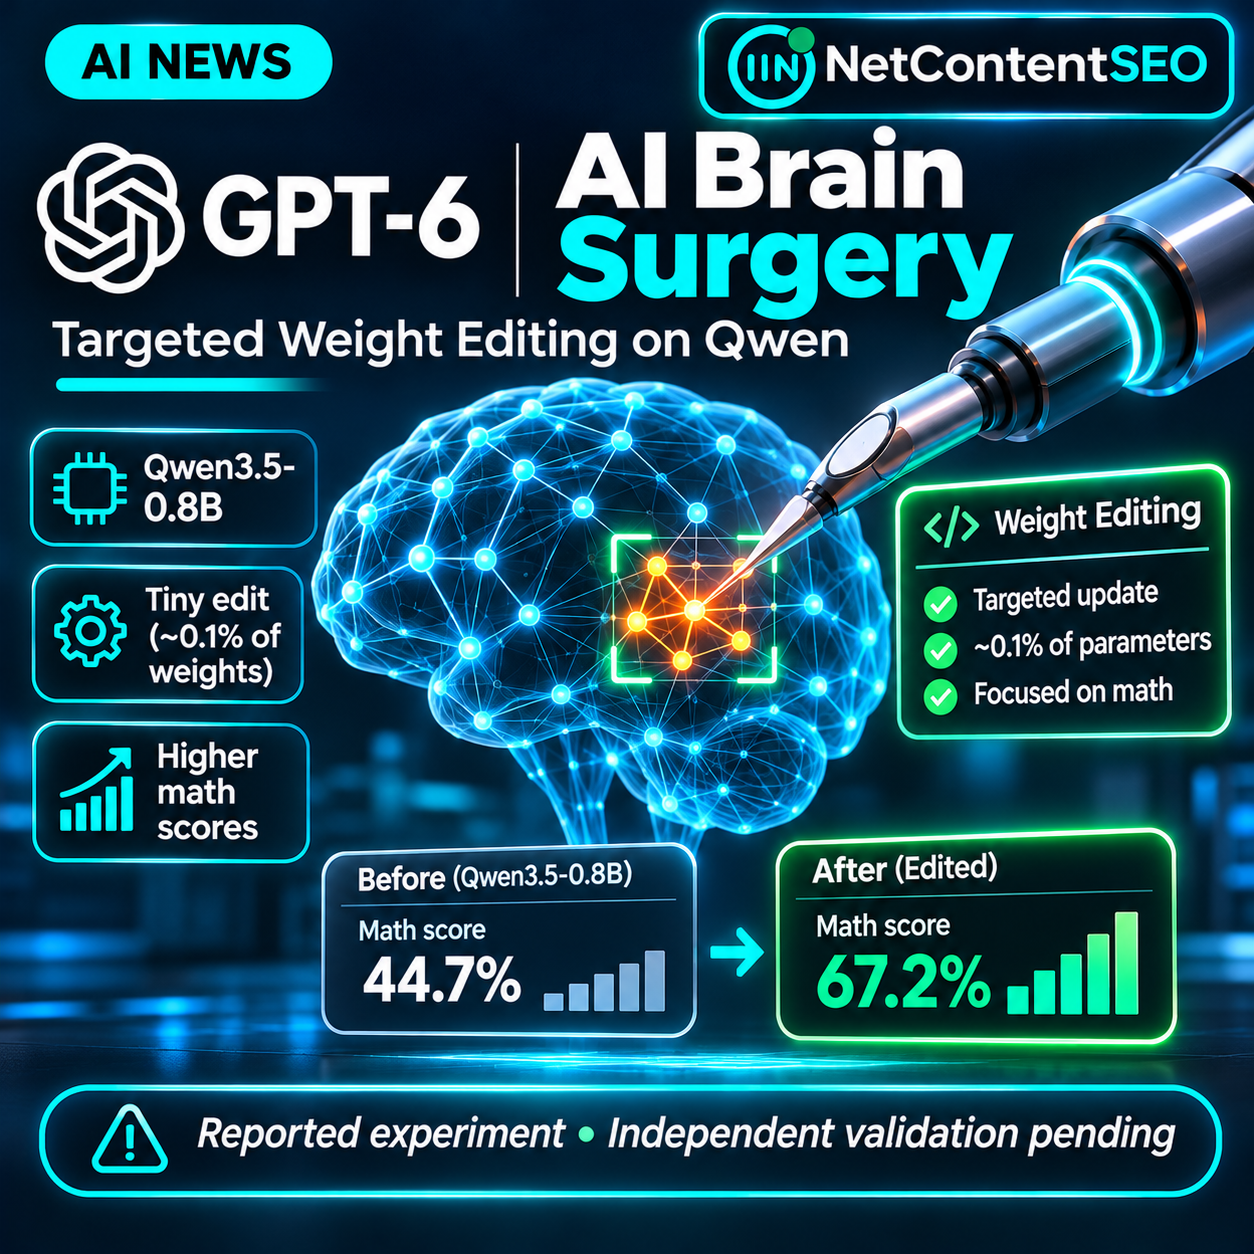

A Reddit post claims that GPT-6 Astra improved a smaller AI model by editing a tiny portion of its neural-network weights rather than running a conventional training cycle. The author calls the experiment “brain surgery,” but the phrase is a metaphor: no biological brain, patient or surgical procedure was involved. The reported intervention concerns the numerical parameters of an existing language model.
The post, “GPT-6 successfully performed ‘brain surgery’ on another AI to make it smarter,” has also been discussed in a November 4, 2026 write-up. Its reported results are intriguing, but should be treated as an account of an experiment rather than an independently reproduced breakthrough.
What was reportedly edited?
The target was Qwen3.5-0.8B, a relatively small language model with roughly 800 million parameters. According to the account, it struggled with certain mathematical reasoning tasks by entering repetitive output loops and exhausting its response budget. The author describes giving GPT-6 Astra access to a Python environment containing the model's weights, then having it identify and modify a very small subset of parameters associated with the unwanted behavior.
The reported change affected approximately 0.016% of the model's weights. That percentage is a claim from the experiment, not a verified general threshold for improving language models. The author says mathematical evaluation improved substantially after the intervention, while also describing follow-up work on another model. Without a complete reproducible procedure and independent assessment, the scale and generality of the improvement remain uncertain.
Why targeted weight editing is different from fine-tuning
Traditional fine-tuning updates model parameters using training examples and an optimization process. Targeted model editing instead attempts to modify specific internal behavior through a smaller intervention. In principle, such edits could correct a persistent failure without requiring a full retraining cycle. The challenge is ensuring that a local change fixes the intended behavior without damaging unrelated capabilities.
The central technical question is not whether changing weights can change a model's outputs—that is expected—but whether an agent can reliably identify which weights to modify, predict the consequences and validate the result across unseen tasks. A striking improvement on one benchmark can coexist with regression elsewhere.
What does the reported math improvement prove?
The published account describes a large gain in mathematical performance, but the result needs context: which benchmark was used, what evaluation prompts and scoring rules applied, how many attempts were made, and whether the same examples informed the editing process. The difference between a model stopping repetitive loops and genuinely acquiring stronger mathematical reasoning is also important. A model can achieve a higher score simply by producing more complete answers, without developing a broadly transferable reasoning capability.
To assess the claim, researchers would need the initial checkpoint, the precise parameter modifications, the evaluation harness, a comparison with simpler baselines and tests for regressions. Ideally, another team would reproduce the results without access to the original author's exploratory choices.
Could AI agents become model engineers?
If the experiment holds up, its significance would lie in an AI agent carrying out part of the model-development workflow: diagnosing a behavior, selecting an intervention and testing the modified system. That is conceptually different from asking a chatbot to explain why another model failed. The agent would be acting on the model's implementation rather than merely discussing it.
However, one demonstration does not establish a dependable autonomous model-improvement loop. The experiment's computational conditions, safeguards, reproducibility and possible failure cases matter as much as its best reported score. A practical system would also need rollback mechanisms, integrity checks, broad evaluation suites and human review before modified weights are deployed.
Why the headline can mislead
“Brain surgery” is vivid shorthand, but neural-network weights are not biological tissue, and parameter editing is not neurosurgery. This Reddit story should also not be confused with the separate late-October 2026 reports about AI agents controlling equipment for gene-therapy injections in mice. Those involve physical laboratory procedures; this case involves editing a digital model.
The distinction matters because headlines that blur metaphor and mechanism can create unrealistic expectations about what AI systems have demonstrated. The interesting claim is already substantial without implying that an AI performed medicine or achieved general intelligence.
Implications for AI infrastructure and applied AI
Smaller models are attractive because they can require less memory and compute than frontier-scale systems. If narrow behavioral failures could be repaired through validated parameter edits, developers might extend the useful life of existing checkpoints without repeating costly training workflows. Potential applications could include reducing repetitive outputs, fixing specific formatting failures and improving task reliability.
Yet editing a model's weights introduces governance and reliability challenges. Every intervention changes the artifact being deployed, so versioning, test coverage and provenance are essential. A local improvement must be measured against safety behavior, calibration, multilingual performance and tasks outside the optimization target.
What this means for SEO and AI visibility
The story does not announce a Google ranking change or a new GEO optimization tactic. Its relevance to AI Search is more structural: the models used to summarize, retrieve and generate answers may be modified in targeted ways, potentially changing behavior without a conventional new-model release. That makes model versioning and repeatable evaluations important for anyone monitoring AI-generated answers.
AI visibility teams should not interpret a single benchmark improvement as proof that a model has become more accurate at citations or source attribution. Those capabilities need their own tests. Reliable measurement means tracking prompts, model versions, retrieval context and observed outputs rather than extrapolating from unrelated mathematical benchmarks.
What to watch next
The most useful next step would be publication of reproducible code or a detailed technical report showing the exact edits, benchmark definitions, held-out results and regression tests. Independent replication would help determine whether the reported gain was robust, whether it transfers to other checkpoints and how much of the effect came from stopping pathological repetition.
Bottom line: A reported GPT-6 Astra experiment suggests that an AI agent may be able to improve a smaller model through narrowly targeted weight changes. It is a provocative example of agent-assisted model engineering, but its results should remain labeled as reported until the methods and outcomes are independently validated.