A page can contain the clearest answer on the web and still have a basic problem in AI search: the system trying to use it may struggle to reach, render or interpret what the publisher considers obvious.
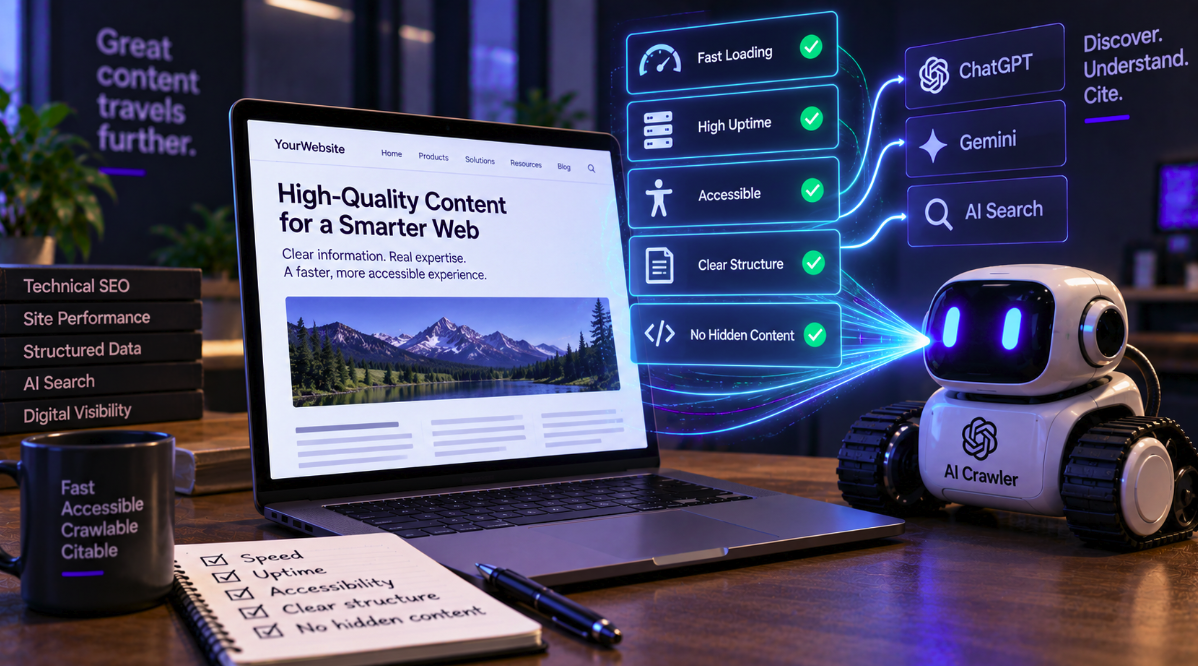
That is the central argument in a September 1 TechRadar Pro Perspectives article by Ayaz Ahmed Khan, senior director of engineering at Cloudways by DigitalOcean. Khan argues that website speed, uptime, accessibility, structured data, clear information architecture and the visibility of important content can affect how easily AI systems collect and understand information from a site.
The idea is technically plausible and aligns with a long-established principle of search engineering: information cannot be selected from a page if the relevant system cannot reliably access or parse it. But the distinction between accessibility and ranking is crucial. Khan’s article is an executive opinion piece, not documentation from Google, OpenAI, Anthropic or another AI provider confirming a new ranking signal. TechRadar itself labels the article as Opinion and notes that Perspectives contributors express their own views.
The useful takeaway is therefore narrower and more practical than “site speed is now an AI ranking factor.” Before asking why an AI system does not cite a page, publishers should verify that the page is technically easy to retrieve and understand in the first place.
Citation requires an information path before it requires a ranking theory
AI-search optimization discussions often begin with content: publish original research, answer questions clearly, demonstrate expertise and create material worth citing. Those are sensible goals, but they assume the system can actually acquire the information.
Khan describes a basic sequence in which an AI system needs to crawl a website, collect information and understand the content before it can include that information in an answer. If a page is slow, unavailable, confusingly structured or dependent on scripts that prevent important information from being exposed in an accessible form, the acquisition stage becomes harder.
That does not mean every AI product literally follows one identical crawl-and-rank pipeline. ChatGPT, Gemini, Perplexity, Claude and Google’s AI search experiences can use different models, retrieval systems, indexes and user-triggered browsing mechanisms. Some may rely partly on third-party search infrastructure or pre-existing indexes rather than a dedicated crawler fetching every source at answer time.
But the general constraint remains: somewhere in the system, the information has to become machine-accessible.
Speed matters first because requests have costs and limits
Khan argues that slow websites make AI access more difficult. It is tempting to turn that statement into a ranking claim, but the stronger engineering interpretation is about reliability and resource cost.
Every automated retrieval system operates with finite time, compute and network resources. A server that responds quickly and consistently is easier to fetch than one that times out, intermittently returns errors or takes an unusually long time to produce a document.
This is not unique to AI. Traditional search crawlers have always had to manage crawl resources and handle unreliable hosts. Human users also abandon slow pages. Website performance is therefore valuable even if no AI provider ever declares a specific speed threshold as a citation factor.
Cloudways naturally has a commercial interest in this argument because it sells managed hosting and infrastructure. Its own platform materials emphasize performance and reliability, including a 99.99% uptime claim. That vendor context should be kept separate from evidence about how an external AI engine ranks sources.
Uptime is less glamorous than GEO, but easier to reason about
Generative engine optimization has produced a growing vocabulary of tactics around entities, citations, answer formats and semantic relevance. Uptime is much less fashionable, but its relationship to retrieval is straightforward.
If an automated system requests a URL while the server is unavailable, the system cannot obtain the current document from that request. Repeated outages can therefore reduce the opportunities for any crawler or retrieval layer to see updates.
Cloudways’ engineering material repeatedly treats infrastructure stability as foundational. A recent Cloudways discussion of managed hosting and AI operations, for example, describes infrastructure as responsible for uptime, performance, security and scalability.
Again, that does not establish an “uptime ranking signal” inside ChatGPT or Gemini. It establishes something simpler: unavailable content cannot be fetched during the period in which it is unavailable.
JavaScript becomes a problem when it hides the information that matters
One of the most useful points in the TechRadar article concerns content buried behind scripts. Modern websites frequently use JavaScript for navigation, product interfaces, personalization and interactive applications. JavaScript itself is not inherently hostile to AI or search.
The risk appears when the meaningful information exists only after a complex client-side process that a particular crawler or retrieval system does not execute successfully. A human browser may display a complete product description after loading scripts and making additional API requests, while a simpler automated fetch may receive little more than an empty application shell.
For publishers, the practical question is not “Does this site use JavaScript?” It is “What does an automated client receive before and after rendering, and is the information we want discovered present in an accessible representation?”
Critical facts, product descriptions, article text, business information and navigation should not be unnecessarily dependent on fragile interactions if the goal is broad machine discoverability.
Clear information architecture reduces ambiguity
Khan also emphasizes page organization and clear information architecture. This is another area where technical SEO, accessibility and AI-readiness overlap without requiring a new ranking theory.
A well-structured site makes relationships easier to infer. Descriptive headings separate concepts. Logical navigation connects related topics. Stable URLs provide consistent locations for information. Internal links establish contextual relationships. Structured data can make specific entities and properties more explicit where an appropriate vocabulary exists.
None of these features guarantees citation. A beautifully structured page can still be irrelevant, inaccurate or less authoritative than competing sources. But clear structure reduces the amount of inference a machine has to perform to identify what the page is about and where important information lives.
That is useful whether the machine is a traditional search crawler, an accessibility tool, a browser agent or an AI retrieval system.
Accessibility is a machine-readability advantage without being an AI shortcut
Accessibility is especially interesting because many practices that improve a site for people using assistive technologies also make content more explicit in the document structure.
Semantic HTML, descriptive labels, meaningful headings, usable navigation and text alternatives reduce dependence on purely visual interpretation. Cloudways’ own web-accessibility guidance describes accessibility as an infrastructure concern and notes that JavaScript performance problems can make an otherwise accessible experience effectively unusable.
It would be a mistake, however, to claim that meeting accessibility standards automatically boosts AI citations. No evidence in Khan’s TechRadar piece establishes such a direct causal relationship.
The better argument is that accessible design often produces cleaner, more explicit information structures. That benefits users first and can also reduce unnecessary barriers for automated systems.
Structured data helps describe information, but it is not a citation token
Structured data is another item in Khan’s technical checklist. Schema markup can give machines explicit information about products, organizations, articles, authors, events and other entities. Search engines have long used supported structured data to understand pages and power rich results.
In AI-search discussions, that history sometimes leads to exaggerated claims that adding schema will make an LLM cite a page. There is no general evidence for that proposition.
Different AI systems may consume structured data differently, or not use a particular markup type at all. A system can also understand well-written visible text without relying on schema. Structured data should therefore be accurate, relevant and consistent with what users can see, not added as a speculative collection of keywords for AI bots.
Its strongest value is semantic clarity where machines are known to understand the vocabulary—not a guaranteed citation advantage.
Performance scores can hide real-world failure modes
Khan makes another useful distinction: a website can look fast in a controlled performance test and still fail when traffic spikes during a product launch, seasonal sale or viral event.
For AI visibility, that timing can matter. If a page becomes popular because a topic is suddenly newsworthy, the moment when retrieval demand is highest may also be the moment when infrastructure is under the most pressure.
A static laboratory score cannot fully describe that operational reality. Teams need server monitoring, error-rate data, latency measurements and capacity planning alongside front-end performance metrics.
This is one reason technical AI readiness should not be reduced to another score in a marketing dashboard. The relevant question is whether important information remains reliably retrievable under the conditions in which people and automated systems actually request it.
Test the machine-visible page, not just the browser screenshot
Publishers can turn the argument into a practical audit without pretending to know proprietary AI ranking algorithms.
Start by requesting important URLs with ordinary HTTP tools and inspect the returned HTML. Confirm that the server returns a successful status code and a sensible canonical URL. Check whether the main text and essential product or business information are present in the document or require multiple client-side interactions to appear.
Then test rendered output, navigation, structured data and accessibility. Review server logs to see which crawlers actually request the site and how the server responds to them. Look for 403 errors, 429 rate limits, 5xx failures, redirect loops and unusually slow response times.
These observations are more useful than assuming every bot can render the same page exactly as Chrome does.
Bot controls can accidentally undermine an AI visibility strategy
A site can be technically fast and still be inaccessible to a crawler because of deliberate or accidental blocking. Robots rules, firewall policies, bot-management services, authentication requirements and aggressive rate limits can all affect automated access.
That creates a strategic choice rather than a universally correct configuration. Some publishers may intentionally block particular AI crawlers because they do not want their content used in certain products. Others may want broad AI visibility and discover that their security stack is preventing the access they intended to allow.
The key is alignment. A company cannot simultaneously pursue maximum visibility in a system and unknowingly block the agents that system uses to obtain information, where direct crawler access is part of that system’s architecture.
Server logs and documented crawler identities are therefore essential. Do not disable security protections broadly in the hope of attracting AI citations; identify legitimate traffic and configure policies deliberately.
Technical accessibility is necessary in some pipelines, but never sufficient
The strongest correction to the “performance is the new defining metric” framing is that accessibility does not replace relevance, quality or trust.
A perfectly optimized server can deliver weak content in 100 milliseconds. A page can use impeccable semantic HTML while making unsupported claims. An AI system still has to decide whether the information answers the question and whether the source is worth using.
Khan acknowledges this by saying content quality, authority and trust still matter. His argument is that technical performance adds another layer because even excellent information has limited value if systems cannot reliably reach or interpret it.
That is a more defensible formulation than declaring infrastructure a new ranking factor.
AI visibility audits should separate retrieval from selection
When a brand is absent from AI answers, teams often jump directly to the selection question: why did the model choose a competitor instead?
A better diagnostic process separates at least two stages. First, could the system plausibly retrieve and understand the relevant information? Second, assuming it could, why might another source have been selected or cited?
The first stage is technical. It involves crawlability, server response, rendering, content exposure and document clarity. The second is competitive and editorial. It involves relevance, evidence, authority, freshness, corroboration and the particular retrieval behavior of the AI product.
Improving stage one cannot guarantee success at stage two. But diagnosing stage two before checking stage one can waste time optimizing content that the system never reliably sees.
Do not turn sensible engineering into another mythical ranking signal
The TechRadar article is valuable precisely because it pulls AI-search discussion back toward infrastructure. Websites are not abstract collections of content. They are software systems that must respond to requests, expose information and remain usable under load.
But the industry should resist converting every reasonable engineering practice into an undocumented “AI ranking factor.” Khan is a Cloudways engineering executive writing an opinion column. His company sells hosting and performance infrastructure. TechRadar explicitly states that the views are the author’s.
No new documentation from Google, OpenAI, Anthropic or Perplexity is presented to prove that a faster Core Web Vitals score, a specific uptime percentage or an accessibility grade directly increases citation probability.
Those caveats do not make the advice useless. They make the advice appropriately scoped.
Make the site easy to fetch before trying to make it famous in AI
For organizations pursuing AI visibility, the practical priority is straightforward. Publish information worth citing, but also make sure the underlying website is stable, fast enough to respond reliably, logically organized and accessible without unnecessary technical barriers.
Keep important facts visible in machine-readable page content. Use structured data where it accurately describes what users can see. Monitor uptime and server errors. Inspect logs. Understand which automated agents reach the site. Test what happens when JavaScript fails or when traffic surges.
None of that guarantees a mention in ChatGPT, Gemini, Perplexity, Claude or Google AI Overviews. There is no single AI ranking system, and technical accessibility is only one part of a much larger source-selection process.
But it answers a question that should come before every citation strategy: if your content deserves to be referenced, have you made it easy enough for the machines building those answers to actually reach and understand it?