

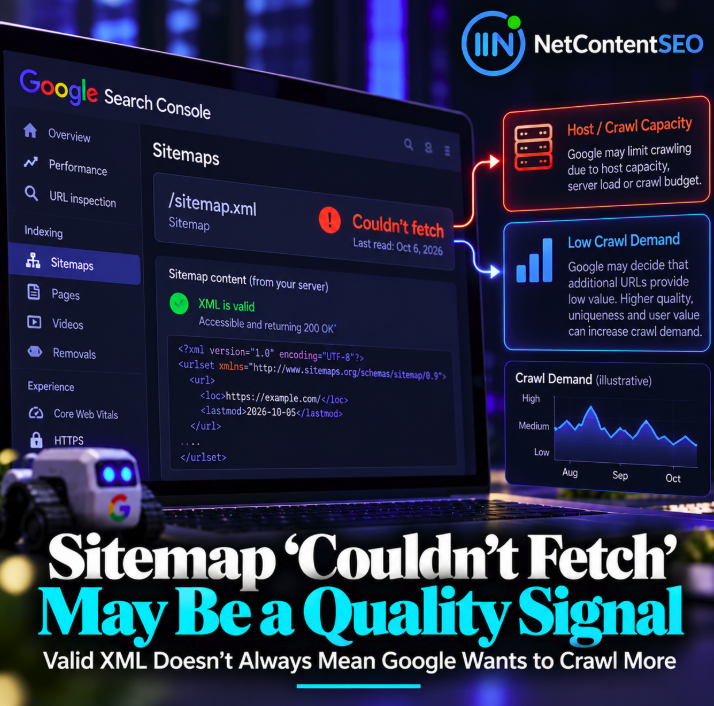

A “Couldn’t fetch” sitemap status in Google Search Console does not necessarily mean the XML file is broken, inaccessible or incorrectly submitted.
Google's Martin Splitt and John Mueller have clarified that a sitemap can be technically valid, publicly accessible and correctly referenced in robots.txt while Search Console still reports that Google could not fetch it.
The reason can be operational — such as limited host capacity — but it can also be connected to crawl demand: Google may simply decide that spending additional crawling resources on the site is not currently worthwhile.
That makes the Search Console message considerably more ambiguous than it appears.
Google acknowledges the message can be misleading
The clarification came during a discussion between Splitt and Mueller about sitemaps.
Splitt described the familiar scenario: the XML validates, the file is public, it is linked from robots.txt, yet Search Console continues to say “Couldn’t fetch.”
Mueller explained that the visible error does not expose every internal reason Google may have for not retrieving the file at that moment.
Reason one: Google may be constrained by the host
The first explanation is technical capacity.
Google's crawling systems calculate how much they can fetch from a hostname without overloading its infrastructure. If a server is slow, unstable or already receiving substantial crawler traffic, Google's available crawl capacity can fall.
In that situation, fetching a sitemap may simply lose priority against other crawling activity.
This aligns with Google's official crawl-budget documentation, which defines crawl capacity partly around server responsiveness, latency, server errors and rate-limiting signals.
Reason two: Google may not want to crawl more
The more important SEO clarification is that capacity is not the only limit.
Mueller explained that Google's systems can also determine that they do not need to fetch more URLs from a site because the expected value of doing so is low.
In other words, the crawler may technically be capable of retrieving the sitemap but have insufficient crawl demand to prioritize it.
Google's own crawl-budget documentation supports this broader model: Googlebot demand varies with factors including site size, update frequency, page quality and relevance compared with other sites.
This does not mean every “Couldn’t fetch” error is a quality penalty
The distinction is critical.
A “Couldn’t fetch” status is not proof that Google has assigned a site a formal quality penalty.
There can still be ordinary technical causes: server failures, DNS problems, access restrictions, unstable hosting, redirects, firewall rules or temporary crawling constraints.
What Google's clarification changes is the diagnostic model. Technical validity alone no longer rules out a crawl-demand explanation.
Why validating the XML is only step one
The usual troubleshooting sequence starts correctly: open the sitemap, verify that it returns 200 OK, validate the XML, check that Googlebot is not blocked and confirm that the sitemap URL is correct.
But if all those tests pass, repeatedly resubmitting the same unchanged sitemap may not address the actual issue.
The next investigation should move outward from the sitemap file to the site itself.
Crawl demand is a site-level problem
Google's crawl-budget documentation says its systems determine the set of URLs they both can and want to crawl.
For Googlebot, demand is influenced by several signals, including perceived URL inventory, popularity and the need to refresh documents.
Google also explicitly recommends improving content quality when trying to increase crawl budget, citing factors such as overall user value, uniqueness and service capability.
That means a technically perfect sitemap cannot force Google to create demand for thousands of URLs it does not consider worthwhile to revisit.
Duplicate and low-value inventories can consume the opportunity
Large inventories of duplicate, filtered, removed or otherwise unnecessary URLs can make crawling less efficient.
Google calls this the site's perceived inventory and identifies it as one of the crawl-demand factors site owners can influence most directly.
Faceted navigation, endless parameter combinations, thin location pages and automatically generated near-duplicates can therefore be relevant to a sitemap problem even when none of them appears inside the sitemap itself.
Quality improvements can change Google's assessment
Mueller also explained that Google's view is not permanent.
If a site substantially improves, Google's systems can reassess it and crawl more over time.
The operative word is substantially. Reformatting the XML, changing a sitemap filename or resubmitting it repeatedly does not solve a site whose broader content inventory offers little incremental value.
Google's people-first guidance similarly emphasizes original information, substantial coverage and content that genuinely satisfies its intended audience rather than large volumes created primarily to attract search traffic.
A better diagnostic workflow
When a technically valid sitemap shows “Couldn’t fetch,” the investigation should cover three layers.
First, sitemap accessibility: verify status codes, XML syntax, redirects, robots rules and whether Googlebot can retrieve the exact URL.
Second, host capacity: inspect server logs, response times, 5xx errors, 429 responses and crawl spikes. Google's infrastructure deliberately reduces crawling when a hostname cannot reliably sustain it.
Third, crawl demand and site quality: look at how many URLs Google already knows, how many are indexed, whether inventories are duplicated or thin, and whether new pages add meaningful information beyond existing pages.
Search Console's wording is the real problem
“Couldn’t fetch” sounds like a network statement: Google tried to retrieve a resource and failed.
But the explanation from Splitt and Mueller shows that the status can represent a broader set of crawler decisions.
A more descriptive interface might distinguish between an actual retrieval failure, host-capacity constraints and low crawl demand.
Search Console does not currently provide that level of diagnosis, so site owners have to infer the cause from logs and broader indexing behaviour.
This matters for “Discovered – currently not indexed” sites
The clarification is particularly relevant when a site already has large numbers of URLs sitting in discovery without progressing into regular crawling and indexing.
Google's crawl-budget documentation specifically identifies sites with a substantial share of URLs classified as Discovered – currently not indexed as one of the cases where crawl-budget analysis may be useful.
If that pattern appears together with a valid sitemap that Google intermittently refuses to fetch, the sitemap should not automatically be treated as the root cause.
A sitemap is a discovery signal, not an indexing command
This clarification reinforces a principle technical SEOs sometimes lose sight of.
A sitemap helps Google discover and prioritize URLs. It does not require Google to crawl them, and crawling does not guarantee indexing.
Google explicitly notes that not every crawled page will be indexed because pages are subsequently evaluated, consolidated and assessed for eligibility.
The same logic applies one step earlier: submitting a sitemap does not guarantee that Google will immediately spend resources retrieving and processing everything it advertises.
NetContentSEO take
“Couldn’t fetch” should no longer be diagnosed as a sitemap-only error.
If the XML is valid and Googlebot can access it, the investigation needs to include hostname capacity, crawl demand, duplicate URL inventories and the overall value Google may expect from crawling additional pages.
The important insight from Google is not that every sitemap error means “bad quality.” It is that technical accessibility and crawler willingness are two different things.
Fix the XML when the XML is broken. But when it is not, the real work may be improving the site Google would discover after fetching it.