

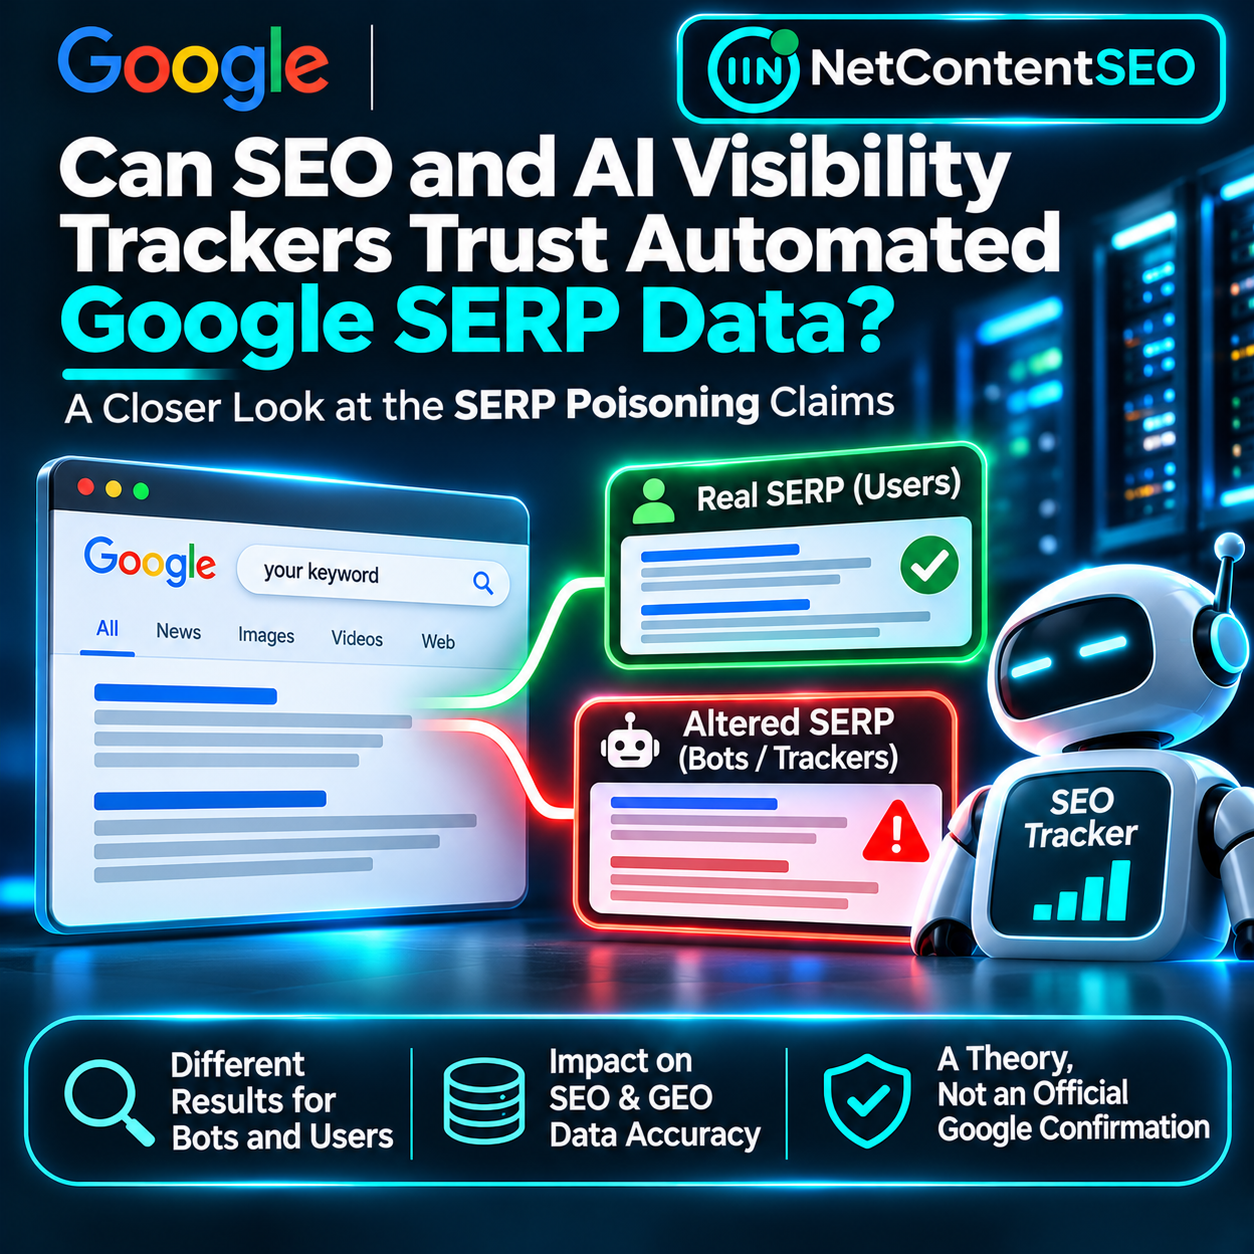

Can SEO and AI visibility trackers still trust the Google results they collect automatically? A growing body of evidence from search-data providers suggests that some automated requests are receiving search engine results pages (SERPs) that differ dramatically from established rankings. In a November 3, 2026 Search Engine Land analysis, Ryan Jones argues that these altered results could have consequences beyond rank tracking, potentially distorting the metrics publishers use to evaluate search performance.
The critical distinction is between observed data anomalies and their alleged cause. Multiple SEO platforms have documented abnormal results. Google has not publicly confirmed that it deliberately serves fabricated SERPs to trackers, how such a mechanism would operate, or whether it affects ordinary users.
What SEO platforms have actually observed
Since September 2026, rank-tracking providers have reported sudden changes in automated Google results that do not resemble normal ranking volatility. Instead of a familiar group of sites moving up or down, some collected SERPs contain largely unrelated pages or omit websites that had consistently appeared for the same queries. The anomalies can be intermittent, making them especially difficult to distinguish from genuine search changes when a tool collects only one snapshot.
Nozzle's published research, updated October 21, examined 29.9 million SERPs collected since September 13 across 53 countries and multiple device types. Using each keyword's earlier ranking history as a baseline, Nozzle classified 22.6% of the evaluated results as abnormal on page one or two, with a peak of 43.5% on September 30. These are findings within Nozzle's sample and classification methodology, not a measured percentage of all Google searches.
Ahrefs separately said that between 5% and 20% of results delivered by its data providers were affected, depending on the provider. Semrush also confirmed inaccurate results reaching automated SEO tools and said it had adjusted collection and validation procedures. Differences in sampling, location, device, data collection and detection rules mean these percentages should not be averaged into a single industry-wide rate.
What “SERP poisoning” means in this debate
Providers use the term SERP poisoning to describe plausible-looking search results that appear inconsistent with the rankings usually returned for a query. Unlike a CAPTCHA or an outright block, such a page can be accepted by an automated parser as genuine. A tracker might then report a dramatic ranking loss or an unexpected new competitor even though the underlying change was not visible to typical searchers.
But the word “poisoning” also implies intent. The observed abnormalities alone do not prove that Google deliberately generated misleading results as an anti-scraping defense. Google may employ measures against automated collection, and vendors have advanced that explanation, but the company's specific implementation and motives have not been independently established through an official technical disclosure.
Why this matters for AI visibility and GEO reporting
AI visibility measurement often relies on repeated automated observations of search interfaces: whether an AI Overview appears, which sources it cites, which domains rank organically nearby and how those features change over time. If the collected interface is not representative of what real users see, downstream metrics can become misleading.
For example, a tool could undercount AI Overviews, overstate the disappearance of a cited source or misclassify a domain's organic visibility. Nozzle's research found that suspected abnormal SERPs retained fewer of the previous page's AI Overview sources than normal comparisons. That is a useful warning about data reliability, but it does not establish that Google's AI systems changed their actual source-selection behavior for users.
The distinction is especially important for agencies selling AI visibility dashboards. A numerical citation share or visibility score may look precise while depending on unverified SERP samples. Data provenance, collection method and confidence levels should be part of the report rather than hidden behind a single percentage.
The proposed link to Search Console impressions and CTR
Jones's Search Engine Land analysis develops a further hypothesis. If data providers respond to suspicious SERPs by repeating the same query until multiple responses agree, their additional requests could increase automated search volume. Some of those requests might evade bot filtering and register as impressions in Google Search Console, potentially inflating impressions and depressing calculated click-through rates when no corresponding human clicks occur.
This is a plausible mechanism to investigate, not an established explanation for particular Search Console anomalies. The article does not demonstrate, with matched request logs and first-party Google accounting, that repeat scraping caused a measured increase in publishers' GSC impressions. Nor does it prove that suspected poisoned results are recorded in Search Console. Those are separate empirical questions.
Search Console metrics also depend on Google's counting and filtering rules, search-result presentation and reporting delays. A declining CTR can have many causes, including query mix, device shifts, SERP features and genuine changes in user behavior. Treating all impression growth as bot contamination would be as misleading as treating every rank-tracker fluctuation as a Google update.
Could ordinary Google users see altered results?
The analysis also raises the possibility of false positives in bot detection: legitimate users might occasionally be mistaken for automated clients. This concern is worth examining, but numerical examples based on hypothetical bot-detection error rates are scenarios, not measured counts of affected people. No verified public evidence establishes how many ordinary users, if any, have received the specific altered SERPs described by vendors.
How to audit a rank tracker or AI visibility dataset
First, compare unexpected ranking changes across independent providers rather than relying on a single scraper. Review the underlying SERP capture when available, including query, location, language, device, timestamp and page depth. Sudden wholesale replacement of previously stable results should trigger an anomaly flag, not an automatic conclusion that a site's SEO performance collapsed.
Second, compare rank-tracking signals with Google Search Console trends, but do not treat GSC as a perfect real-time ground truth for every question. Search Console can help establish whether impressions and clicks changed, while analytics and server logs can test whether user visits changed. Each source measures a different part of the process.
Third, ask vendors whether they detect anomalous SERPs, recollect suspicious samples, annotate corrected historical data and distinguish observed results from inferred rankings. Where an AI visibility product reports citation frequency or share of voice, request a clear denominator and a description of how failed or suspect captures are handled.
Finally, preserve raw evidence before reacting. A dashboard screenshot alone may be insufficient to explain whether a change came from a website, a Google interface experiment, collection infrastructure or data processing.
Why the industry needs better data provenance
The larger issue is not simply whether one anti-bot tactic exists. SEO and GEO products increasingly turn scraped observations into business decisions: content investment, competitor analysis, client reporting and attribution. That makes uncertainty in the collection layer an operational risk.
Jones argues that a public paid search-data API could reduce incentives for adversarial scraping. Such an API is a policy proposal, not a product Google has announced in response to this controversy. Even an official interface would need transparent definitions, sampling rules and coverage limitations to support credible measurement.
The takeaway for publishers and SEO teams
The available vendor studies support a serious warning: some automated Google SERP datasets have contained substantial anomalies since September 2026. They do not, by themselves, prove a Google-directed deception campaign or establish that ordinary searchers and Search Console metrics have been affected in the ways proposed by the November 3 analysis.
For SEO and AI Search measurement, the practical response is to improve verification, annotate uncertainty and avoid converting unvalidated observations into definitive ranking or visibility claims. When the data collection layer becomes unstable, a precise-looking SEO or GEO score can be precisely wrong.
Sources
- Ryan Jones, Search Engine Land, “Is Google poisoning more than just search results?”, November 3, 2026
- Nozzle, “Poisoned Google SERPs,” updated October 21, 2026
- Search Engine Land, “Semrush confirms ‘poisoned’ Google results are impacting SEO tools,” October 27, 2026
- PPC Land, reporting Ahrefs' October 22 statement