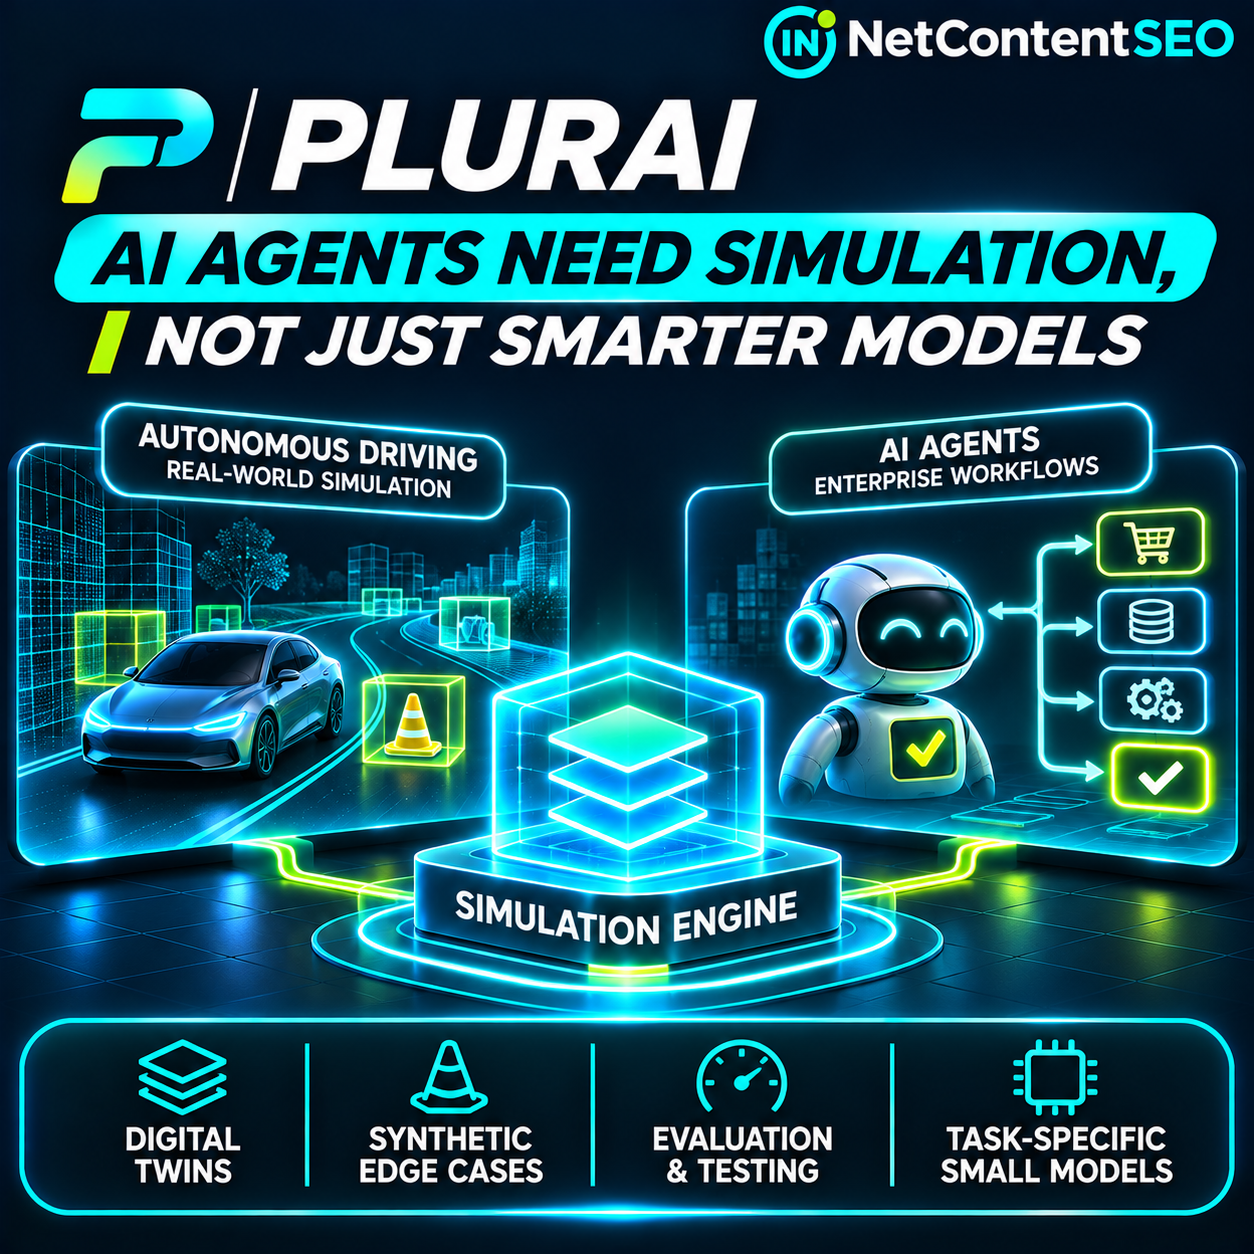
AI agents are becoming more capable at browsing websites, calling tools and completing multi-step workflows. But a successful demo is not proof that an agent can reliably handle the messy exceptions of a real business. Plurai, an AI reliability startup founded by researchers with autonomous-driving experience, is betting that the missing ingredient is a simulation environment where agents can fail safely before they reach customers.
On November 11, 2026, TechCrunch reported that Plurai raised $13 million in seed funding, led by Team8 with participation from U&I, Velocity and Mercer. The company wants to apply lessons from autonomous vehicles to software agents: recreate realistic operating conditions, generate difficult scenarios, evaluate failures and improve the system before deployment.
For SEO and AI Search professionals, the story matters because discovery is becoming only the first step in a longer journey. An assistant may find a hotel, retailer or service provider, but the business outcome depends on whether it can obey policies, retrieve accurate information and complete an authorized action without introducing costly errors.
What Plurai announced on November 11
TechCrunch describes Plurai as a company building a simulation layer for enterprise AI agents. Its co-founders, Ilan Kadar and Elad Levi, previously worked on autonomous-vehicle technology at Nexar. Plurai's official company profile identifies Kadar as CEO and Levi as CTO, and details their machine-learning and autonomous-systems backgrounds.
According to the reporting, Plurai can construct a digital representation of a company's software environment, including knowledge sources and the tools available to an agent. It then generates scenarios designed to expose where an agent may violate policies, misunderstand a request or fail when several systems must work together. The company also aims to use the resulting data to adapt smaller open-weight models to particular enterprise tasks.
The $13 million round is a financing announcement, not evidence that the technology has independently solved agent reliability. The company's product claims and performance comparisons require careful interpretation.
Why autonomous driving is a useful analogy
Self-driving systems operate in environments that cannot be fully predicted from a single test route. Even if a vehicle performs well in ordinary traffic, rare combinations of weather, road conditions and human behavior can create dangerous failures. Developers use simulations to exercise difficult cases repeatedly without waiting for those exact situations to occur on public roads.
AI agents have a related problem in digital environments. A customer can ask an assistant to book travel while also imposing a spending limit, change a reservation after a partial payment, or request an answer that requires combining information from several systems. The agent may perform each simple step correctly but still fail the full workflow.
Plurai's premise is that an enterprise should simulate these combinations before granting an agent broad production responsibilities. The analogy is useful for testing methodology, but software agents and autonomous vehicles have different safety requirements, failure modes and regulatory contexts. The success of one field does not automatically validate a product in the other.
How Plurai's simulation approach works
Plurai describes its offering as a simulation-driven platform for agent evaluation, protection and optimization. Its official website emphasizes realistic multi-turn interactions, business-specific policies, edge-case coverage and evaluation workflows that can be incorporated into development and deployment processes.
In the approach described by TechCrunch, the platform models a company's knowledge base and tool environment, maps possible agent paths, generates synthetic scenarios and uses the outcomes to identify failures. The intended loop is to test an agent, analyze mistakes, improve instructions or safeguards, and rerun relevant scenarios before production.
A crucial limitation is that a digital twin is a representation, not the real business. If it omits a payment exception, a new product policy or a confusing customer interaction, an agent can pass every simulated test and still fail in production. Scenario coverage, fidelity and continuous updates are therefore as important as the headline number of test cases.
The edge cases that break agent workflows
Consider an AI travel assistant asked to book a hotel for a business trip. A basic test might confirm that it can search properties and identify an available room. A realistic test should also examine what happens when the preferred hotel exceeds the travel budget, taxes push the total over a spending limit, a rate becomes unavailable between search and booking, or the user changes the dates after approval.
In commerce, an agent might need to verify stock, shipping eligibility and refund conditions across separate systems. In customer support, a conversation may extend over many turns, with contradictory user instructions and outdated documentation. These cases can expose failures in context management, tool selection, permission checks and state handling.
These are illustrative scenarios showing why simulation matters; they are not published examples of Plurai customer failures or independently verified test outcomes.
Why Plurai also wants smaller, specialized models
Simulation is only one part of Plurai's strategy. TechCrunch reports that the company wants to use evaluation data to train or adapt small, open-weight language models for narrow enterprise needs. The idea is to reserve expensive general-purpose models for tasks that need broad reasoning, while smaller specialized models handle repeated checks or well-defined decisions.
Examples might include classifying whether a request violates a refund policy, checking whether an agent response contains prohibited personal information, or judging whether a workflow followed a required approval sequence. These are examples of possible specialist functions, not an exhaustive list of Plurai's supported models.
Plurai says that tests with Nvidia and Nebius showed tailored models outperforming some mid-tier frontier models at substantially lower cost. Its own website also publishes speed, failure-reduction and cost claims. Those figures should be treated as company-reported results until the test conditions, baselines and independent replication are available. A smaller model that performs well on one company's policy dataset may not generalize to a different business.
Reliability is a system property, not a model leaderboard score
Agent performance depends on more than the underlying language model. An end-to-end workflow may require retrieval, planning, several tool calls, authentication, policy checks, user confirmation and state recovery. Failure at any step can prevent the intended outcome even when the model produces fluent text.
This suggests a different evaluation unit: the successfully completed, policy-compliant task. A system should not receive full credit for locating a booking page if it cannot complete the booking safely. Nor should it be counted as successful if it executes the transaction twice or exceeds a customer's authorized budget.
Useful metrics include end-to-end task success, policy-violation rate, human intervention rate, incorrect tool calls, duplicate actions, latency, recovery after tool failures and total cost per successful task. These measures can reveal tradeoffs hidden by generic model benchmarks.
What this changes for AI Search and GEO
Generative Engine Optimization has often been discussed in terms of citations, brand mentions and visibility in AI-generated answers. Those remain useful signals, but agents that can take action introduce a separate question: can the business be used reliably after it is discovered?
A hotel might appear in an assistant's recommendations but lack a supported way for that assistant to check live availability. A retailer might expose a product feed while providing inconsistent inventory data. A local service provider might be discoverable but require a complex handoff to request an appointment. In each case, visibility and transaction completion are different problems.
Simulation can help teams test the journey from intent to action. For example, a business could evaluate whether an agent retrieves the correct policy, selects the right product, respects geographic restrictions and requests confirmation before an irreversible operation.
None of this establishes that using Plurai improves Google rankings, ChatGPT citations or any search engine's recommendation algorithm. The connection to SEO and GEO is an operational implication of agent-enabled discovery, not a confirmed ranking signal.
A practical test plan for agentic commerce and service discovery
- Define a real customer objective. Examples include checking stock, requesting a quote, confirming a booking or obtaining an accurate refund explanation.
- List the required systems. Identify which tools, APIs, knowledge sources and permissions the agent needs.
- Document non-negotiable policies. Include price limits, privacy requirements, authorization rules and actions requiring explicit consent.
- Create ordinary and adversarial scenarios. Test unavailable inventory, conflicting instructions, stale data, API failures and repeated requests.
- Evaluate the complete task. Score not just the final answer but every consequential tool call and resulting state change.
- Compare model configurations. Test frontier models, smaller specialists and hybrid approaches against the same workload.
- Measure cost per successful task. Include inference, tool use, evaluation, human review and recovery costs.
- Use human approval for sensitive actions. Payments, cancellations and account changes should have appropriate safeguards.
- Monitor production drift. Update scenarios when policies, APIs, products or customer behavior change.
- Separate discovery from execution metrics. Track AI referrals or mentions independently from tool-call reliability and completed transactions.
How should companies evaluate Plurai's claims?
Prospective customers should ask whether tests reproduce their own business policies and data flows. They should request a clear description of the evaluation dataset, how synthetic scenarios are validated, whether the same scenarios were used during model tuning, and which baseline models were compared.
They should also test how the platform handles sensitive business data, access to internal tools, audit logs and changes in production policies. A meaningful proof of concept should include previously unseen scenarios and report both successful and failed cases, not just a curated demonstration.
Lower inference cost is valuable only if the resulting system maintains the required accuracy and safety. A cheap model that causes more manual interventions or transaction errors can be more expensive at the business level.
What is confirmed, and what remains unproven?
Confirmed through reporting and company materials: Plurai is developing simulation-based evaluation and optimization for AI agents; its founders have autonomous-driving backgrounds; TechCrunch reported a $13 million seed round on November 11, 2026; and the company markets synthetic scenario generation, guardrails and task-specific small models.
Company-reported, not independently established here: specific reductions in cost or failure rates, superiority to particular frontier models and the extent of production improvements from tailored models.
Not demonstrated: universal reliability across industries, elimination of human oversight, a direct increase in AI Search citations or a measurable SEO ranking benefit.
Frequently asked questions
What is Plurai?
Plurai is an AI-agent reliability company focused on simulation, evaluation, guardrails and optimization, including smaller task-specific models.
How much funding did Plurai announce?
TechCrunch reported a $13 million seed funding round on November 11, 2026, led by Team8 with participation from U&I, Velocity and Mercer.
What does autonomous driving have to do with AI agents?
Both involve probabilistic systems facing unexpected situations. Simulation can expose edge cases before deployment, although the two domains have different technical and safety requirements.
What is a digital twin for an AI agent?
In this context, it is a simulated representation of the systems, knowledge and tools an agent will encounter, used to test workflows without causing real production effects.
Does synthetic data guarantee reliable agents?
No. Synthetic data can broaden test coverage but may miss real-world situations or reproduce flawed assumptions. Independent testing and production monitoring remain necessary.
Why use small language models instead of the biggest model?
For narrowly defined tasks, a tailored smaller model may offer lower cost and latency. Whether it preserves adequate quality must be measured for the specific workload.
Does Plurai improve SEO or AI visibility?
There is no verified direct ranking or citation benefit. Its relevance is to the reliability of agents that may interact with businesses after discovering them.
What should an enterprise measure first?
Start with successful, policy-compliant task completion, then measure error rates, human escalation, latency and total cost per successful outcome.
The bottom line
Plurai is betting that the next major advance in enterprise agents will not come from model intelligence alone. It will come from exposing systems to realistic failures, measuring what goes wrong and continuously improving the combination of models, tools and business rules.
For SEO and AI Search, the broader lesson is clear: being recommended by an assistant and being usable by an assistant are distinct competitive capabilities. As more discovery journeys include tool calls and transactions, the reliability of that second step may matter as much to business outcomes as the visibility of the first.