

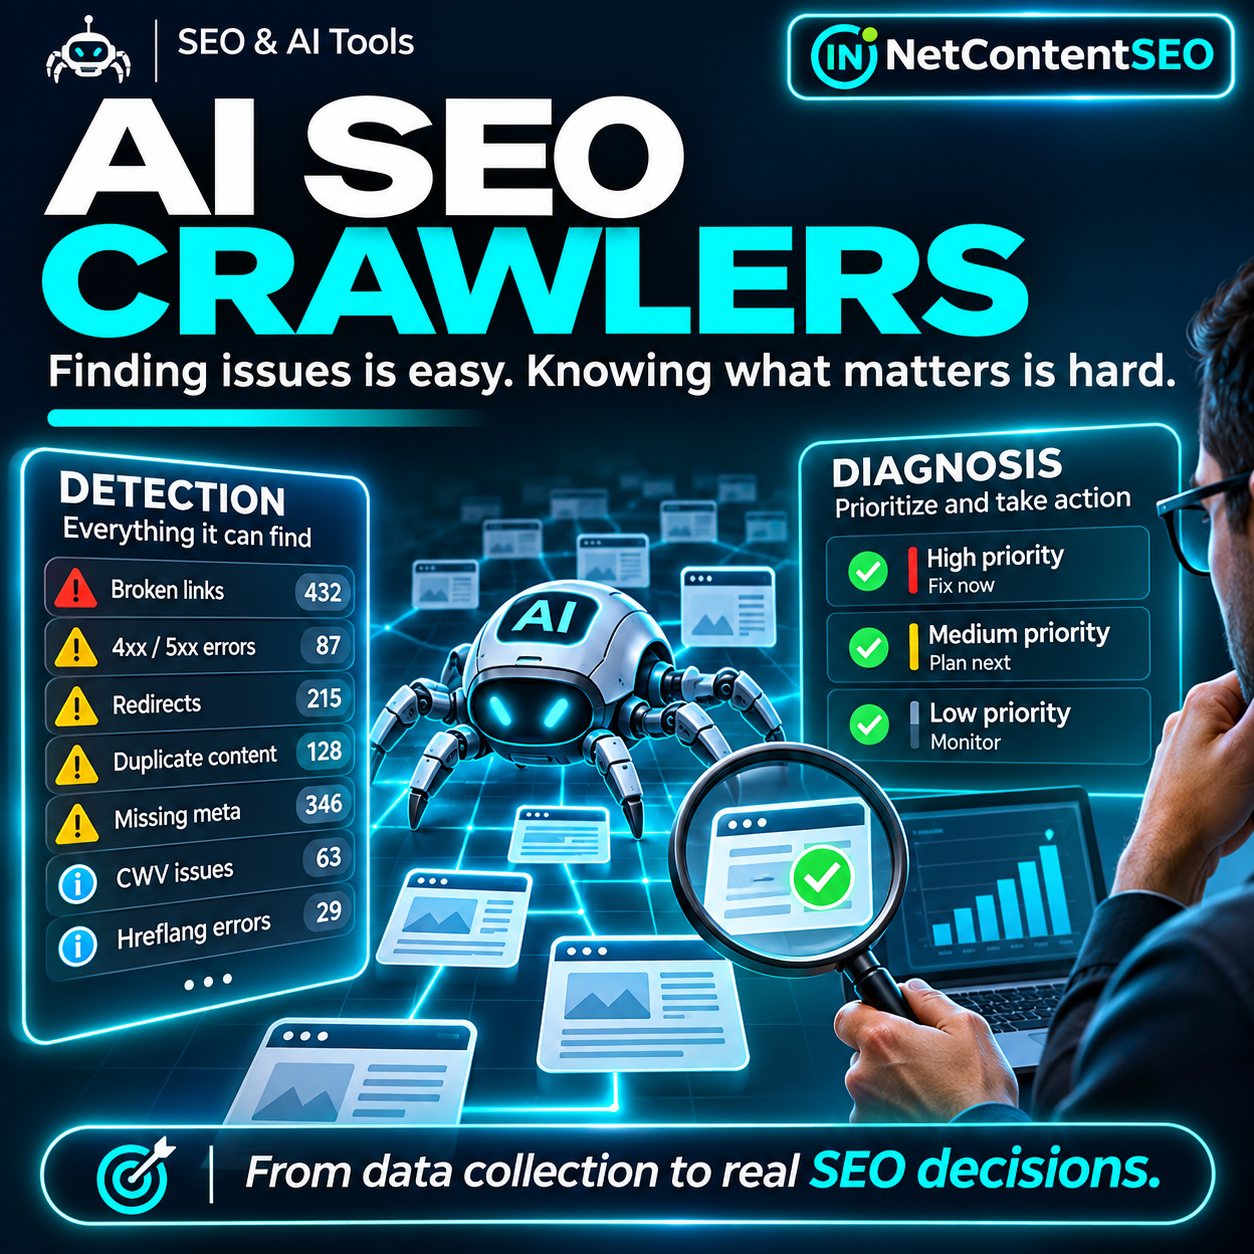

November 5, 2026. AI-assisted coding has made it easier than ever to build a website crawler. A developer can ask an assistant to fetch URLs, extract metadata, follow internal links and generate a technical SEO report. But a crawler that collects information is not automatically a tool that understands which problems matter.
That distinction is at the center of a recent r/TechSEO discussion in which Google's John Mueller cautioned against assuming that building a crawler is equivalent to replacing a maintained technical SEO platform. His argument is not that custom tools are impossible or useless. It is that interpreting findings, maintaining the software and knowing when to act require experience.
Mueller's comments were visible in a screenshot of the discussion provided for this article. The original Reddit comment URL could not be independently fetched during verification; therefore, the account below is based on that supplied screenshot, while the technical explanations are checked against Google's published documentation.
What John Mueller actually said
Mueller acknowledged that developers can create their own technical SEO tools, including crawlers built with Python and AI assistance. But he urged caution: unless someone knows what they are doing, a working, documented and maintained tool may save considerable time and effort.
He also emphasized a subtler problem. A crawler does not provide a magical list of technical SEO issues that necessarily require fixing. It produces observations. Users still need to understand what those observations mean, decide which ones matter, and find reliable documentation or expert support when something is unclear.
Mueller also recognized the affordability problem: a global software price can be difficult for professionals in lower-income markets. He suggested that some smaller tool vendors may be open to discussing pricing arrangements, while explicitly making no promises.
In the screenshot, another Reddit participant dismissed his detailed comment with “Thank you ChatGPT,” and Mueller replied “Lol.” That exchange is amusing, but it should not obscure the technical substance of his message. There is no evidence in the screenshot that he was making a new Google policy announcement, discouraging AI development outright, or identifying a particular crawler as unsafe.
Why building a crawler is not the same as building an SEO audit
A basic crawler requests pages and records what it sees. It can collect status codes, titles, meta robots directives, canonical hints, headings, internal links, redirects, structured data and sitemap references. That is useful. But the next stage—interpreting the evidence—depends on site architecture, business goals, search engine behavior and the consequences of making a change.
For example, a report may list 400 URLs returning a 404 status. That number is not enough to decide whether there is a serious problem. Are these old URLs that have been intentionally retired? Are they linked from important navigation pages? Are they referenced by current XML sitemaps? Do they receive traffic or backlinks? Are they broken internal links that prevent users from reaching valuable content?
A useful audit distinguishes these cases. The first may need no action; the others may warrant repairing links, restoring pages or implementing appropriate redirects. The correct decision comes from context, not the number 400.
Detection, diagnosis and prioritization are three different jobs
| Stage | What it does | What it cannot establish alone |
|---|---|---|
| Detection | Finds observable conditions such as 404 responses, redirect chains or missing tags | Whether the condition is harmful |
| Diagnosis | Tests likely causes against crawl paths, indexing rules, templates and logs | Whether a proposed fix is worth its cost |
| Prioritization | Ranks confirmed problems by impact, scope, confidence and effort | Guaranteed ranking gains |
These stages should remain separate in both software and reporting. A tool may be highly accurate at detecting a missing meta description and still be wrong to classify every instance as critical. Similarly, a canonical mismatch may require careful investigation rather than an automatic replacement of the tag.
Google's How Search Works documentation separates crawling, indexing and serving results. Pages can be discovered but not crawled, crawled but not indexed, or indexed but not shown for a particular query. A third-party crawler cannot infer all three states merely by downloading HTML.
Five examples where an AI-built crawler can mislead you
1. A page has no meta description
A crawler flags the absence of a description. That is a valid observation, but it does not prove an indexing error or a ranking penalty. The next step is to assess whether the page is important, whether the snippet is misleading, and whether a custom description would improve the result. Fixing thousands of low-value descriptions may be less useful than improving a small set of important landing pages.
2. A canonical URL differs from the current URL
That may be intentional on duplicate or parameterized pages. A crawler should compare canonical hints, redirects, internal links, content similarity and indexability before labeling the relationship incorrect. Google's canonical selection is algorithmic, and a declared canonical is a signal rather than a command.
3. An XML sitemap contains only some site URLs
A sitemap is a discovery aid, not necessarily a complete inventory of every crawlable page. A crawler should distinguish sitemap-listed URLs from internally discovered pages, verify the sitemap entries and identify whether important indexable URLs are omitted. It should not automatically classify every URL absent from a sitemap as an SEO error.
4. A JavaScript page appears empty
A simple HTTP crawler may see little content in initial HTML, while a rendering-capable browser can execute JavaScript and expose the actual page. Google's documentation states that Googlebot renders pages using a recent version of Chrome. A diagnostic tool should make its own rendering limitations explicit rather than claim Google necessarily sees the same empty page.
5. A blocked URL appears in the crawl report
Robots.txt and noindex are not interchangeable. Robots.txt controls crawler access; noindex can prevent indexing when the crawler is allowed to see the directive. If a page is blocked by robots.txt, a third-party crawler may not be able to inspect its content or its meta robots rules. The correct remedy depends on the intended visibility of that URL.
What a reliable AI SEO crawler should actually do
First, it should disclose what it scanned: the starting URL, crawl date, user agent, robots policy, rendering mode, discovered internal pages, excluded URLs, timeout settings and coverage limitations. A report that claims a full-site audit while sampling only a small number of pages is not equivalent to a comprehensive crawl.
Second, it should retain the evidence behind every finding: the affected URL, HTTP response, relevant HTML or header, link source, redirect path and the rule used to classify the issue. Evidence allows an SEO specialist to reproduce the finding and challenge a false positive.
Third, it should separate confirmed technical conditions from inferred SEO impact. A 500 response observed during a request is a confirmed response. A claim that it caused a search traffic decline requires further evidence from logs, Search Console and timing.
Fourth, it should support recrawls and comparisons. A report becomes more useful when it shows whether an issue is new, recurring or resolved and whether the affected pages are important. Software updates must account for changes in browsers, HTML, search engine documentation and site architectures.
Finally, an AI explanation layer should cite the actual crawl evidence and relevant documentation. It should be allowed to say “uncertain,” “requires manual verification” or “not enough data.” Generating confident recommendations from incomplete crawl data is a product defect, not an advanced feature.
Should you build your own crawler or buy an established tool?
The choice depends on the work. A custom crawler can be appropriate when the team has unusual URL structures, proprietary business rules, internal access requirements or a specific repeatable diagnostic problem. It can also be valuable as an educational project and as a complement to established tools.
Buying an established platform can make more sense when you need a broad collection of tested checks, browser rendering, scheduled audits, support, documentation, collaboration and predictable maintenance. Those benefits have costs, and not every team needs them.
A hybrid approach is often practical: use a maintained crawler for general discovery, a custom script for unusual checks, and an AI assistant to explain evidence or help draft investigation steps. The AI layer should not silently override confirmed findings or present guesses as Google's internal decisions.
How to evaluate a crawler before trusting its recommendations
- Test on a known website. Create or select a staging site with intentional redirects, broken links, canonical variations, noindex pages and JavaScript-rendered content. Compare the crawler's output with manual checks.
- Measure coverage. Count internal HTML pages discovered and successfully fetched. Distinguish all-page crawling from limited sitemap sampling, and document any explicit crawl cap.
- Review false positives. Take a representative sample of critical, medium and low-priority findings and check whether each condition is real and actionable.
- Verify technical assumptions. Check whether the tool respects robots directives, handles redirects, normalizes URLs consistently, records failures and distinguishes source HTML from rendered HTML.
- Inspect prioritization. Confirm that high-priority issues affect important pages and have plausible user or search consequences. Do not accept severity labels without evidence.
- Test recrawls. Fix a known issue and verify that the next report reflects the change without generating contradictory findings.
- Evaluate maintenance. Determine who updates rules, dependencies and documentation when browser behavior or search guidance changes.
A practical priority model for technical SEO findings
A useful internal scoring model can combine impact, affected-page importance, scope, confidence and effort. For example, assign each factor a documented 1–5 scale, then review the highest-impact, highest-confidence findings first. Such a score is a project-management heuristic, not a Google ranking metric.
A sitewide accidental noindex directive on important pages deserves immediate attention. A handful of missing descriptions on low-value pages generally does not. A redirect loop in the checkout path can be urgent for users and revenue, even if it is not primarily a search issue. Good prioritization considers business impact as well as technical SEO.
For large sites, group findings by template and root cause. Fixing one broken navigation component may resolve thousands of affected links. Treating each URL as a separate ticket would waste time and obscure the actual problem.
What about RAG and LLM-powered SEO audits?
Retrieval-augmented generation (RAG) can help an assistant consult current search documentation, internal audit rules and previously verified incidents before explaining a finding. It can improve traceability if the retrieved sources are relevant and the model accurately distinguishes them from site-specific evidence.
RAG does not make a crawler omniscient. It cannot replace a missing HTTP response, infer Googlebot's private decisions, or prove that a recommended change will improve rankings. A robust system should preserve three layers: observed crawl facts, retrieved documentation and the model's interpretation.
For example, a RAG-assisted audit might observe that a page returns 200, contains noindex and appears in a submitted sitemap. It can cite Google's documentation on noindex and explain that the signals conflict with an apparent indexing objective. But it must ask whether the page was intentionally excluded before recommending removal of noindex.
Does this mean AI cannot replace technical SEO tools?
No. Mueller's point, as represented in the supplied Reddit screenshot, is about reliability and interpretation, not a categorical prohibition on AI-built software. AI coding can accelerate development and help specialists build focused diagnostics. The challenge is making the output trustworthy enough to support decisions.
The strongest technical SEO tool is not necessarily the one that finds the most warnings. It is the one that helps the user understand which conditions are real, which matter and what evidence supports the next action.
Frequently asked questions
Can ChatGPT or another AI build an SEO crawler?
Yes. AI coding assistants can help write crawlers and audit scripts. Production use still requires testing, safe crawling behavior, maintenance and technical SEO expertise.
Is a custom crawler better than Screaming Frog or other established tools?
Not inherently. A custom crawler may be better for a narrow proprietary task; a maintained platform may offer broader checks, documentation and support. Evaluate the actual requirements and total maintenance cost.
Can a crawler tell whether Google indexed a page?
Not reliably from HTML alone. It can assess indexability conditions, but Google's indexing status is a separate process. Use Google Search Console and other appropriate evidence when investigating indexing.
Are all technical SEO warnings worth fixing?
No. Some are intentional conditions, minor improvements or false positives. Prioritize confirmed problems that affect important content, users or search access.
Will RAG make an AI SEO audit accurate?
RAG can help ground explanations in documentation, but accuracy still depends on the crawl evidence, retrieval quality, rules and human verification.
Did John Mueller announce a Google ranking change?
No. The discussion concerned the practical value and limitations of building technical SEO tools, not a change to Google's ranking systems.
The takeaway: diagnosis is the product
AI is lowering the cost of writing crawler code. That is a genuine opportunity for independent developers and SEO teams. But the value of an audit is not the number of URLs fetched or warnings generated. It is the ability to distinguish meaningful problems from noise, explain why they matter and support a decision that can be tested.
Mueller's warning deserves to be read in that spirit: build your own tools if they solve a real problem, but do not confuse a working crawler with a reliable technical SEO diagnosis. Collecting data is increasingly cheap. Interpreting it responsibly remains the difficult part.
Sources and verification
- r/TechSEO discussion, November 2026 — John Mueller's remarks visible in a screenshot supplied to the editor; live comment could not be fetched independently.
- Google Search Central: How Search Works — crawling, indexing and serving distinctions.
- Google Search Central: Troubleshoot crawling errors — investigation workflow and evidence.
- Google Search Central: Technical requirements — minimum indexability conditions.
- Google Search Central: Maintaining your website's SEO — JavaScript, robots, sitemaps and internationalization.