

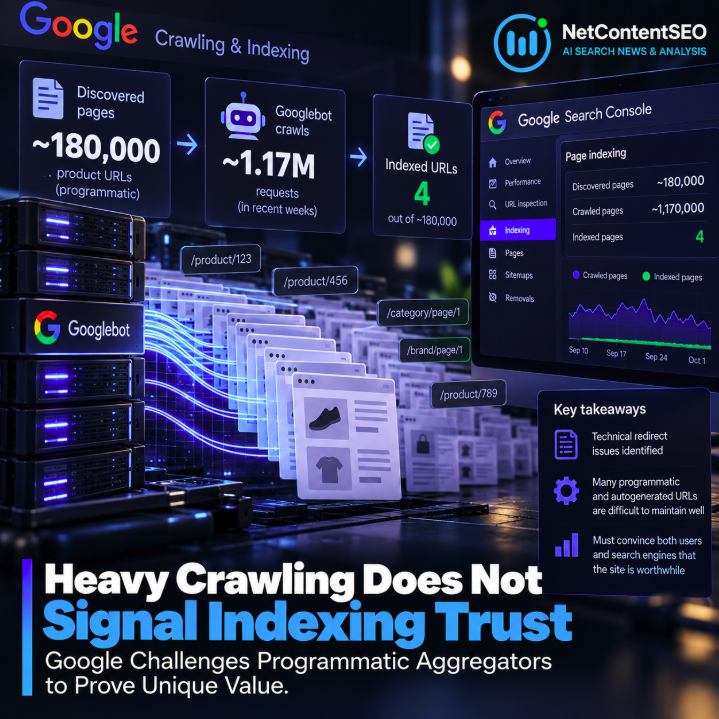

A large product aggregator can receive enormous amounts of Googlebot activity and still have almost nothing indexed. A recent case discussed by Google's John Mueller is a sharp reminder that crawl volume is not evidence that Google considers a site worthy of indexing.
The site in question reported roughly 180,000 pages and about 1.17 million Googlebot crawl requests over recent weeks, yet Search Console showed only four indexed URLs. Even the homepage was reportedly absent from Google's index.
Mueller's response focused on two separate problems: unresolved technical issues and the much harder challenge of demonstrating value when operating a very large programmatic product aggregator.
Googlebot crawling a URL does not mean Google wants to index it
The case is an extreme example of a distinction that is easy to overlook in Search Console.
Discovery, crawling, rendering, indexing and ranking are different stages. Google may crawl URLs to understand what they contain, reassess previous decisions, discover links or detect changes without ultimately selecting those pages for the index.
That means a graph showing rising crawl requests cannot safely be interpreted as increasing indexing trust or an imminent expansion in indexed pages.
Mueller first identified a technical problem
Before discussing content strategy, Mueller pointed to a concrete technical issue: several URLs already associated with the site were redirecting to the homepage.
He said this suggested there were still significant technical problems that needed to be resolved.
That matters because large-scale sites amplify technical mistakes. Redirect patterns, canonicalization, duplicate URL generation, internal linking and status-code errors can affect thousands of URLs simultaneously.
But fixing redirects does not solve the larger challenge
Mueller then addressed the site's underlying model.
He characterized it as another large product aggregator containing a large number of URLs with apparently programmatic, autogenerated content. His broader point was that this type of site is difficult to build and maintain well, and that convincing both search engines and users that it is worthwhile will be difficult.
This is not a new Google rule banning programmatic SEO, and Mueller was responding to a specific site rather than announcing an algorithm update.
But the statement reinforces a recurring principle: generating URLs at scale does not itself establish why those URLs deserve to exist in Search.
180,000 URLs create a value problem as well as a crawl problem
Programmatic publishing changes the economics of content creation. Once templates and datasets are connected, creating another 10,000 pages may be technically inexpensive.
For a search engine, however, every additional URL still competes for crawling, indexing, retrieval and ranking resources.
The important question therefore becomes whether each generated page contributes something sufficiently useful and differentiated for a user searching for that specific result.
A product aggregator that reproduces information already available from manufacturers, merchants or larger marketplaces has a particularly difficult task. Its value must come from what it adds: comparison, normalization, historical data, availability, analysis, filtering, original research, unique inventory relationships or another capability users cannot obtain as easily from the underlying sources.
Indexing at scale is an outcome, not an entitlement
The case also challenges a common assumption in large-site SEO: if URLs are technically indexable and Googlebot is crawling them, indexing should eventually follow.
Google does not guarantee that outcome.
Technical accessibility is necessary, but it is not sufficient. Search systems still need to decide whether a URL is useful enough, distinct enough and reliable enough to retain in the searchable corpus.
Four indexed URLs out of roughly 180,000 is therefore not simply a “crawl budget” story. The reported 1.17 million crawl requests show that Google was capable of accessing a substantial amount of the site. The bottleneck appears farther downstream.
Programmatic sites should measure uniqueness before URL count
For large aggregators, the useful KPI is not how many pages the CMS can generate.
Teams should instead ask how many page types provide genuinely distinct information, how much content changes from one generated URL to another, whether the page satisfies a unique search intent and whether users have a reason to prefer the aggregator over the original data source.
Those questions should be answered before multiplying a template across hundreds of thousands of URLs.
Technical hygiene still comes first
Mueller's redirect observation is equally important because quality analysis becomes unreliable when the site's technical state is unstable.
Large programmatic sites should audit redirect destinations, canonical targets, HTTP status codes, sitemap consistency, internal linking, duplicate parameter URLs and the relationship between submitted, crawled and indexed URLs.
Only after those layers are clean does it become easier to isolate whether the remaining indexing gap reflects content selection rather than technical confusion.
The NetContentSEO takeaway
Crawling is not indexing trust.
A million Googlebot requests can coexist with almost no indexed content because crawl activity tells us that Google is fetching URLs, not that Google has decided those URLs deserve persistent inclusion in Search.
Mueller's response is particularly relevant as AI makes programmatic publishing dramatically cheaper. The cost of generating 180,000 pages may continue to fall, but the burden of demonstrating why those pages are useful does not disappear.
For large aggregators, the competitive advantage will increasingly come from unique information and user utility, not from the ability to manufacture the largest possible URL inventory.