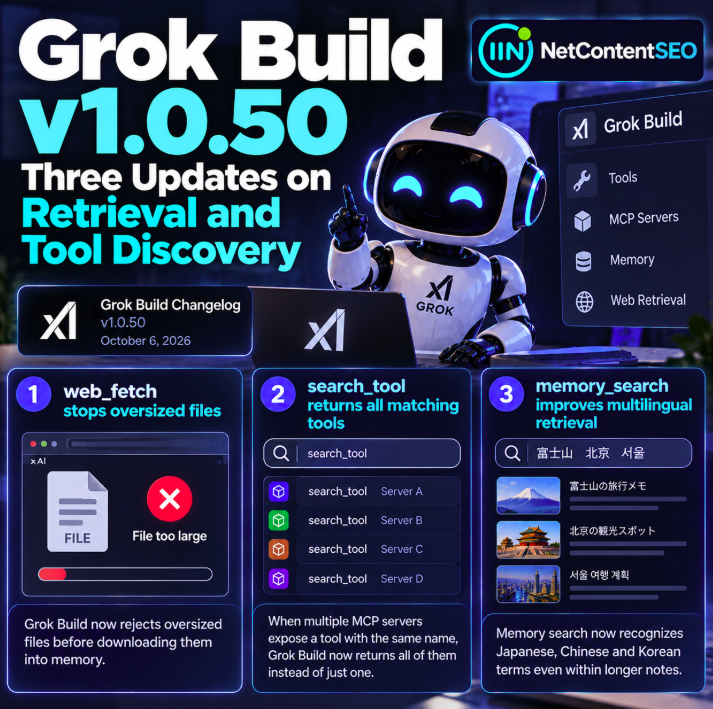
xAI's Grok Build v1.0.50, dated October 6, 2026, changes how its web_fetch tool handles files that are too large. According to the official Grok Build changelog summarized in the release brief, the tool now rejects oversized files before downloading the complete file into memory.
What changed in web_fetch?
Previously, handling a large retrieval could require more of the file to be loaded before the size problem was identified. The reported change moves rejection earlier in the retrieval process. The practical goal is to avoid wasting memory on content that the tool cannot process within its limits.
The changelog summary does not specify a new numerical file-size threshold, whether limits vary by file type, or the exact error returned. Those details should not be assumed.
Why early rejection matters
Web retrieval is a common step in agent workflows: reading documentation, gathering evidence, analyzing a report or following a linked source. Unexpectedly large files can consume memory, increase latency and interrupt the broader task. Rejecting such content before full in-memory download may reduce unnecessary resource use and make failures more predictable.
However, early rejection is not the same as successful retrieval. A source that exceeds the supported limit remains unavailable through that attempt. An agent may need a smaller document, an authorized alternate format, a relevant excerpt or another supported access method.
Implications for publishers and AI visibility
For websites publishing lengthy technical documentation or research files, the change highlights an important distinction between being linked and being retrievable by a particular tool. A page may be discoverable but its downloadable attachment may exceed an agent's processing limits.
Publishers can improve usability by offering clear HTML summaries, accessible document sections, descriptive headings and appropriately sized downloadable assets where practical. These are sensible accessibility and information-design practices, not confirmed Grok ranking factors.
What developers should test
- Whether the tool returns a clear failure when a file exceeds the limit.
- Whether the agent can recover and continue its task without repeatedly requesting the same oversized file.
- Whether relevant content is available in a smaller or structured format.
- Whether citations accurately reflect what the agent actually retrieved, rather than content it could not access.
Does this change Grok search rankings?
No ranking, indexing or citation-selection change is announced in this update. It concerns the operational behavior of web_fetch inside Grok Build.
FAQ
Does web_fetch download an oversized file completely?
According to the October 6 release summary, it now rejects oversized files before downloading them entirely into memory.
What is the maximum allowed size?
The supplied changelog summary does not state a numerical limit.
Will every large file become inaccessible?
The change describes rejection of files that exceed the tool's applicable limits, not a blanket ban on large documents.
NetContentSEO analysis
This is a small but meaningful reliability improvement for agentic retrieval. For AI visibility research, it reinforces the need to measure actual source accessibility separately from search discoverability: an agent cannot faithfully use evidence it failed to retrieve.
Primary source: xAI Grok Build changelog, v1.0.50 (October 6, 2026).