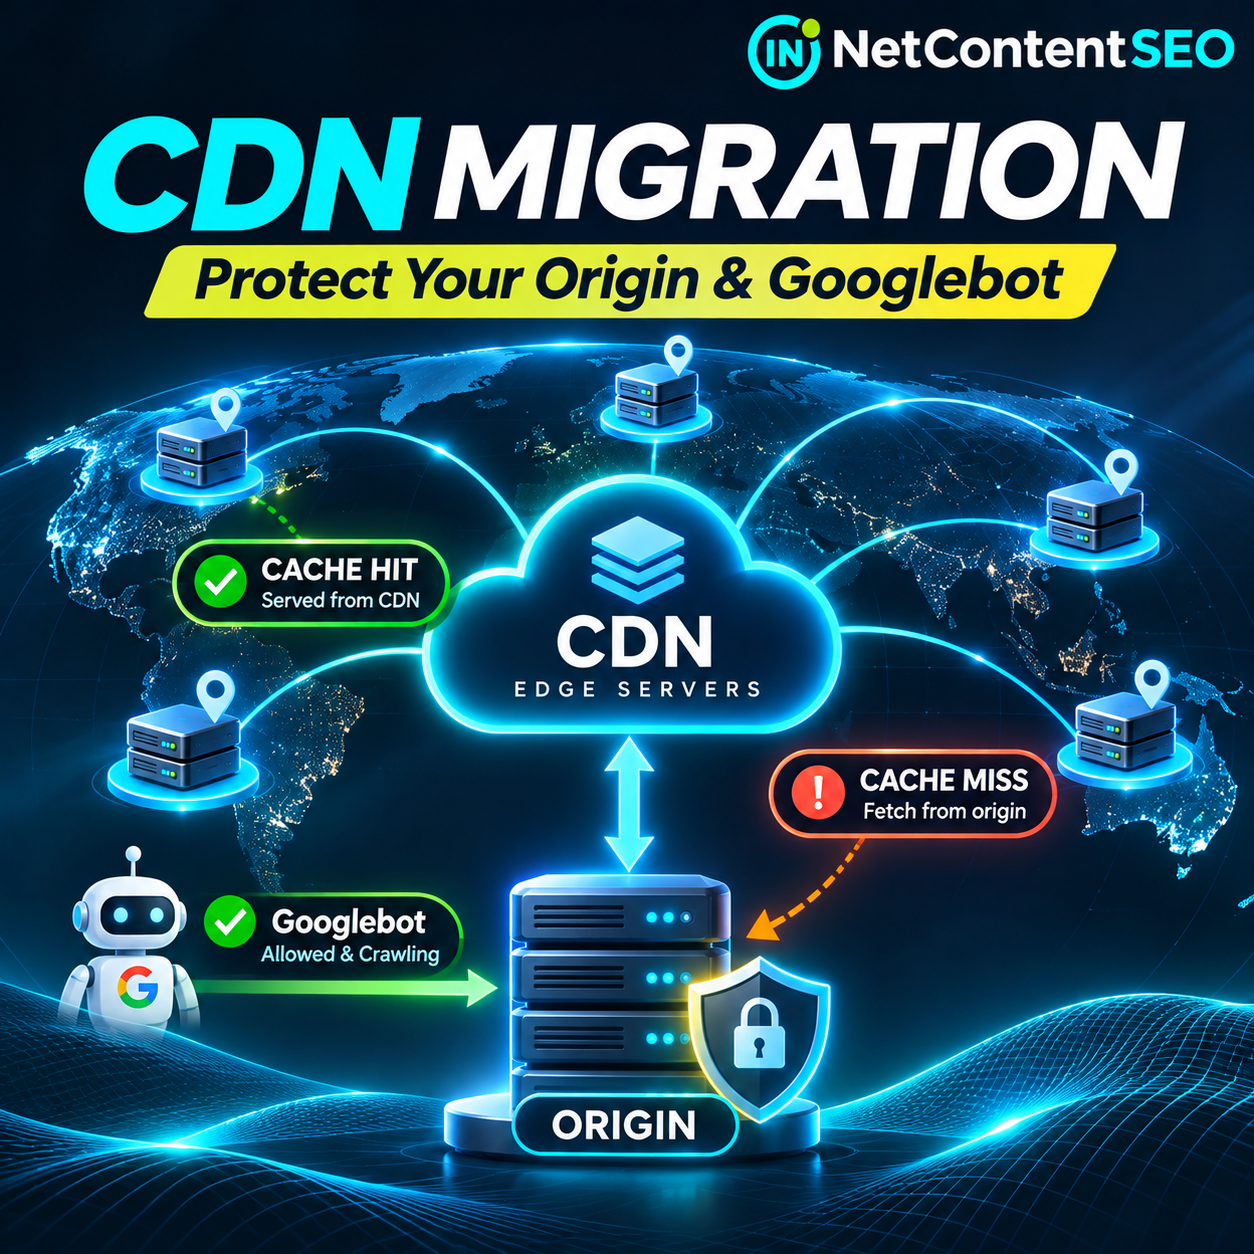
Moving a website to a content delivery network (CDN) usually improves performance and reduces origin-server load. Yet Google's November 11, 2026 Search Central guidance highlights a counterintuitive migration risk: Googlebot may increase its crawl rate just as the new CDN's caches are empty, sending a wave of cache misses back to the origin. If administrators respond by enabling blanket bot challenges, they can inadvertently prevent Googlebot from accessing content at all.
Google's article, Moving to a CDN without overwhelming your origin (or blocking Googlebot), is not a new ranking algorithm announcement. It is an operational explanation of crawler behavior, caching and firewall rules that can have direct consequences for crawling and indexing. Barry Schwartz also covered the advice on Search Engine Roundtable.
Why a faster CDN can temporarily increase Googlebot traffic
Google's crawlers adapt to a host's observed responsiveness and capacity. When a site responds slowly, Google can reduce crawling to avoid overloading it. When responses are fast and stable, Google's systems may gradually raise the crawl capacity limit if there is demand for the site's URLs.
Switching DNS to a fast CDN changes what Googlebot observes. Edge servers can respond much faster than the former origin, suggesting the site can handle more crawling. But this signal describes the edge-facing response path, not necessarily the workload that the backend can sustain while the CDN is still warming.
Google explicitly notes that the increase is not necessarily immediate, and many CDNs have connection pacing. The risk is conditional rather than inevitable.
The cold-cache problem: every unique URL can reach the origin
A CDN can serve a cached response without contacting the origin only after that response is available in the relevant edge cache. The first eligible request for an uncached URL is a cache miss: the CDN must retrieve content from the origin, potentially store it and deliver it to the requester.
Human visitors often cluster on a small number of popular pages, allowing those URLs to warm quickly. Search crawlers explore a much broader URL inventory. If a site has tens of thousands of articles, listings or product pages, a large share of crawler requests may hit URLs that no edge has cached yet.
That creates the migration paradox: a fast CDN encourages more crawling, but an empty cache forces the origin to perform much of the work. The result can be elevated CPU usage, database pressure, slow PHP workers, upstream timeouts or increased bandwidth bills, depending on the application architecture.
Not every URL is cacheable. Authenticated pages, personalized responses, sensitive data and endpoints with unsuitable cache headers should not be indiscriminately cached simply to improve hit rates. Cache safety is a separate requirement from crawl performance.
The second risk: bot protection that blocks Googlebot
After seeing a spike in requests, a site operator might enable a CDN's strongest bot-protection mode. But blanket Web Application Firewall (WAF) rules can challenge verified search crawlers with CAPTCHA, JavaScript interstitials or hard blocks. Googlebot cannot complete a human challenge.
If Google repeatedly receives a challenge page or an error instead of the requested document, crawling and indexing can suffer. Google warns that prolonged blocks may eventually cause pages or shopping listings to disappear from Search. The outcome depends on the status code, duration and affected URLs; a single short interruption does not automatically deindex a site.
Do not solve this by trusting any request whose user-agent string merely says Googlebot. User-agent strings can be spoofed. Use the CDN's managed verified-bot classification or verify crawler identity against Google's documented IP ranges and procedures.
Google's three official recommendations
1. Allow verified crawlers through bot challenges
Google recommends exempting verified crawlers from CAPTCHA and blanket bot challenges when their access is desired. Many CDN and WAF products support managed verified-bot rules. Administrators should still maintain protection against malicious traffic and not broadly disable security.
2. Pre-warm the cache before full migration
Google advises fetching high-traffic, upcoming peak-traffic and frequently crawled URLs through the CDN at a controlled pace. This helps populate edge caches before heavy traffic arrives. Pre-warming should respect origin capacity; aggressively fetching an entire sitemap can itself cause the overload it is meant to prevent.
3. Use temporary 429 or 503 responses when necessary
If origin load becomes critical, Google says temporary HTTP 429 Too Many Requests or 503 Service Unavailable responses can act as an emergency brake for crawling. Its November guidance describes short periods—hours, or at most one to two days—rather than permanent throttling. These codes should be reserved for genuine overload and monitored carefully because prolonged errors can still damage crawling and visibility.
A practical CDN migration checklist for SEO and infrastructure teams
- Inventory critical URLs. Identify canonical HTML pages, sitemap files, robots.txt, images, CSS, JavaScript and structured-data dependencies. Separate public cacheable routes from login, checkout, account and admin routes.
- Measure the origin baseline. Record request rates, p95 response time, CPU, memory, database connections, PHP worker saturation, 5xx responses and existing crawler volume before the DNS switch.
- Review caching rules. Confirm which response types and paths are cached, which bypass cache and whether cache-control and authentication headers prevent unsafe storage.
- Configure verified-bot handling. Check CDN/WAF policies for Googlebot and other wanted crawlers; ensure CAPTCHA or browser challenges are not applied indiscriminately.
- Pre-warm strategically. Start with the homepage, priority landing pages, popular articles, category pages and heavily crawled public URLs, using a bounded request rate.
- Stage the cutover where possible. Validate DNS, TLS, redirects, canonical URLs and response headers in a controlled test before shifting all production traffic.
- Monitor both edge and origin. Compare CDN requests, cache-hit ratios, cache misses, origin requests, 429/503 rates and WAF events. A healthy edge dashboard can conceal an overloaded backend.
- Test actual crawler access. Use Google Search Console URL Inspection and live testing to verify that Google can fetch and render important pages. Review server and CDN logs for verified crawler requests.
- Watch indexing signals. Track Search Console Crawl Stats, indexing reports and server errors. Allow for reporting delays and distinguish technical failures from unrelated ranking changes.
- Have a rollback and incident plan. Document how to disable a problematic WAF rule, reduce unnecessary origin work or revert a routing change without introducing redirect loops or exposing private endpoints.
Specific considerations for Laravel, PHP and Plesk websites
For Laravel applications running behind Nginx, Apache or a Plesk-managed stack, cold-cache requests can reach PHP-FPM and the database even when static assets are already cached. Monitor PHP-FPM busy workers, slow requests, MySQL connections and application logs during the cutover.
Cache static assets with suitable long-lived headers and versioned filenames. Evaluate public HTML caching only where responses are genuinely shareable; never cache authenticated sessions, personalized dashboards, admin panels or private API responses as public content. Ensure the CDN forwards the correct host and scheme and that Laravel's trusted-proxy configuration is correct so generated URLs, redirects and secure cookies behave as expected.
These Laravel/Plesk recommendations are engineering implications of Google's explanation, not product-specific instructions published in the November 11 Google article. The exact controls vary by CDN, server and deployment.
How to distinguish a CDN crawl incident from a ranking update
When organic traffic falls after a migration, check infrastructure evidence before blaming a core update. Look for an abrupt rise in CDN-origin requests, blocked verified Googlebot traffic, challenge responses, sustained 403/429/503 errors or URL Inspection failures. Compare timestamps against DNS and WAF configuration changes.
A core ranking update does not ordinarily explain a new CAPTCHA page being served to Googlebot. Conversely, an isolated cache-miss spike does not prove that indexing has been harmed. Establish the actual sequence of events and use both server-side and Search Console evidence.
What this means for AI Search and GEO
Google's article is about Google's crawling infrastructure. It does not announce a new AI Overview citation factor or a new AI Mode ranking mechanism. However, inaccessible source pages can impair systems that rely on fetching website content. A reliable technical foundation is therefore relevant to AI visibility as well as conventional SEO.
Do not assume that allowing Googlebot automatically allows every AI crawler. Different crawler operators use different identities, IP ranges, policies and robots.txt conventions. Define which bots the business intends to support, verify their identities through official documentation and test access separately.
Frequently asked questions
Will moving to a CDN make Googlebot crawl faster?
It can. Google says faster, stable responses may cause its systems to raise crawl capacity gradually when there is demand. The increase is not guaranteed or necessarily immediate.
Why does the origin receive more requests after the CDN launch?
New edge caches start cold. First requests for uncached URLs must be fetched from the origin; broad crawler coverage can create many unique misses.
Should I block Googlebot to protect the server?
No, not as a blanket default. Google recommends allowing verified crawlers past bot challenges and using carefully controlled temporary 429 or 503 responses only when overload makes them necessary.
Can a CDN CAPTCHA hurt SEO?
Yes. If Googlebot receives a challenge instead of the intended page, it may be unable to crawl or render the content. Prolonged failures can affect indexing.
Is a 503 safer than returning a CAPTCHA with HTTP 200?
For a genuinely temporary outage, a correctly returned 503 communicates temporary unavailability more clearly. A challenge or error served with HTTP 200 can be misinterpreted as page content and may lead to more complicated indexing problems.
Should I pre-warm every URL in the sitemap?
Not necessarily. Pre-warming the entire inventory at high speed can overload the origin. Prioritize important URLs and warm them at a controlled pace.
Does Google recommend one CDN provider?
No. The guidance concerns caching, verified crawler access and safe rate control rather than endorsing a specific vendor.
Is this a new Google ranking factor?
No. The November 11 article is operational guidance about crawling and infrastructure, not a newly announced ranking signal.
Bottom line
A CDN migration can improve speed and resilience while temporarily increasing the load on the origin. Google's advice is to prepare for cold caches, keep verified crawlers accessible and use temporary, correctly signaled throttling only when necessary. For SEO and GEO teams, the lesson is practical: crawler accessibility and infrastructure observability should be part of every CDN launch checklist, not an afterthought once traffic drops.
Sources
- Google Search Central — Moving to a CDN without overwhelming your origin (or blocking Googlebot), November 11, 2026
- Google Search Central — Crawling December: CDNs and crawling, December 24, 2024
- Search Engine Roundtable — Google: How Moving to a CDN Can Accidentally Overwhelm Your Website, November 11, 2026
- Search Engine Land — Google SEO advice on moving to a CDN, November 11, 2026