

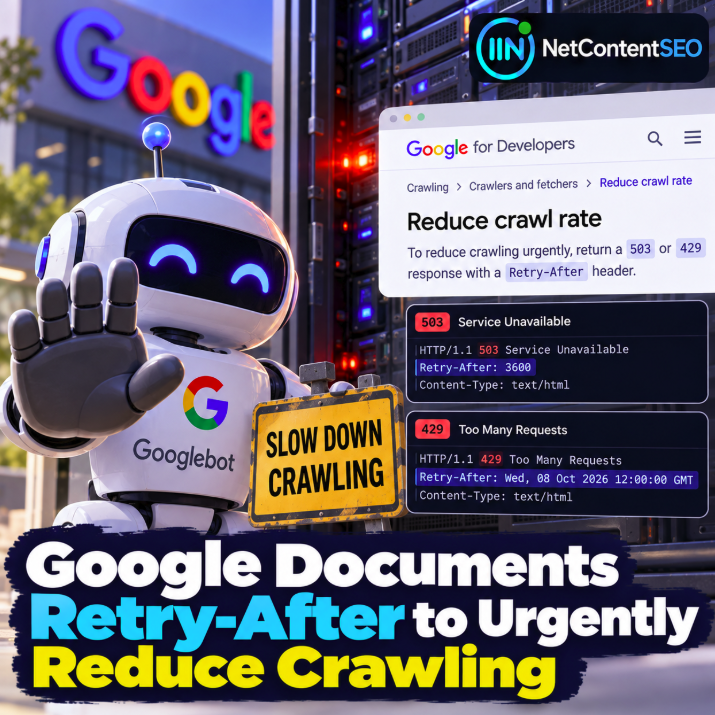

October 8, 2026. Google has updated its official documentation on urgently reducing crawler traffic, adding explicit guidance and examples for the HTTP Retry-After response header. The documentation was updated on October 6, 2026. This is a documentation clarification, not the launch of a new Googlebot capability.
What Google now documents
When a site needs to reduce crawling urgently because of server overload, maintenance or an infrastructure incident, it can return HTTP 503 Service Unavailable or 429 Too Many Requests. The response can include a Retry-After header indicating when a crawler should attempt another request. Google documents two formats: a delay expressed in seconds, or an HTTP-date in GMT/UTC.
Example: Retry-After in seconds
HTTP/1.1 503 Service Unavailable
Retry-After: 120
Content-Type: text/html
This example requests a retry after 120 seconds. The number is an illustrative delay, not a guarantee that Googlebot will return at precisely that moment.
Example: Retry-After with an HTTP date
HTTP/1.1 429 Too Many Requests
Retry-After: Thu, 08 Oct 2026 16:00:00 GMT
The date format provides an absolute retry time. Administrators should generate a future timestamp appropriate to the incident rather than copy a fixed example into production.
503 or 429: which should you use?
A 503 response generally indicates temporary service unavailability, such as maintenance or overloaded infrastructure. A 429 response indicates rate limiting or too many requests. Both can signal a need to slow down, but they describe different server conditions. Use the status that accurately reflects the situation, and avoid turning an otherwise healthy site into a blanket error response.
The indexing risk of prolonged errors
Google cautions that returning server errors for an extended period, such as more than one or two days, can lead to URLs being dropped from the index. That makes this an emergency measure, not a long-term crawl budget strategy. Restore successful responses as soon as the underlying issue is resolved.
How to apply it safely during an outage
- Confirm the actual bottleneck using server metrics, logs and request patterns.
- Use a temporary
503for genuine unavailability or429for rate limiting. - Include a sensible
Retry-Aftervalue, expressed in seconds or as an HTTP date. - Check that load balancers, reverse proxies and CDNs preserve the intended response headers.
- Monitor Googlebot requests and server recovery rather than assuming immediate compliance.
- Remove emergency responses promptly when normal service returns, and monitor Search Console indexing afterward.
What not to do
Do not use robots.txt changes as a substitute for temporary overload management without considering their different effects. Do not return 404 or 410 for pages that still exist merely to discourage crawling. And do not leave a site in a persistent 503 state as a routine SEO optimization.
The NetContentSEO takeaway
For teams operating high-traffic sites or managing fragile hosting environments, the updated guidance provides a documented incident-response option: tell Googlebot that the server needs time, using appropriate HTTP errors and Retry-After. The operational goal is to protect infrastructure during a short disruption while minimizing indexing damage from prolonged unavailability.
Official source: Google Search Central: Reduce the Google crawl rate.