

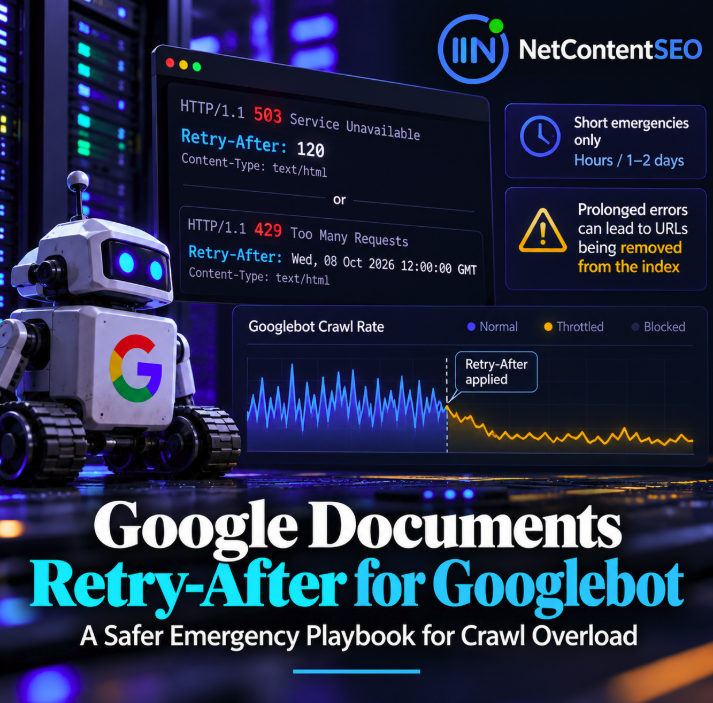

Google has turned an existing crawler capability into a much clearer operational playbook. On October 6, 2026, Google updated its crawling documentation to explicitly explain how site owners can use the HTTP Retry-After header with 503 or 429 responses when they urgently need to reduce crawler traffic.
The technical support is not new. Google says the header was already documented in its guidance for temporarily pausing or disabling a site. What changed is its placement and explanation inside the dedicated Reduce the Google crawl rate documentation.
For technical SEO teams, that matters because emergency crawl management now has a much more explicit Google-documented procedure.
What Google changed on October 6
Google's crawling documentation changelog says it restructured the emergency crawl-rate reduction section and added information and examples for the Retry-After HTTP header.
The reason given is straightforward: support already existed, but putting the instructions directly in the crawl-rate guide makes the mechanism easier to find and understand when crawler traffic needs to be reduced urgently.
This is therefore a documentation update, not a newly launched Googlebot capability.
The basic emergency pattern
Google recommends returning an HTTP error response instead of 200 OK when crawler traffic is creating critical infrastructure load or unwanted costs during an outage.
For a short emergency, Google currently lists 500, 503 and 429 as status codes that can reduce crawler traffic.
When using 503 Service Unavailable or 429 Too Many Requests, site owners can additionally send Retry-After to indicate when Google's crawlers should try again.
Retry-After can use seconds
One supported format is a delay expressed in seconds:
HTTP/1.1 503 Service Unavailable
Retry-After: 120
In this example, the server is telling the crawler to wait 120 seconds before retrying.
Or use an absolute UTC date
Google also documents an absolute date and time format:
HTTP/1.1 503 Service Unavailable
Retry-After: Wed, 21 Oct 2026 07:28:00 GMT
The date must follow the HTTP semantics expected by the header and is expressed in GMT/UTC.
This can be useful during planned maintenance where the expected recovery time is known.
Google reduces crawling across the hostname
The effect is broader than the individual URL returning an error.
Google says that when its crawling infrastructure encounters a significant number of URLs returning 500, 503 or 429, it reduces the site's crawl rate across the whole hostname.
That includes both URLs returning errors and URLs that are still serving content.
Once the number of errors decreases, Google's systems automatically begin increasing the crawl rate again.
This is not a permanent crawl-budget control
The most important warning in Google's documentation is duration.
Google describes this mechanism as appropriate for short periods such as a couple of hours or roughly one to two days.
It specifically advises against using the strategy for longer periods.
If Googlebot continues seeing these status codes on the same URL for multiple days, Google warns that the URL may eventually be dropped from the Search index.
Why this is better than panicking with robots.txt
During infrastructure trouble, teams sometimes reach immediately for robots.txt and block large sections of a site.
That is not equivalent to telling a crawler that the server is temporarily overloaded.
A temporary 503 or 429 communicates server availability or rate limiting through HTTP itself. Adding Retry-After adds a specific retry instruction.
By contrast, a robots.txt block tells Google that it should not crawl the URL at all. Google's crawl-budget guidance also says robots.txt should not be used merely to reallocate crawl budget temporarily.
There is an indexing trade-off immediately
Even a correctly implemented emergency throttle has consequences.
Google warns that reducing crawl rate means it may discover fewer new pages and refresh existing pages less frequently.
That can delay changes to prices and product availability in Search, while deleted pages can remain visible for longer because Google has not revisited them.
The goal is therefore not “stop Googlebot as much as possible.” It is to keep the site operational while reducing crawler pressure only as much as necessary.
Google products beyond organic Search can be affected
The warning is broader than standard indexing.
Google notes that crawl reduction can affect Google Ads, potentially causing campaigns to be cancelled or paused and ads not to serve.
Its crawl-budget documentation also explains that different Google crawlers have different demand patterns. Google Shopping, for example, can have greater crawl demand for products present in merchant feeds.
For ecommerce infrastructure, an indiscriminate emergency response can therefore have commercial consequences beyond organic rankings.
429 already influences crawl capacity
Google's broader crawl-budget documentation confirms that rate-limiting signals such as HTTP 429 are already part of how its systems determine crawl capacity.
If a site slows down, produces server errors or signals rate limiting, Google's crawl-capacity limit decreases and the crawler makes fewer requests.
The new documentation makes Retry-After the more explicit companion signal when the site operator needs to communicate when requests should resume.
A practical incident-response sequence
For SEO and infrastructure teams, the documentation suggests a useful incident pattern:
- Confirm that crawler traffic is actually contributing to the server problem by checking access logs.
- Identify whether the spike comes from structural problems such as faceted navigation, sorting URLs or calendars.
- If the situation is genuinely urgent, return the appropriate temporary HTTP status.
- For
503or429, include a realisticRetry-Aftervalue. - Monitor server recovery and crawler activity.
- Restore normal
200responses as soon as the emergency ends.
The last step matters. The emergency mechanism becomes an SEO problem when it remains in place after the emergency is over.
Do not fake an outage to manipulate crawling
This documentation should not be interpreted as a new optimization trick for ordinary crawl-budget management.
If a site is healthy but Googlebot is crawling inefficient URLs, the long-term solution is architecture: consolidate duplicates, manage faceted navigation, return correct 404/410 responses for removed content, maintain sitemaps and improve server performance.
Retry-After is for temporary operational pressure, not a substitute for fixing crawl traps.
What technical SEOs should test now
Teams responsible for large sites should check whether their CDN, reverse proxy and application layer can actually return the intended status code and header together.
A maintenance configuration that displays a friendly “temporarily unavailable” page while accidentally returning 200 OK is not the same signal.
Likewise, an upstream CDN may rewrite or remove headers before Googlebot receives them.
The correct implementation should be tested at the HTTP-response level, not just visually in a browser.
NetContentSEO take
Google's October 6 update gives technical SEO teams a clearer emergency throttle for crawler traffic, but the safety window is deliberately short.
The important pattern is 503 or 429 plus Retry-After, using either seconds or an absolute UTC date. Google's crawling infrastructure can then reduce traffic across the hostname and recover automatically as errors disappear.
But the warning is equally important: leave those errors in place for multiple days and URLs can disappear from the index.
This is not a crawl-budget hack. It is an incident-response tool — and the difference matters.