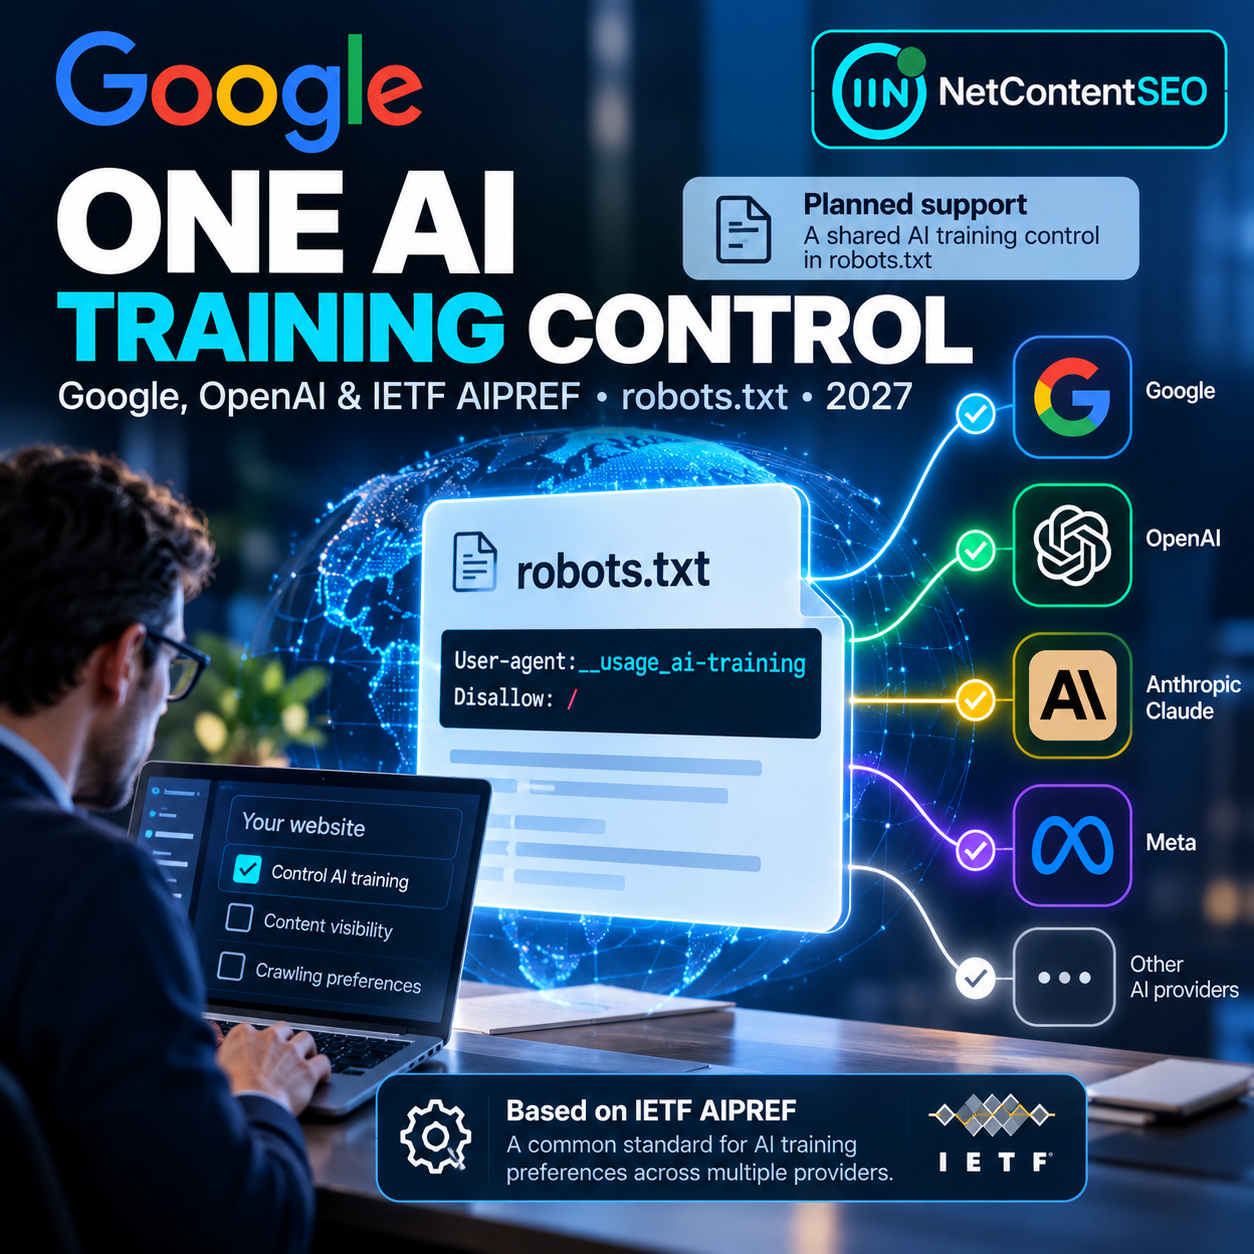
Website owners may soon have a simpler way to tell multiple AI companies whether their content should be used to train generative models. On October 30, 2026, Google announced plans to support a shared AI training preference in robots.txt, based on work by the Internet Engineering Task Force's AI Preferences (AIPREF) working group. OpenAI separately announced that it intends to honor the same common signal.
This is an important development for publishers, technical SEO teams and organizations managing large websites. Instead of maintaining an ever-growing collection of company-specific rules, a publisher could express a broad training preference through one policy token recognized by participating providers. But there is a crucial distinction: this is an announced implementation plan, not a universal control that already works across the industry.
What Google announced on October 30
In a Google Search Central post, John Mueller said Google aims to support the shared control alongside other AI providers in 2027. The mechanism is based on an IETF draft and is intended to coexist with Google's existing Google-Extended control, introduced in 2023.
Google says that when a website uses the common token to opt out of AI training, and does not explicitly set a separate Google-Extended preference, Google plans to interpret the shared opt-out as a Google-Extended disallow. If a publisher explicitly allows Google-Extended, that more specific choice can continue to apply. Google also notes that explicitly allowing Google-Extended preserves eligibility for certain Gemini Apps grounding experiences that can send traffic to publishers.
OpenAI's announcement on the same day says it plans to implement the common signal in the coming months while retaining its existing crawler-specific controls. Neither announcement means that every AI company currently supports the token.
The proposed robots.txt policy token
The October 30 IETF Internet-Draft identifies the token as __usage_ai-training. A simple site-wide preference against generative AI training would look like this:
User-agent: __usage_ai-training
Disallow: /
The draft also permits path-specific exceptions using the familiar robots.txt syntax. For example, a publisher could express a preference against training on most content while permitting it for a public press-kit directory:
User-agent: __usage_ai-training
Disallow: /
Allow: /press-kit/
These examples describe the draft mechanism and should not be presented as immediately effective against every provider. The token is a policy signal, not an ordinary crawling user-agent. Providers that do not implement it may ignore it.
AI training preferences are not the same as crawling restrictions
This distinction is central to the proposal. Conventional robots.txt groups tell crawlers which URLs they may request. The new policy token communicates how retrieved material may be used for the specific purpose of training generative AI models. It does not, by itself, block all bots, remove a page from search results or prevent content from being referenced in every AI product.
The IETF draft defines AI training in terms of using content to modify the learned parameters of a generative model. It excludes some other activities, such as models used exclusively for classification, ranking or scoring. Website owners should therefore avoid assuming that an AI training opt-out controls every form of AI processing, retrieval or search grounding.
How this works alongside Google-Extended
Google-Extended remains a company-specific control. Google says existing controls will continue working alongside the shared signal, and specific preferences can take precedence over a general one. This makes it possible for publishers to express a broad industry preference while choosing a different policy for Google.
That flexibility also introduces a trade-off. Google's announcement says websites that explicitly allow Google-Extended remain eligible to appear in Gemini Apps responses through grounding and potentially receive clicks. Publishers should evaluate training restrictions separately from their goals for AI-assisted discovery and referral traffic. Google has not announced a new Google Search ranking factor as part of this proposal.
Is this an official IETF standard yet?
No. The Machine-Readable Training Preference Signal is an Internet-Draft dated October 30, 2026, not a finalized RFC. It uses the existing robots.txt group structure and introduces no new Allow or Disallow directive names. Work continues within AIPREF on a broader vocabulary and ways to attach preferences to web content.
Google also connects the proposal to European discussions around machine-readable publisher preferences under the EU AI Act framework. However, expressing a technical preference should not be confused with an automatically enforceable legal guarantee or proof that every downstream data user complies.
What publishers and SEO teams should do now
First, inventory existing robots.txt controls, including Google-Extended and any provider-specific training crawlers. Second, decide whether the organization's priority is limiting model training, restricting crawling, maintaining AI-search visibility or some combination of these objectives. Those are related but different decisions.
Third, monitor the IETF draft and the implementation documentation from each provider before treating the shared token as operational. For websites that plan to adopt it, test the final syntax carefully and document any deliberate exceptions. Large multi-domain publishers should also ensure that preferences are consistent with licensing agreements and internal content policies.
Finally, monitor referral traffic and discovery separately from compliance with training preferences. A robots.txt training signal is not a measurement of AI visibility, and no single setting guarantees whether a page will be cited in an AI-generated answer.
Why the announcement matters
The immediate news is not that one robots.txt line can already control the entire AI industry. It is that major providers have publicly committed to a shared, standards-oriented approach that could reduce the administrative burden on publishers. If implemented consistently, the mechanism could give website owners clearer choices without forcing them to abandon ordinary search visibility.
For technical SEO, this is a development worth following closely through 2027. The most important work now is understanding the distinction between training, crawling and AI search, and avoiding premature claims about a still-developing standard.
Primary sources: Google Search Central, October 30, 2026; OpenAI, October 30, 2026; IETF Internet-Draft, October 30, 2026.