

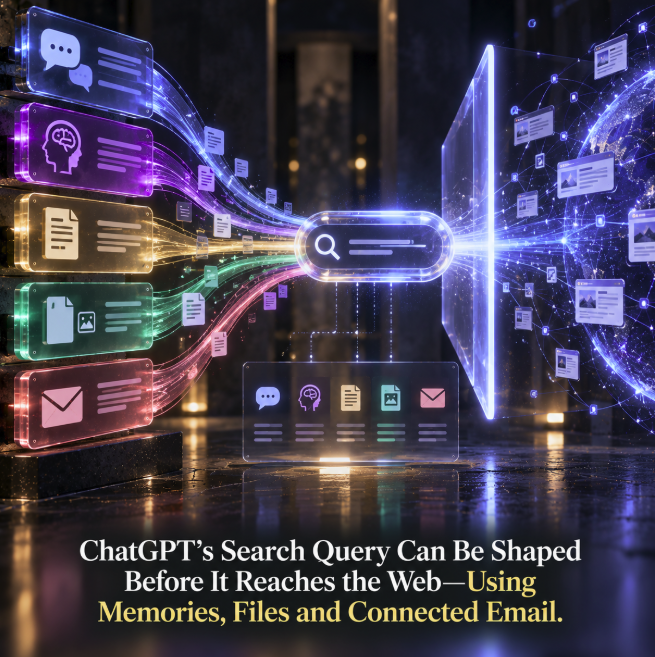

ChatGPT’s web search can be personalized before the query ever reaches the public web. OpenAI now explicitly documents that when Memory is enabled, ChatGPT may use relevant personal details to formulate a more useful search query — and the context available to Memory can extend beyond previous conversations to saved memories, custom instructions, Library files and connected apps such as Gmail.
The expanded description appears in OpenAI’s newly updated Memory in ChatGPT documentation. The page also explains that a Sources section may appear beneath a response when personal context contributes to personalization, helping users inspect items such as a past chat, saved memory, custom instruction, file or connected email that influenced the response.
For search, this creates an important architectural distinction. Personal retrieval does not merely add context after public search results have been returned. According to OpenAI, relevant remembered information can help formulate the search query itself. In other words, personalization can affect what ChatGPT asks the web to find.
Memory now spans more than previous chats
OpenAI’s documentation describes Memory as a system that can draw on several available sources depending on plan, region, platform and workspace settings. Those sources can include past chats, saved memories, custom instructions, files in Library and content from connected apps such as Gmail.
This is broader than the older mental model of memory as a short list of preferences extracted from conversations. The system can use relevant information from a larger personal corpus when the necessary features are available and enabled.
OpenAI is careful to say that Memory does not retain every detail from every conversation. ChatGPT determines which available information is relevant to a response, and the context Memory considers useful can change over time.
Personal context can shape the web query itself
The most consequential sentence in the updated documentation appears in the FAQ on web search. OpenAI confirms that when Memory is enabled, ChatGPT may use relevant details to formulate a more useful search query.
The company gives a straightforward example: location or dietary preferences can refine a restaurant search. The mechanism has broader implications, however. If ChatGPT knows relevant context about the user before performing the public search, it can translate a relatively underspecified request into a more targeted query.
A request such as “find a restaurant for dinner” does not necessarily have to become the same web query for every person. Existing context can help determine what location, preferences or constraints should be represented in the search.
This means personalization can happen upstream of ranking and retrieval
Search personalization is often imagined as a post-processing layer: retrieve a common set of results, then reorder or summarize them differently for each user. OpenAI’s documentation establishes another possible stage.
ChatGPT can use relevant memory to formulate the query that initiates the search. If two users provide the same short prompt but have different relevant remembered context, the system may construct different searches before any public result is retrieved.
OpenAI does not publish the internal query-generation algorithm, signal weights or exact circumstances under which a particular memory changes a search. It would therefore be incorrect to claim that every remembered detail is injected into every query. The documented point is narrower: relevant details may be used when they are likely to make the search more useful.
Library files can participate in the personal context layer
OpenAI says Memory may use relevant files in Library when the feature is available. Library contains files a user has uploaded or created in ChatGPT and, where supported, can also expose files and folders from connected services.
OpenAI’s Library documentation says the service can include saved documents, spreadsheets, presentations, PDFs and images. Where available, it can also show connected Google Drive, Box, Dropbox and SharePoint content while those files remain associated with their original services.
The Memory documentation does not say that every Library file is read for every search. It says relevant Library files may be used when the feature is available and enabled. That distinction matters because personal retrieval is selective rather than a blanket insertion of the entire Library into each request.
Connected email can also contribute to personalization
Gmail is the clearest example OpenAI gives of a connected app that can contribute relevant information. The Memory page lists content from connected apps such as Gmail among the possible sources available to Memory.
OpenAI’s separate Google app data controls documentation confirms that when Google apps are connected and Memory is enabled, eligible information accessed through those apps may help personalize ChatGPT, subject to account permissions, settings and Google-specific data-use limitations.
This does not mean connecting Gmail automatically gives every web search unrestricted access to the mailbox. Access remains governed by the connected app, user permissions, supported requests and workspace controls. OpenAI also says an ordinary Google app connection does not automatically create a personal synchronized index of the entire service.
Sources can expose some of the personal context behind a response
The updated Memory documentation also gives users more visibility into this retrieval layer. When ChatGPT uses relevant personal context, a Sources section may appear beneath the response.
OpenAI says those Sources can help users review a past chat, saved memory, custom instruction, file or connected email that contributed to personalization. Depending on the source and available controls, users may be able to open the item, correct or delete a saved memory, delete a referenced chat, mark a source as relevant or not relevant, or open the referenced file or email.
The feature should not be interpreted as a complete audit trail. OpenAI explicitly says Sources may not show every factor that shaped a response. The Memory summary likewise provides a high-level view rather than an exhaustive inventory of every detail or source the system can reference.
Web citations and Memory Sources are different things
The word “Sources” can create confusion because ChatGPT web search also displays citations to public webpages. The two concepts serve different purposes.
Web citations identify online material used to support the answer. Memory Sources help users inspect personal context that contributed to personalization. A single answer can therefore involve two retrieval layers: private context that helps shape the task or query, and public web sources that provide current external information.
That separation is essential for understanding how personalized AI search differs from a conventional search engine request.
Personal retrieval and public web retrieval can now work in sequence
The emerging workflow can be described as a sequence rather than a single search operation. ChatGPT receives the user’s prompt, determines whether relevant personal context is available, may use that context to make the search request more useful, retrieves public web information and then constructs a response using the available evidence and context.
Not every request requires every stage. OpenAI says ChatGPT does not search a user’s history for every response; it looks for relevant context when doing so is likely to improve the answer.
Likewise, not every ChatGPT response performs a web search. The significance is that when web search does occur and Memory is enabled, personal context can influence the retrieval request upstream.
This is different from sidebar search
NetContentSEO recently documented how ChatGPT’s sidebar search can retrieve chats, projects, images, documents, Library files and eligible connected Google Drive content. OpenAI explicitly says that sidebar search finds existing account or workspace content and does not search the web.
The Memory update describes a different relationship between private and public information. Here, personal context can be used to personalize a response and, where relevant, help formulate a public web-search query.
One system helps the user directly find an existing private object. The other can use relevant private context to improve how ChatGPT approaches an external information request.
Connected apps turn personal context into a cross-system layer
As connected apps expand, the personalization layer is no longer confined to information originally typed into ChatGPT. A relevant email, file or connected document can potentially contribute context when the appropriate features and permissions are active.
This gives ChatGPT a way to bridge information environments without treating them as one undifferentiated database. The email remains in Gmail, a connected file can remain with its storage provider and a past conversation remains in ChatGPT history, yet relevant information can still participate in personalization.
The architecture is therefore less about moving every piece of data into ChatGPT and more about selectively retrieving context from authorized sources.
The SEO implication is that the visible prompt may not equal the actual search query
For publishers and search researchers, the update complicates prompt-level testing. The sentence a user types into ChatGPT may not be the complete representation of the query that ultimately reaches web retrieval.
If Memory is enabled and relevant context is available, ChatGPT can formulate a more useful search query using those details. Two accounts submitting identical visible prompts could therefore receive different searches or results because the system has different relevant context available.
OpenAI does not provide a tool for publishers to see every generated search query or reproduce the complete personalization pipeline. This means AI-search testing that ignores account state can mistake personalization effects for general retrieval behavior.
Clean-room AI search testing now requires controlling memory state
Researchers trying to measure whether a brand, page or source appears for a particular prompt should account for this documented personalization layer. A test performed with Memory enabled may represent the behavior of that account rather than a context-neutral baseline.
That does not make personalized testing invalid. In many real-world situations, personalized behavior is precisely what users experience. But researchers should distinguish between testing an unpersonalized prompt and testing a prompt in an account with accumulated context.
OpenAI’s recently expanded Temporary Chat controls make that distinction more explicit. As NetContentSEO reported in our analysis of Personalized and Unpersonalized Temporary Chat, a Temporary Chat can itself use existing memories unless the user selects the unpersonalized option before beginning.
Personalized query formulation raises new transparency questions
When a search query is shaped by information outside the visible prompt, users may reasonably want to know what influenced the answer. The Sources feature provides part of that transparency by surfacing some personal context that contributed to personalization.
But OpenAI says the list may not expose every factor. It should therefore be viewed as a review mechanism rather than a complete technical trace of query generation.
For high-stakes research, users should still inspect the public citations, verify source content and be aware that personal context may have influenced what ChatGPT chose to search for in the first place.
Disconnecting an app stops future access but does not rewrite old conversations
OpenAI also documents an important lifecycle rule for connected sources. Disconnecting an app prevents future access to that app, but it does not delete past conversations that already used content retrieved from the service.
Likewise, removing remembered information can require action at the underlying source. OpenAI advises users to remove relevant information from the memory controls, chats, Library files or connected apps where applicable rather than assuming that deleting one reference automatically removes every copy or source.
This reinforces the idea that personal retrieval spans multiple repositories with distinct retention and permission models.
Personal context is becoming part of the search stack
The updated Memory documentation reveals a deeper change in how ChatGPT search should be understood. Personalization is not limited to tone, preferred formats or details added after an answer has been generated. Relevant context can participate earlier, at the point where the system decides how to formulate a public web query.
That context can come from past chats, saved memories, custom instructions, Library files and connected apps such as Gmail, depending on availability and settings. Sources can then expose some of the personal material that contributed to the personalized response.
The visible prompt is therefore no longer necessarily the whole search request. When Memory is active, ChatGPT can use a user’s private context to shape what it asks the public web — making personal retrieval an upstream component of AI search rather than merely a layer added after retrieval.