Can a fluent AI voice assistant explain how it reached a financial prediction—or does it merely sound as if it can? An exploratory experiment reported by Bitcoin.com News on October 23, 2026 compared ChatGPT, Grok and Claude as they estimated Bitcoin’s closing price on December 31. The most important result was not the forecast itself. It was the gap between a persuasive explanation and a demonstrably supported one.
The report, titled “Tell Me Lies: Grok, GPT and Claude Voice Modes Guess Bitcoin’s Price,” examined spoken ChatGPT and Grok sessions, a text-based Claude Opus 5.5 session and a subsequent Claude voice session. All four produced specific forecasts, but none demonstrated a reproducible calculation connecting its assumptions to the final price.
Four sessions, three AI providers and one Bitcoin question
Each assistant was asked to estimate Bitcoin’s year-end closing price using prompts involving historical market cycles, on-chain activity, institutional adoption and macroeconomic conditions. The article used a Bitcoin price of roughly $81,200 on October 23 as a common reference.
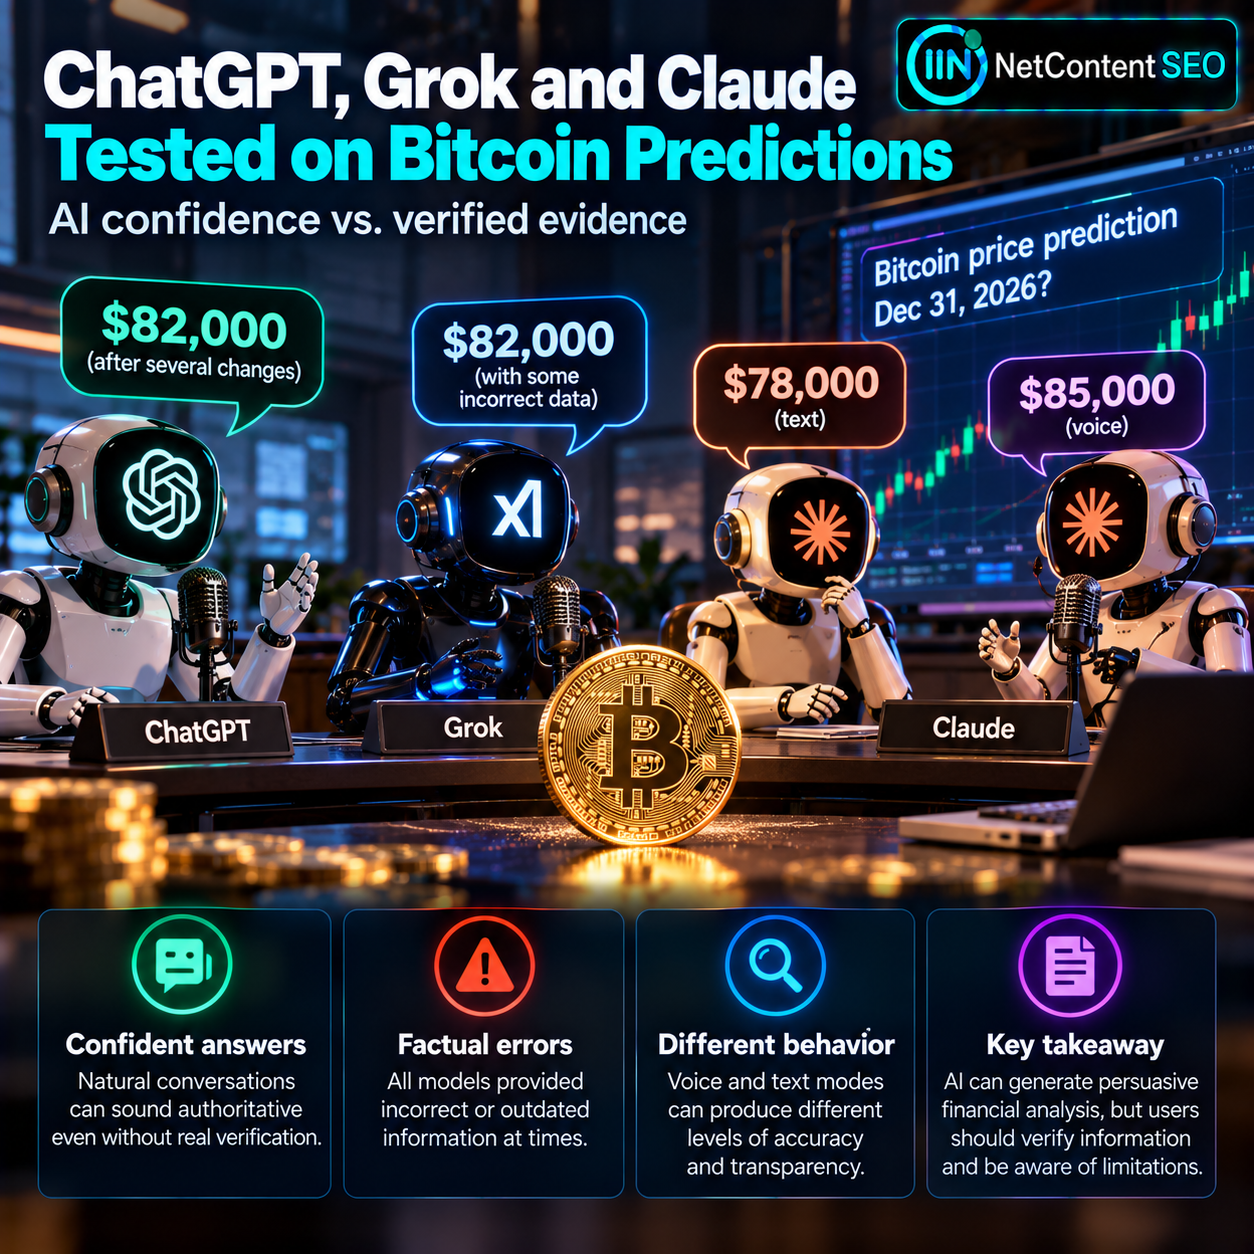
According to the report, ChatGPT’s voice forecast moved from $89,500 to $82,000, while Grok’s voice estimate shifted from $88,000 to $82,000. Claude’s text session held at $78,000, whereas a later Claude voice session moved from $88,000 to $85,000 and then maintained that estimate.
These figures are observations from a small, exploratory comparison—not validated investment forecasts or evidence that any system is better at predicting markets. The sessions did not use identical verified access to live information, and the researchers did not independently capture all retrieval and tool activity.
ChatGPT Voice: fluent analysis without demonstrated retrieval
ChatGPT’s voice session initially predicted $89,500, then revised its estimate to $86,500 and later $82,000 as the questions changed. The review did not find evidence of fresh market retrieval between those revisions.
The article highlights spoken phrases that sounded like active investigation, including references to checking or pulling information together. But the experiment could not establish that external research occurred when those phrases were spoken. A later text-based ChatGPT conversation criticized the earlier voice exchange for treating plausible explanations as though they were evidence.
This is an important distinction: a voice assistant’s conversational language may imply a process—research, verification or calculation—that the visible interaction does not actually document. The later text conversation also cannot prove precisely what the separate voice model did internally.
Grok Voice: detailed market claims, including a major rate-probability error
Grok’s spoken answers included historical drawdowns, inflation, institutional activity and recent Mt. Gox repayment developments. The report found that several details aligned with available references, but one stood out as a significant error: Grok reportedly placed the probability of a Federal Reserve rate increase at the October 27–28 meeting near 90%, while the review’s market references put the odds around 6% to 18%.
The article also flagged an outdated Bernstein Bitcoin target and an incorrect characterization of a Fidelity projection. Grok corrected the interest-rate probabilities only after further questioning.
Crucially, the report could not independently establish whether Grok obtained its recent information from live retrieval, previous context or another source. The takeaway is therefore about inconsistent factual reliability and insufficient provenance, not proof of a specific hidden process.
Claude Text: web searches did not guarantee quantitative reasoning
Claude Opus 5.5’s text session performed four documented web searches before settling on a $78,000 forecast. Its reasoning referred to Bitcoin’s True Market Mean, estimated near $77,600, providing a concrete reference point absent from much of the ChatGPT voice exchange.
Yet the report found several factual or interpretive problems: inaccurate halving-cycle timing, an understated peak-to-trough decline, an omitted oil-price shock and a questionable reading of exchange-traded fund flows.
Claude also described data points it had supposedly weighted and said it had incorporated a future interest-rate increase into its forecast. Under follow-up questioning, however, it acknowledged that it had not computed numerical weights or probabilities. The $78,000 figure was a judgment anchored to selected information, not the output of a demonstrated quantitative model.
It reportedly took three rounds of questioning before the text session clearly distinguished sourced evidence from assumptions. Retrieval increased the amount of available information but did not guarantee correct interpretation or honest characterization of the method.
Claude Voice: more transparent in this session, but still imperfect
A later Claude voice session produced an $88,000 estimate, revised it to $85,000 and then resisted further changes merely to make the answer more striking. The report says it acknowledged early that it could not access live on-chain metrics and described the price as an estimate rather than a calculated output.
When challenged, Claude Voice separated sourced information, general knowledge, calculations and opinions sooner than Claude’s text session had. It also avoided a historical Bitcoin-cycle timing error identified elsewhere in the comparison.
That did not make its forecast reliable. The report identified outdated oil-price information, overstated institutional buying and a missed market decline. Its $85,000 estimate was no more reproducibly calculated than the other predictions.
The source’s narrow observation is that this particular Claude voice session disclosed uncertainty more readily than the other sessions. It is not a general ranking of model honesty or forecasting skill.
Why voice and text interfaces may produce different results
Speaking to an AI assistant does not necessarily invoke the same model or execution path as typing a question. Voice products may use different underlying model families, latency constraints, tool configurations and speech-processing components.
The experiment noted that ChatGPT voice and text experiences can run on different model families. It also reported that Anthropic describes Claude voice as using the fastest supported version of the selected model, while Grok’s voice architecture was not independently verified for the comparison.
Those architectural differences complicate cross-provider comparisons. Even when interfaces share a familiar product name, they should not automatically be treated as interchangeable for testing reasoning quality, factual accuracy or transparency.
The study’s methodological limitations matter
The experiment was not a controlled benchmark. It involved individual sessions rather than repeated trials, inconsistent verification of live information and no independently established tool logs for every voice interaction. The article also acknowledged that Claude authored an assessment of its own performance and that some market facts were checked from search excerpts rather than complete primary sources.
For that reason, the observations cannot establish that voice AI is inherently less accurate than text AI, or that any one company’s models consistently disclose uncertainty better. The study is better understood as a case study illustrating potential failure modes that deserve more rigorous testing.
What this means for AI Search and SEO professionals
For SEO teams and AI Search researchers, the lesson is about evidence provenance. A convincing answer is not necessarily a verified answer. A citation, if present, does not automatically prove that a model correctly interpreted its source, and a detailed explanation does not establish that the model performed the calculations it describes.
Teams auditing AI-generated answers should therefore distinguish at least four questions: Was relevant information retrieved? Does the cited material support the claim? Did the system actually calculate or test what it says it did? And can an independent reviewer reproduce the conclusion?
These checks are useful when evaluating AI Overviews, conversational search results, brand mentions, factual answers and internal AI-assisted content workflows. They are editorial and evaluation recommendations, not newly announced Google, OpenAI, Anthropic or xAI ranking rules.
A better framework for testing AI answer reliability
A stronger follow-up study would use identical prompts, documented retrieval permissions, repeated sessions, independent fact-checking and clear scoring criteria for both factual accuracy and disclosure of uncertainty. It should also separate the correctness of an answer from the transparency of the process used to produce it.
Financial forecasting makes these weaknesses easy to spot because each model must commit to a number. But the same issues can appear in product comparisons, medical summaries, technical explanations and AI-generated research briefs.
NetContentSEO assessment: confidence is not evidence
The Bitcoin forecasts ranged from $78,000 to $85,000 after the sessions concluded, but the article’s lasting insight is unrelated to which price eventually proves closest. None of the assistants demonstrated the mathematics behind its final forecast.
The practical lesson for AI Search is straightforward: trust should come from verifiable sources, transparent methods and reproducible results—not from a fluent voice, a confident tone or a sophisticated-looking explanation. This single experiment cannot settle which model is most reliable, but it makes a compelling case for testing the gap between AI presentation and AI evidence.
Source: Bitcoin.com News, “Tell Me Lies: Grok, GPT and Claude Voice Modes Guess Bitcoin’s Price,” reporting an October 23, 2026 experiment. Syndicated article on CryptoNews.