
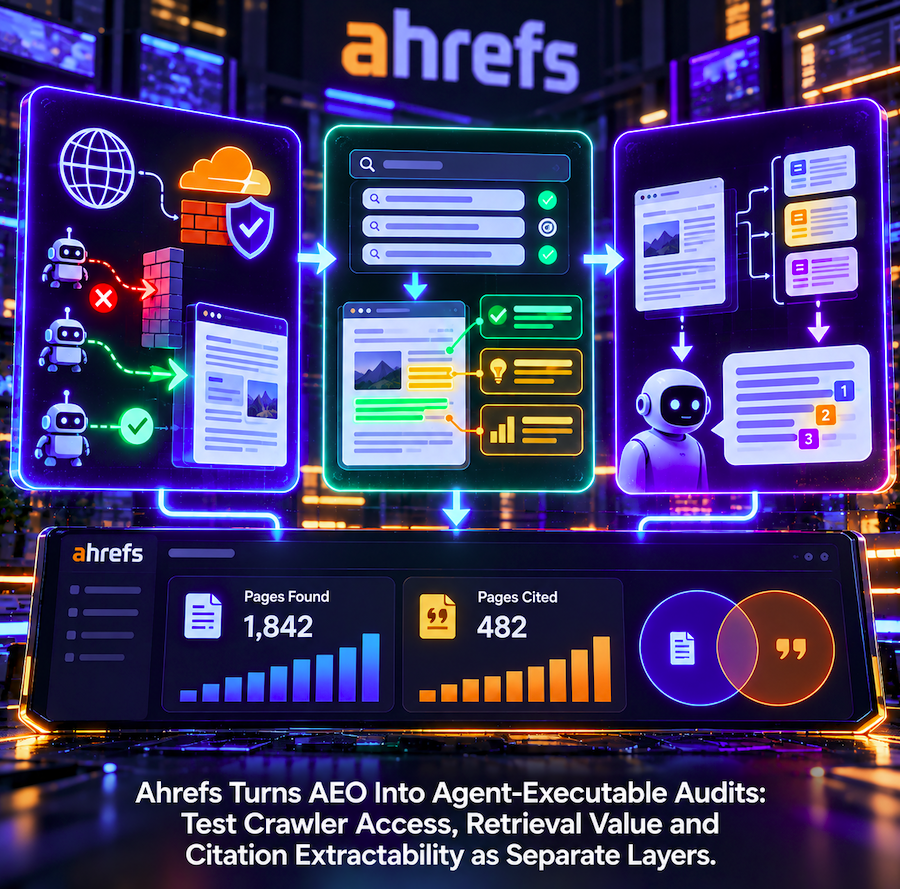
Ahrefs is turning AI-search optimization from a collection of writing recommendations into a set of tasks an agent can actually execute. A new guide published September 25 pairs Ahrefs data with three public agent workflows that separately test whether AI crawlers can reach a page, whether the page contains anything worth retrieving for target queries, and whether its important facts remain understandable and citable when the content is broken into passages.
The framework appears in Ahrefs’ official “How to Optimize for AI Search” guide by Mateusz Makosiewicz. Rather than presenting AEO as a replacement for SEO, Ahrefs argues that traditional crawlability, indexability and usefulness remain prerequisites while generative search adds another requirement: pages must supply facts that AI systems can understand, trust and cite.
The practical change is automation. Ahrefs links directly to three public repositories maintained by Makosiewicz: the AI Crawler Access Audit, Query Match Audit and AI Extractability Audit. They can be handed to an agentic environment so the diagnosis becomes a repeatable workflow rather than a checklist someone has to execute manually page by page.
The first audit asks whether the AI crawler can reach the real page
The crawler-access workflow addresses a blind spot in ordinary site auditing. Ahrefs Site Audit can identify many technical problems, but a successful conventional crawl does not prove that external AI bots receive the same access. A CDN, firewall or bot-management rule can selectively block an AI crawler while allowing Ahrefs, Googlebot or a normal browser through.
Ahrefs explicitly points to Cloudflare as an example. Its guide says some access problems cannot be found through a typical site crawl and require inspection of server, firewall or CDN settings. The agentic audit combines Ahrefs site-health information with Cloudflare controls and can inspect robots directives, noindex rules, status codes, redirects, visible content, WAF rules, crawler visits and blocked bot requests.
That separation is operationally important. A page can be perfectly indexable in traditional search while an AI crawler is denied at the edge. Without checking both layers, an AEO team can spend weeks rewriting content that the target system cannot fetch.
This connects directly with NetContentSEO’s earlier analysis of why AI crawler measurement needs careful interpretation. Bot access, retrieval, citation and downstream traffic are different events; seeing or blocking one class of crawler does not by itself reveal the entire AI-discovery journey.
The second audit asks a harder question than keyword relevance
Once access works, Ahrefs moves from technical availability to retrieval value. Its Query Match Audit takes a draft or page plus roughly three to ten target prompts and checks whether the title, headings and body actually address those prompts. It also flags thin sections, generic passages, vague claims, weak examples, missing evidence and gaps in topic coverage.
The distinctive part is the second half of that test. Matching a query is not enough. Ahrefs asks whether the page contains information an AI system would have a reason to retrieve rather than replace with one of dozens of interchangeable summaries.
The guide identifies original examples, surveys, benchmarks, workflows, customer insights and expert judgment as the kinds of information that can make a page harder to substitute. The agent can identify where such value is absent, but Ahrefs is careful about the boundary: it cannot manufacture genuine expertise, proprietary data or real customer evidence. Those inputs still have to come from the publisher.
This makes the skill more interesting than an automated on-page SEO grader. It is trying to evaluate two separate conditions: semantic fit with the target information need and information gain strong enough to justify retrieval.
A page can be relevant and still fail after chunking
The third repository focuses on what happens after a retrieval system has found useful content. AI search engines frequently split pages into smaller chunks or passages and retrieve only the portions relevant to a question. A statement that makes sense when read with the preceding five paragraphs can become ambiguous or misleading when extracted on its own.
The AI Extractability Audit tests for that failure mode. Ahrefs instructs the agent to examine whether facts and data remain understandable when pulled from surrounding context, flag buried answers and vague claims, and suggest self-contained rewrites without inventing new facts. The repository describes the task as auditing whether AI search engines can chunk, understand and cite a page’s facts.
That turns “write for AI” into a more precise engineering problem. The goal is not robotic prose or a page made of isolated factoids. It is to ensure that important passages preserve enough subject, timeframe, units and attribution to remain accurate when the retrieval layer separates them from the full document.
Ahrefs recommends putting the main answer early in a section, using specific names, dates and numbers, keeping important information in visible text and organizing complex information with clear structures when they genuinely help. The guide calls this largely good editorial hygiene rather than a special machine-only writing style.
The three audits map to three different failure states
Taken together, the repositories create a useful diagnostic sequence. A page can fail because the crawler cannot access it. It can be accessible but fail because it does not contribute enough distinctive information to deserve retrieval. Or it can contain valuable information but express it in a form that becomes unclear when a search system extracts the relevant passage.
Those failures demand different fixes. Changing headings will not repair a Cloudflare WAF rule. Opening crawler access will not make a generic article more useful. Adding original research will not help if the crucial statistic loses its date and subject when extracted from the surrounding paragraph.
This layered model is consistent with the retrieval funnel NetContentSEO described in our analysis of Perplexity’s first-stage retrieval benchmark. Citation is downstream of earlier gates. A source has to become technically available, enter the evidence pool and survive later source-selection decisions before a visible citation is even possible.
Ahrefs now distinguishes “found” from “cited” pages
The monitoring layer makes that funnel visible in Ahrefs Brand Radar. In its Cited Pages report, Ahrefs recommends comparing how often a page is shown as a citation with how often it is “found.” The guide defines found as a broader event: the page was either cited or retrieved without being shown in the answer.
That distinction is unusually valuable for diagnosis. A page that is rarely found may have an access, discovery or relevance problem. A page that is frequently found but rarely cited has already passed some of those upstream gates, shifting attention toward source selection, evidence quality, competition or how effectively its passages support the answer.
It also prevents AEO reporting from collapsing every failure into one citation score. A citation is the visible outcome users can inspect, but retrieval can happen without that outcome. Ahrefs is effectively exposing two stages of the funnel instead of treating absence from the final answer as proof that the system never saw the page.
NetContentSEO recently explored the same diagnostic distinction through an experimental exact-content retrieval test. The underlying principle is identical: before changing authority signals or chasing citations, determine whether the retrieval layer can locate the expected content at all.
Agentic SEO is moving from advice generation to inspection
The broader shift is not that Ahrefs has added another AI writing assistant. The repositories are designed to let an agent inspect systems and artifacts: crawler rules, APIs, page content, target prompts and passage structure. That is a more consequential use of agents than asking a model to generate a list of generic optimization suggestions.
An agent with the necessary permissions can move between Ahrefs and Cloudflare data, compare what different systems report, inspect page text and return prioritized findings. The same pattern extends later in Ahrefs’ guide to citation analysis, freshness checks and comparison against a publisher-maintained source-of-truth file.
This makes AEO increasingly reproducible. Instead of a consultant manually checking ten pages and describing common issues, a team can encode the inspection logic in a skill and run it repeatedly across drafts, published pages or changing infrastructure.
Open source makes the audit logic inspectable
The public GitHub repositories matter for another reason: teams can inspect what the agent has been instructed to do. AI-search optimization is currently crowded with proprietary scores whose definitions are difficult to audit. A public skill exposes the assumptions, checks and output format behind the recommendation.
That does not make every conclusion objectively correct. Query fit and content distinctiveness still require judgment, and agent outputs can be wrong. But an inspectable workflow makes it easier to see whether a recommendation came from an actual technical check, a page comparison or a vague model heuristic.
The repositories can also be adapted. A company could add its own source-of-truth data, preferred AI crawlers, content standards or publishing workflow while retaining the basic separation between access, retrieval value and extractability.
AEO is becoming a pipeline, not a single optimization score
Ahrefs’ framework is useful precisely because it resists reducing AI visibility to one number. Crawl access is binary or conditional at the infrastructure layer. Query match and information gain affect whether content is worth retrieving. Passage construction affects whether evidence survives extraction. Freshness and consistency affect trust. Citation monitoring reveals only some of what happened downstream.
A single “AI readiness” score can hide which of those stages failed. An agent-executable audit can instead return a causal path: ClaudeBot is blocked by a WAF rule; the target page is accessible but does not answer two priority prompts; a key statistic becomes ambiguous when chunked; the page is nevertheless being found but seldom cited.
That kind of diagnosis is much closer to technical SEO than to the early GEO habit of rewriting paragraphs in the hope that an LLM prefers a particular format.
The optimization target is now the whole evidence path
Ahrefs’ new workflow does not prove that passing these three audits will cause a page to be cited. AI search systems use proprietary retrieval, ranking and generation processes, and citation outcomes can vary across prompts and repeated runs. Ahrefs itself presents the tools as diagnostics and emphasizes that human teams still decide what deserves to be published.
What the workflow does provide is a cleaner model of the problem. AI visibility can fail before content is read, after it is read but before it is selected, or after selection when a passage cannot stand on its own. Measuring only final citations obscures those distinctions.
For AEO teams, that changes the job from “make this article more AI-friendly” to a sequence of testable questions: Can the relevant crawler access it? Does the page contain something uniquely useful for the intended query? Can the system extract that evidence without losing its meaning? Is the page being found? And after all of that, is it actually being cited?
Ahrefs has now packaged several of those questions as tasks an agent can execute. That may be the more important evolution in AI-search optimization: not another theory about what language models like, but a diagnostic pipeline that lets teams identify exactly where a page stops progressing toward the answer.