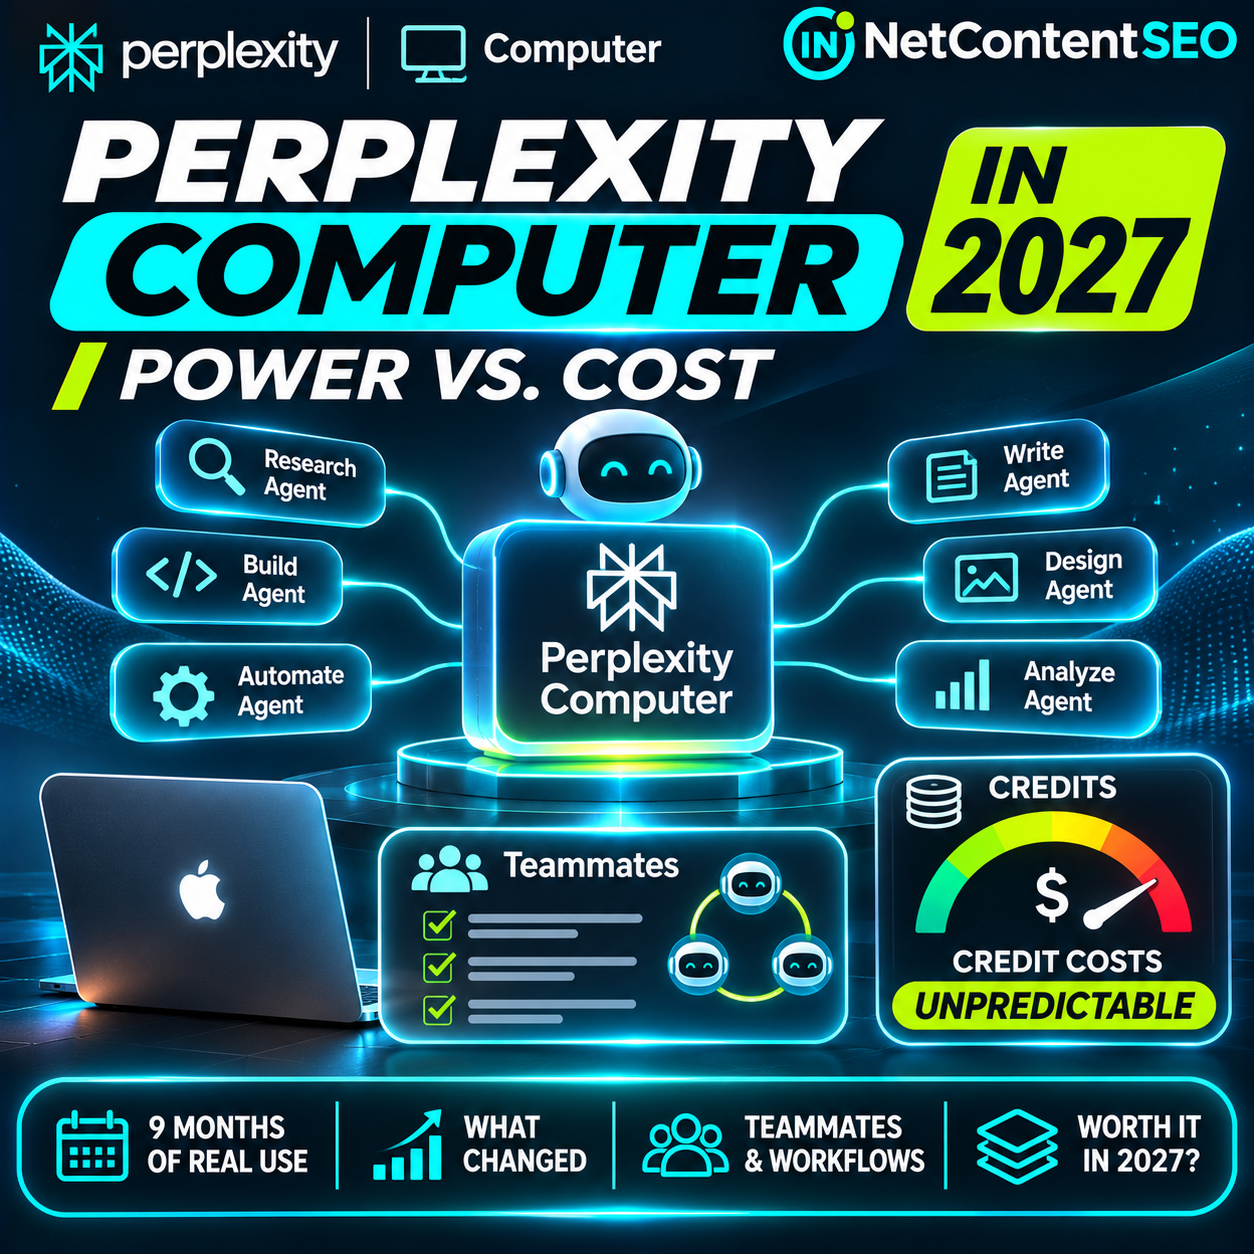
Perplexity Computer is no longer just a research assistant that produces an impressive deliverable. By November 2026 it has become a broader agent platform, combining web research, application building, automation, cloud execution, local Mac workflows and persistent agents called Teammates. The more difficult question for prospective users is not whether the system can do useful work. It is whether the value of a completed task justifies a bill that can be difficult to predict.
That tension is the focus of Karo Zieminski's nine-month practitioner review. The Product with Attitude writer describes using Computer almost daily since its February launch, testing research, building, teammates, credit consumption and failures. Her experience is a valuable case study, not an independent benchmark of every competing agent. We checked its main product claims against Perplexity's November 6 changelog, official Teammates announcement and pricing information.
What Perplexity Computer actually does
Computer is a multi-step AI agent environment: users describe an outcome and the system can coordinate research, analysis, file creation, coding and connected-app tasks. Its cloud execution uses Perplexity's sandbox infrastructure, including the SPACE platform described in the company's official blog. The platform is more ambitious than a question-answering search box because it can work through a task rather than merely suggest what the user should do.
That distinction also changes the economics. A normal search request can be inexpensive and short. An agent that explores sources, invokes tools, retries a browser action, generates files and revises an output consumes resources across many steps. Two prompts with similar wording may have very different costs if one requires a complicated execution path.
What changed between launch and November 2026?
The official changelog documents a fast expansion of Computer's capabilities. In March, Computer became available to Pro subscribers on web and iOS. Subsequent updates added Projects, shared workspaces, Brain, automations, skills, new model choices and controls for connectors. The November 6 release introduced Teammates, fully local Computer on supported Macs and expanded voice capabilities.
These are verifiable platform releases. Zieminski's account adds a different layer: how those capabilities feel in sustained work, where they save time, and where they introduce operational overhead. Both perspectives matter. A feature list cannot show the total cost of delivering an acceptable result, while one reviewer's experience cannot establish average performance for every user.
Teammates: persistent agents for ongoing work
Perplexity announced Teammates on November 4, 2026. These agents can take responsibility for continuing workstreams, coordinate Computer sessions, remember project context and collaborate with other teammates. The initial rollout is for Max subscribers on the web, with mobile access described as forthcoming.
The official product examples include monitoring an inbox, tracking competitors and supporting customer-service workflows. Zieminski describes using specialized teammates for SEO and answer-engine optimization, task prioritization, research and email design. She also reports experiments in which teammates coordinate through shared projects or delegate tasks to one another. Those particular workflows are her firsthand observations, not independently verified guarantees of reliability or supported interoperability across every external agent platform.
Her reported interaction between Perplexity Teammates and OpenAI Dots is especially interesting as an illustration of browser-mediated agent collaboration. However, it should not be described as a formally supported cross-platform agent protocol unless both providers document it. Browser interaction can be fragile, permission-sensitive and subject to interface changes.
Perplexity Computer pricing in November 2026
Perplexity's public consumer pricing lists Pro at $20 per month and Max at $200 per month on monthly billing, with lower effective monthly prices available on annual billing. Its current Pro offer advertises a 4,000-credit promotional bonus; Max advertises 10,000 monthly credits and a 35,000-credit promotional bonus for eligible new subscribers. Promotional terms, expiry periods and eligibility can change, so users should check their own account's billing screen before relying on a particular allocation.
Zieminski reports that paid Pro accounts receive weekly Computer usage, consumed before credits, and that Max monthly credits do not roll over. She also describes credit purchase pricing at 100 credits per $1. These are useful operational details from the review, but the exact allowance, purchase conditions, spending cap and credit-expiration rules should be confirmed in the current account interface or Perplexity's help documentation before budgeting.
The critical distinction is between the subscription price and the total task cost. A subscription can grant access to the agent while additional usage consumes a separate allowance or purchased credits. A low headline plan price does not establish the price of a complex dashboard, research report or automation that runs repeatedly.
Why the cost of one task is hard to predict
According to the review, actual Computer usage varied sharply even for superficially similar projects. Zieminski says a dashboard she built consumed 550 credits, while another reviewer completed a dashboard for fewer than 300. Those figures are individual reported runs, not comparable benchmarks: different inputs, model choices, data complexity, iteration counts and output requirements can produce radically different bills.
The review also describes failed or disappointing runs with much higher consumption, including a user-reported outreach workflow that allegedly spent about 15,000 credits without producing usable drafts. This is an anecdote, not a verified distribution of typical task costs. It does, however, illustrate why teams should measure cost per accepted deliverable rather than cost per prompt or number of agent steps.
A task that spends 600 credits and produces a report that needs no revision may be cheaper in business terms than one that spends 200 credits but requires several hours of human repair. Conversely, a task that consumes thousands of credits without meeting its acceptance criteria has poor unit economics even if the agent technically finishes.
Does the effort slider limit spending?
Computer offers effort settings that influence how much reasoning the system uses and which coordinating model handles the task. Zieminski describes Light, Standard, High, Ultra and a Custom option. Perplexity's changelog confirms the addition of effort controls, but an effort preset should not be confused with a hard financial ceiling.
Lower effort may reduce resource consumption for some work, but the total depends on tool use, delegation, retries and task length. Anyone operating under a fixed budget should use the available account spending controls and review the projected work plan, rather than assuming Light means cheap or Ultra means a predictable fixed charge.
Credit controls, paused tasks and refunds
Zieminski reports several budget behaviors that deserve careful attention: included usage may be consumed before purchased credits; exhausted tasks can pause and resume when allowance becomes available; and stopping a task does not automatically refund work already completed. She also reports that Perplexity may refund usage for failures caused by its own infrastructure, such as a sandbox or tool error, while poor-but-technically-completed results may remain billable.
These are descriptions from her review, not universal promises of reimbursement. Refund eligibility, regional consumer rights, account configuration and promotional credits may differ. Keep task IDs, timestamps, error messages and credit-usage records when seeking support. If a task is no longer needed, cancel or delete it where the interface permits rather than assuming a paused task will never resume.
Cloud Computer versus Personal Computer and fully local Mac mode
The November 6 official changelog confirms that fully local Computer is available on supported Apple-silicon Macs running the required app version. Perplexity recommends 36 GB of unified memory for that configuration. Local mode is designed to run the model, agent harness and execution on-device, while Hybrid mode can split work between the Mac and the cloud.
Local execution can materially change privacy and infrastructure trade-offs. However, local mode does not automatically make every connected external service private, nor does it mean every capability available in cloud mode is guaranteed to run identically offline. Users should verify where files, prompts and connector requests are processed before placing sensitive business information into a workflow.
The review also discusses mobile access to cloud Computer and access to local Mac applications. These are distinct execution arrangements. A mobile interface that starts a cloud task is not equivalent to running the model locally on the phone.
Where Computer appears strongest
Zieminski rates Computer particularly highly for research-to-deliverable work: gathering evidence, synthesizing sources, producing reports and creating useful assets. She also praises its browser control. Those judgments come from an experienced user's workflow and should be presented as her assessment rather than proof that Computer is categorically faster or more accurate than ChatGPT, Claude or other agents.
The most credible use cases are tasks with clear input sources, a concrete output format and reviewable success criteria. Examples include a sourced market brief, a competitor monitoring report, a small internal tool, or a structured research packet. In each case, the output can be inspected before a person relies on it or publishes it.
Where it can fail: coding loops, connectors and runaway tasks
The review identifies three recurring problem categories: long coding iterations, unreliable connections to external services and tasks that keep consuming credits without producing acceptable work. These are not unique to Perplexity; they are common failure modes of tool-using agents.
For software tasks, a useful safeguard is to separate specification from implementation. Have the agent produce a plan, define acceptance tests, save the working files and then execute a bounded development task. For connected services, grant only the permissions required. For long-running jobs, establish a maximum acceptable spend, review checkpoints and a clear stop condition.
Do not treat an agent's assertion that it has tested or deployed something as sufficient evidence. Inspect the artifact, run the tests, check the destination system and confirm the requested result yourself.
Security: prompt injection and agent permissions
Research agents read untrusted web pages and documents. An attacker can insert instructions that attempt to make the agent reveal data, change tools or perform actions unrelated to the user's request. Perplexity's November 2026 BrowseSafe++ research reflects the industry's continuing effort to mitigate these risks.
Zieminski also cites security research into browser-agent attacks. The practical implication is to keep untrusted source material separate from operational instructions and restrict access to email, calendars, files and business systems. Use read-only research permissions by default, require approval for external communications or purchases, and review connector scopes regularly.
On data retention, the review states that enterprise data receives different treatment from consumer plans and that consumer users should check their AI Data Retention preference. Because policy language and settings can evolve, consult the current privacy and enterprise documentation rather than assuming the same rules apply across all tiers.
What Computer means for SEO and AI Search
The SEO significance is not that Perplexity Computer introduces a new ranking factor. It is that more discovery and research workflows can be executed by agents that retrieve evidence, compare sources, create summaries and deliver finished work without a traditional search-results visit at every step.
For publishers, that raises questions about source accessibility, attribution and referral measurement. For brands, it increases the importance of consistent, independently verifiable facts across websites, documentation, product pages and trusted third-party sources. For agencies, it creates opportunities to automate repetitive audits while also increasing the need to check the quality of evidence.
A citation in an agent's research packet, an appearance in a final report and an actual website visit are different outcomes. No evidence in the review proves that using Perplexity Computer increases a site's rankings, citations or organic traffic. The product's relevance to GEO is primarily about how information is discovered, synthesized and acted upon.
A practical cost-per-deliverable test
- Choose one repeatable task. For example, produce a ten-source competitive analysis with an executive summary and links to each original document.
- Define acceptance criteria. Specify required sources, output structure, freshness, factual accuracy and the maximum amount of human editing allowed.
- Record the environment. Note the plan, available credits, effort level, enabled connectors and whether the task runs in cloud or local mode.
- Set a spending boundary. Use the account's available cap controls and stop or review the task if consumption exceeds your agreed threshold.
- Run the task. Preserve the final deliverable, task link, elapsed time, credits consumed and any failures or retries.
- Audit the evidence. Open a sample of citations, check factual claims and confirm that requested files or actions actually exist.
- Calculate accepted-output cost. Combine billable usage with the time spent reviewing and correcting the result.
- Repeat on comparable work. A single successful demo is not a reliable estimate of production cost. Compare multiple runs under similar conditions.
- Compare alternatives fairly. Evaluate the same task with other agents, noting differences in subscriptions, usage charges, human intervention and output quality.
Frequently asked questions
Is Perplexity Computer worth using in 2027?
It is worth testing if your work combines research, analysis and deliverable creation. The business case depends on the quality of completed outputs and the total cost of producing them, not the number of features advertised.
What is the difference between Pro and Max?
Perplexity lists Pro at $20 monthly and Max at $200 monthly, with different usage allowances and access levels. Teammates initially requires Max. Check the current pricing and account page for promotional bonuses and credit conditions.
What are Perplexity Teammates?
Teammates are persistent agents for ongoing work. Perplexity says they can coordinate Computer sessions, collaborate with other teammates and follow projects over time. They launched for Max users on the web in November 2026.
Can Perplexity Computer run locally on a Mac?
Yes, on supported Apple-silicon Macs. Perplexity's November changelog recommends 36 GB of unified memory and a compatible version of its Mac app.
Does Light effort guarantee a low bill?
No. Effort settings influence model and reasoning choices, but they are not a fixed per-task price or a substitute for spending controls.
Can a paused task resume and consume more credits?
Zieminski reports that tasks can resume after usage becomes available again. Users should check the current task controls and explicitly cancel work they no longer want completed.
Are failed tasks refunded?
The review says Perplexity may refund usage when failures are caused by its own infrastructure. A disappointing result or user-stopped task does not necessarily qualify. Review the applicable policy and preserve error evidence.
Is Perplexity Computer better than ChatGPT or Claude?
The review expresses a preference for Computer in certain research and browser workflows, but it is not a controlled comparative benchmark. Run equivalent tasks and compare accepted output quality, human review time and total cost.
Can Teammates work with other AI assistants?
The reviewer describes an experimental browser-mediated interaction with OpenAI Dots. That should not be interpreted as a guaranteed, officially supported cross-provider integration.
Does Perplexity Computer change SEO rankings?
There is no evidence that using Computer changes rankings. Its importance for SEO and GEO is as another agent-mediated discovery and research environment that may select and summarize sources.
The verdict: measure completed work, not impressive demonstrations
Perplexity Computer's expansion through 2026 is substantial. The company has documented persistent teammates, broader model and connector support, automations and local execution. Zieminski's sustained usage offers a valuable reality check: the same flexibility that makes the product powerful can also make it hard to budget.
For an analyst, founder or publisher, the right metric is not the number of agents launched or tasks attempted. It is the cost per accurate, accepted, useful deliverable—including credit consumption, subscription cost, review time, retries and security overhead. That is the measure that will determine whether Computer earns a place in a production workflow going into 2027.
Sources
- Karo Zieminski, Product with Attitude — Perplexity Computer, Going Into 2027: Worth It or Credit Furnace? (practitioner review)
- Perplexity — Teammates are agents for complex, ongoing work, November 4, 2026
- Perplexity — Teammates, fully local Computer on Mac, and Voice mode, November 6, 2026
- Perplexity — Official Pro and Max plans
- Perplexity — Computer for Pro subscribers, March 2026
- Perplexity — Product changelog