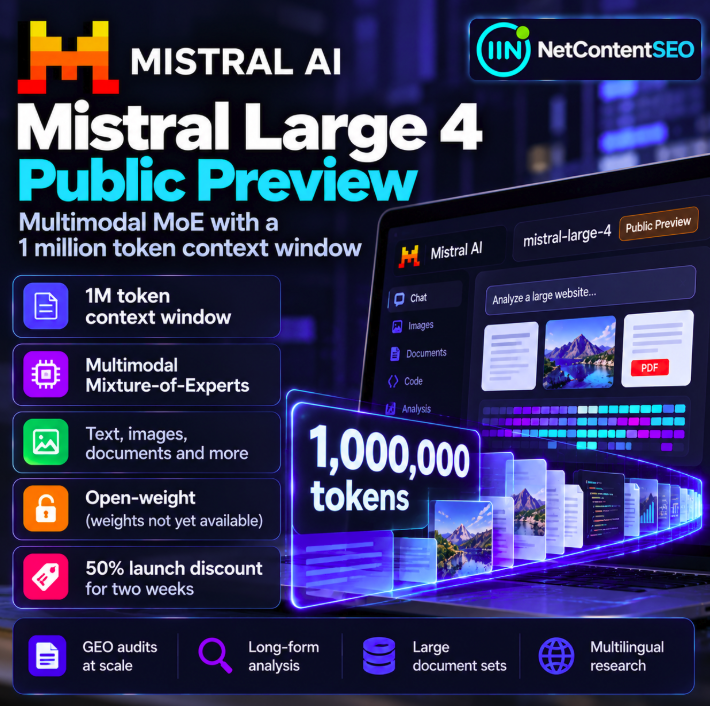
Mistral AI has placed mistral-large-4 in Public Preview, describing a multimodal Mixture-of-Experts (MoE) model with a context window of up to one million tokens. The October 6, 2026 release note also describes an introductory 50% pricing discount for two weeks and positions the model as open-weight. However, the model weights had not been published at the time described in the announcement. That distinction is essential: an open-weight announcement is not the same as downloadable weights being available today.
These release details are based on the official Mistral AI changelog cited in the editorial brief. Availability, pricing, license terms and download status should be checked against the current product documentation before production deployment.
Mistral Large 4: the announced specifications
| Attribute | Reported status |
|---|---|
| Model identifier | mistral-large-4 |
| Release stage | Public Preview |
| Architecture | Multimodal Mixture-of-Experts |
| Maximum context window | 1,000,000 tokens |
| Weights | Described as open-weight, but not yet published in the supplied release information |
| Launch pricing | 50% discount for two weeks, according to the announcement |
| Public search integration | Not announced |
The announcement summary does not provide a verified parameter count, benchmark table, complete list of supported input modalities, or standard per-token pricing. Those details should not be invented.
Why a million-token context window matters
A context window defines the amount of tokenized material a model can process within a single request, subject to its product and API limits. One million tokens potentially accommodates very large document collections, long reports, multiple website exports or extensive technical documentation in one working context.
For SEO and AI visibility research, the attraction is straightforward: fewer arbitrary document splits may be needed when examining interconnected evidence. A team could potentially analyze technical audit reports, content inventories, policy documents and competitive research together rather than preparing a separate prompt for every file.
But maximum context capacity does not guarantee accurate retrieval of every detail inside that context. Performance can vary with document structure, relevant-information placement, input quality and task complexity. A long-context benchmark or real-world evaluation is necessary before concluding that the model can reliably audit an entire website in one pass.
What does multimodal Mixture-of-Experts mean?
A Mixture-of-Experts architecture typically uses routing mechanisms to activate selected parts of a model for a given input, rather than applying every expert component uniformly to every token. The architectural approach can provide a different balance of model capacity and compute. However, the exact routing scheme, number of experts and efficiency of Mistral Large 4 are not specified in the supplied announcement.
Multimodal capability means the model is designed to work with more than one type of input or information representation. The precise supported modalities, file formats and limits should be verified in Mistral's API documentation rather than inferred from the word 'multimodal' alone.
Potential application: large-scale GEO audits
Generative Engine Optimization (GEO) research often requires combining many sources: website content, structured data, brand and entity descriptions, citation observations, competitive positioning and historical changes. A large context window could make some cross-document comparisons easier.
1. Analyze large content inventories
A model could be prompted to compare article groups, detect repeated claims, identify conflicting descriptions and suggest editorial priorities across a large corpus. The input should include stable URL identifiers and publication dates so findings can be traced back to specific pages.
2. Compare entity consistency
Teams could supply About pages, author biographies, organization descriptions and structured-data exports to identify inconsistencies in names, roles, locations or brand relationships. This is an audit of supplied material, not proof that any AI search engine has indexed or understood the same information.
3. Review citation evidence
Researchers could analyze a collection of observed AI answers and citations, looking for patterns in which pages or brands are referenced. That requires an independently collected and accurately timestamped dataset. A model's own narrative about citation patterns is not a substitute for verified observations.
4. Cross-check technical and editorial findings
Long-context analysis may help correlate crawl exports, indexing reports, content quality assessments and change logs. It can generate useful hypotheses, but causal claims about ranking losses still require direct evidence and controlled comparisons.
A practical workflow for testing a million-token GEO audit
- Define the research question. For example, compare entity descriptions across site sections or identify content that conflicts with documented product specifications.
- Prepare a traceable corpus. Assign each document a URL or file ID, collection date and content type.
- Preserve the original evidence. Avoid stripping away the context needed to interpret a quote, table or structured-data field.
- Run a smaller baseline. Test the same questions on a representative subset before attempting the largest possible context.
- Require source references. Ask the model to cite the supplied document IDs and quote only evidence it actually finds.
- Validate samples manually. Check claimed contradictions, missing details and priority recommendations against source files.
- Measure cost and latency. Large prompts can be expensive or slow even when technically supported.
The most useful comparison is not simply how much text fits, but whether the larger context improves evidence coverage without reducing precision.
Public Preview versus open-weight availability
The announcement's open-weight positioning deserves careful interpretation. A model may be announced as open-weight while its downloadable artifacts, license and deployment instructions are still pending. As described in the supplied October 6 release information, the weights had not yet been published.
Consequently, developers should not describe the model as already self-hostable without confirming an official weights release and applicable license. Public Preview access to a hosted model and availability of downloadable weights are separate questions.
How to interpret the 50% launch discount
Mistral reports a 50% introductory price reduction lasting two weeks. That is a temporary promotional term, not necessarily the long-term cost of using the model. Before calculating project budgets, verify the exact applicable dates, eligible endpoints, input and output token rates, and whether the offer remains active.
Even with a discount, the total cost of a million-token workflow depends on how many tokens are sent, how much output is generated, and how often the analysis is repeated. The supplied release summary does not include verified numerical per-token prices, so none are asserted here.
Does Mistral Large 4 power any public search or citation system?
No such integration is confirmed in the supplied announcement. A model's capability to analyze large documents does not establish that it is being used by a public search engine, an AI answer engine, a crawler or a citation-selection pipeline.
For SEO and GEO professionals, this distinction prevents an important category error: a model being useful for visibility research does not mean that model determines visibility in a public search product. No ranking or citation impact should be attributed to this release without separate evidence.
What SEO teams should test before adoption
- Accuracy of findings when relevant evidence is buried deep in a long context.
- Consistency of source attribution and document-ID references.
- Support for the actual image and document formats used in the audit.
- API throughput, latency and costs for repeated large requests.
- Handling of confidential data and the applicable preview terms.
- Reproducibility compared with smaller-context or retrieval-augmented workflows.
FAQ
When did Mistral Large 4 enter Public Preview?
October 6, 2026, according to the supplied official changelog summary.
What is its context window?
Up to one million tokens, as announced.
Is Mistral Large 4 multimodal?
Yes, the release describes it as a multimodal Mixture-of-Experts model. Confirm specific supported modalities in the technical documentation.
Are the open weights available to download?
The supplied release information says the model is described as open-weight but its weights had not yet been published. Check the latest official status.
How long is the launch discount?
The announcement describes a 50% discount for two weeks. Exact eligibility and current pricing should be confirmed directly.
Will the model improve my website's AI citations?
There is no evidence in the supplied announcement of a change to any public AI search or citation system.
NetContentSEO analysis
Mistral Large 4's million-token context window could be valuable for large-scale GEO auditing, provided its real-world accuracy, traceability and economics hold up under testing. The release is important as a new analytical capability, not as a confirmed search ranking event. Researchers should evaluate how reliably it handles large evidence sets while keeping model availability, open-weight publication and public search integration clearly separate.
Primary source: Mistral AI — Changelog, October 6, 2026.