

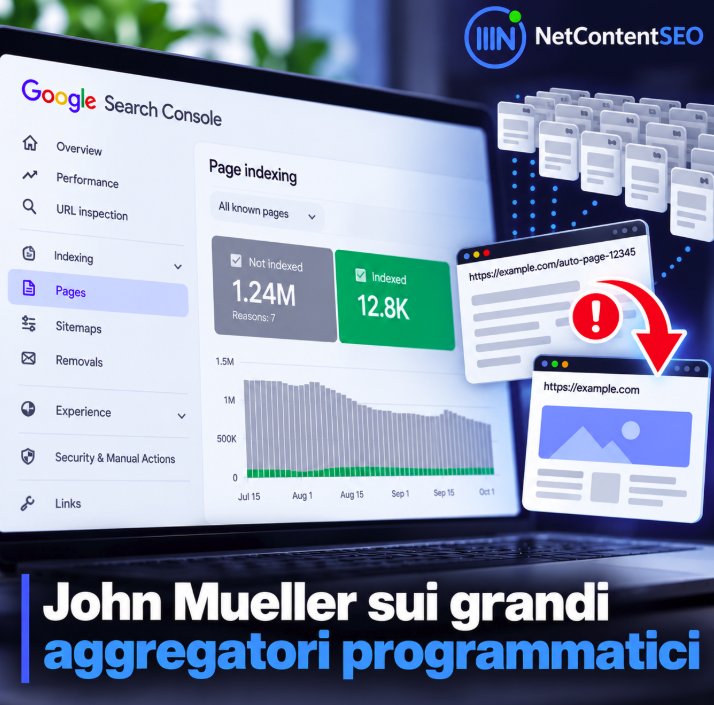

Large-scale programmatic publishing does not become valuable simply because Google crawls a large number of its URLs. That is the central point in a recent public comment from Google's John Mueller about a large aggregator generating substantial volumes of programmatic or automatically created pages.
Mueller's comments, made on October 4, 2026 and resurfacing on October 6, focus on a familiar problem for large aggregators: extensive crawling can coexist with extremely limited indexing. For sites operating at this scale, the challenge is not merely getting Googlebot to discover and fetch URLs. The site has to demonstrate why those pages deserve to exist in Search.
Crawling is not evidence of indexable value
Programmatic SEO systems can create enormous URL inventories. Templates, location combinations, product attributes, datasets and automatically generated landing pages can easily produce hundreds of thousands or millions of crawlable URLs.
But crawl activity should not be confused with an endorsement of those pages. Google may discover and revisit large portions of a site while choosing to index only a small fraction. When that happens, increasing crawl access or generating even more URLs does not address the underlying question: what unique value does each page provide to users?
Large aggregators have to prove their usefulness
Mueller's framing is particularly relevant to aggregators because their pages often depend on data available elsewhere. At scale, small differences between URLs can produce pages that are technically unique but functionally interchangeable.
A strong programmatic page therefore needs more than a unique URL and a populated template. Useful aggregation, meaningful comparisons, original analysis, genuinely helpful filtering, proprietary data, editorial context or another clear user benefit can help explain why the page deserves to be indexed rather than treated as one more variation in a massive URL set.
Anomalous redirects add another warning signal
The case discussed by Mueller also included unusual behavior in which indexed URLs redirected users to the homepage. That creates a separate technical concern. If pages that Google previously considered indexable no longer resolve to an equivalent destination and instead collapse into a generic homepage redirect, the site's URL architecture and lifecycle deserve investigation.
Redirects should preserve meaningful destination equivalence whenever possible. Sending large numbers of unrelated or expired URLs to the homepage can obscure what happened to the original content and may create a poor experience for both users and crawlers.
Why crawl-heavy, index-light sites need a different diagnosis
When Googlebot is crawling heavily but indexing remains close to zero relative to the site's total inventory, the first instinct is often technical: crawl budget, sitemaps, internal linking, rendering or server behavior. Those checks still matter, but they cannot solve a value problem on their own.
The more important audit is often at the content-system level. How many URLs answer essentially the same intent? How much information is unique to each page? Does the page offer something users could not obtain from the source data or competing aggregators? Are empty or weak combinations being generated automatically? Are obsolete URLs handled coherently?
Programmatic SEO should scale usefulness, not just URLs
The lesson is not that programmatic SEO is inherently problematic. Automation can produce highly useful pages when the underlying dataset, template logic and editorial design create a genuinely valuable result for each search intent.
But scale magnifies weaknesses as efficiently as it magnifies value. If a template produces thin or repetitive pages, generating a million instances creates a million variations of the same problem.
For large aggregators, the practical takeaway from Mueller's comments is straightforward: discovery and crawling are only the beginning. Sustainable indexing requires a convincing reason for Google—and ultimately users—to treat those programmatically generated URLs as useful destinations in their own right.