Google researchers have published a system that reframes the fight against mass-produced synthetic content as a network-forensics problem rather than a page-by-page classification task. SAFE, short for Scaled Abuse Forensics Examiner, is an automated multi-agent architecture designed to investigate coordinated campaigns of adversarial synthetic media—the phenomenon the paper explicitly describes as “AI slop.” Google Research’s official publication page describes the system and reports results from early deployment.
The important boundary is equally clear. Google’s publication discusses abuse forensics for synthetic-media campaigns. It does not say SAFE is a Google Search ranking system, does not state that it directly evaluates webpages in Search and does not connect the architecture to Google’s September 2026 spam update. Any automatic claim that SAFE explains current Search ranking volatility would therefore go beyond the published evidence.
What the research does provide is a useful technical model for understanding why AI-generated spam increasingly has to be investigated above the level of an individual piece of content. When adversaries can cheaply create thousands of unique, localized variations, exact duplication becomes a weaker signal. Coordination—who publishes what, when, through which channels and in what recurring behavioral pattern—becomes much more revealing.
AI slop breaks simple duplicate-content assumptions
Google’s researchers frame the problem around generative AI’s ability to flood platforms with mass-produced, low-quality synthetic media. The campaigns can distribute unique and localized versions of content across coordinated networks, which means the abusive material does not necessarily fall into a single repetitive-content cluster.
That creates what the paper calls a recall gap. Traditional static detection may identify some suspicious items while missing others because the individual pieces are not sufficiently identical. The actors behind them, however, can still exhibit related patterns of behavior that become visible during forensic investigation.
This is the central strategic shift behind SAFE: instead of asking only whether one video, page or media item looks synthetic or violates policy, the system asks whether multiple channels and behaviors form a coordinated abuse pattern.
SAFE decomposes the investigation into specialized agents
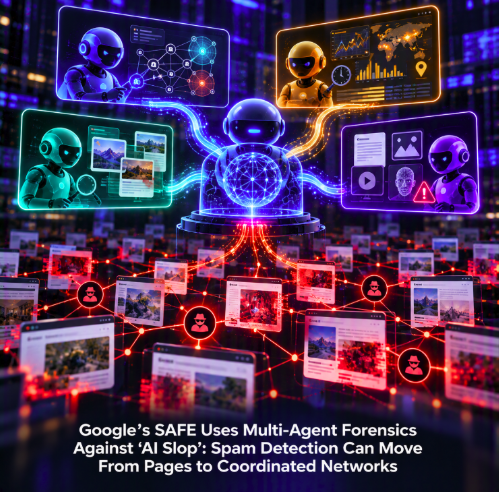
Google describes SAFE as a multi-agent architecture in which different agents handle distinct parts of the forensic investigation. A Cluster Understanding Agent analyzes relationships between channels inside a cluster. A Behavior Understanding Agent looks for inorganic spatiotemporal patterns. A Content Understanding Agent analyzes the media itself using LoRA-adapted large language models and few-shot learning. A Root Agent then synthesizes those signals into a final verdict.
The architecture is important because no single signal has to carry the entire decision. Content can look superficially unique while behavior remains coordinated. Channels can appear separate while their relationships expose a common campaign. Timing and geography can reveal inorganic activity even when individual items evade similarity-based detection.
The Root Agent’s role is therefore closer to a forensic coordinator than a simple content classifier. It combines evidence produced by specialized investigators before rendering the system-level judgment.
Content is only one layer of the evidence
The Content Understanding Agent remains important. Google says it uses LoRA-adapted LLMs and few-shot learning to identify existing policy violations and what the paper calls violations of the “spirit” of policy.
But SAFE’s design makes clear why content inspection alone is insufficient. Generative systems make variation cheap. An operator can alter wording, visuals, language, location references and presentation while preserving the same underlying campaign objective.
Behavioral and relational signals are harder to disguise at unlimited scale. Coordinated publishing schedules, repeated cross-channel structures and other inorganic patterns can remain visible even after the content itself has been diversified.
The target is the campaign, not merely the artifact
This difference matters for anyone thinking about the future of spam detection. A classifier operating on one artifact effectively asks, “Is this item abusive?” A forensic network system can ask a broader question: “What coordinated operation does this item belong to?”
That second question creates different detection possibilities. A single item might be ambiguous in isolation but become suspicious when placed beside dozens of related channels exhibiting the same behavioral signature. Conversely, a piece of AI-generated media is not automatically abusive merely because it was produced synthetically; the relevant context is the campaign, behavior and policy implications around it.
SAFE therefore should not be summarized as an “AI-content detector.” Google’s own description is more specific: it is an automated architecture for scalable forensics of adversarial synthetic media.
Google reports early deployment results
The research is not presented solely as a laboratory proposal. Google says early deployment results indicate that SAFE significantly accelerates the identification of novel synthetic threats and reduces forensic investigation time compared with human-in-the-loop workflows.
That is meaningful, but the wording should be preserved carefully. The public abstract does not provide enough information to convert “significantly accelerates” into a universal percentage improvement, nor does it establish performance across every form of synthetic abuse. It reports early deployment results for the system described by the researchers.
The operational value is straightforward: generative abuse can be produced at machine speed, while purely manual forensic investigation does not scale at the same rate. SAFE uses agents to automate parts of the investigation process so human teams are not required to manually reconstruct every relationship from scratch.
This is consistent with Google’s broader human-plus-AI safety model
Google’s wider safety documentation describes automated systems and human expertise as complementary rather than mutually exclusive. The company says AI plays an important role in identifying potentially violative content at scale while human review remains important for nuanced enforcement decisions. Google’s AI safety overview describes this as combining automated safeguards with human insight and large-scale review operations.
SAFE fits that broader operational logic. Its value is not necessarily eliminating investigators; it is compressing the forensic workload so coordinated threats can be surfaced faster and at greater scale.
Why the architecture matters for the web even without a Search ranking connection
The paper concerns synthetic-media abuse and does not establish that SAFE is used by Google Search. Still, the architecture illustrates a broader anti-abuse principle relevant to web publishers: evaluating one URL in isolation becomes less useful when adversaries operate coordinated publishing systems.
A modern synthetic-content operation can control multiple domains, accounts, channels and identities while generating superficially distinct material for each. Looking only for duplicate paragraphs or identical images misses the organizational structure behind the operation.
Network-level analysis instead creates the possibility of detecting shared behavior across assets that individually look different. That conceptual shift—from artifact similarity to coordinated activity—is the most transferable lesson from the research.
The paper does not prove that Google Search evaluates publisher networks this way
This is where interpretation needs restraint. SAFE’s existence does not demonstrate that Google Search’s ranking systems are applying the same architecture to websites. Google has not said that the Cluster Understanding Agent, Behavior Understanding Agent, Content Understanding Agent or Root Agent described in the paper participates in Search ranking or spam enforcement.
It would therefore be incorrect to tell publishers that a site lost rankings because SAFE connected it to an AI-content network. The paper supplies no evidence for such a diagnosis.
It is equally unsupported to claim that SAFE caused or powered the September 2026 Google Search spam update. The research and the Search update may both concern abuse at a high level, but thematic proximity is not technical evidence of integration.
Do not reverse-engineer the September spam update from SAFE
The timing makes the temptation understandable. Google’s September spam update and a research paper about scalable AI-slop forensics both appeared in the same broader period, and publishers are actively trying to understand how Google responds to industrialized generative content.
But a research publication can describe systems built for a different product, enforcement surface or internal workflow. Unless Google explicitly connects the technologies, using one document to explain Search ranking behavior creates a causal story that the evidence does not support.
For SEO analysis, the safer approach is to keep the two evidence streams separate: evaluate Search updates through Google Search documentation, observed ranking data and confirmed Search statements; evaluate SAFE as an official Google research and abuse-forensics architecture.
The architecture makes “unique content” a weaker defense against abuse detection
One important conceptual implication is that superficial uniqueness is not the same as independence. Generative systems can produce thousands of distinct versions without changing the fact that the publishing operation is coordinated.
For legitimate publishers, this is not a reason to fear shared ownership, common infrastructure or normal editorial workflows. SAFE’s research target is adversarial synthetic-media abuse, not ordinary multi-site publishing. The paper does not provide a checklist of Search penalties for publishers.
For abusive operators, however, the research demonstrates why simply paraphrasing every output may not solve the detection problem. If a system can reason over behavioral and relational evidence, exact-text uniqueness stops being the decisive variable.
AI-generated content and AI-enabled abuse are not synonymous
The phrase “AI slop” can easily encourage an overly broad conclusion that synthetic content itself is the target. Google’s research framing is narrower: malicious actors use generative capabilities to mass-produce low-quality synthetic media and coordinate its distribution in ways that overwhelm conventional integrity systems.
The abuse problem therefore includes intent, scale, coordination, policy violations and behavior—not merely the presence of generative technology in a production workflow.
That distinction is important for editorial organizations increasingly using AI for translation, research assistance, transcription, formatting or other production tasks. SAFE does not provide evidence that the use of AI alone marks a publisher as abusive.
Multi-agent defense mirrors multi-agent production
There is a broader technical symmetry in the paper. The same AI advances that allow attackers to automate content production can also allow defenders to automate investigation. Instead of one monolithic model attempting to solve every forensic task, SAFE assigns specialized roles and then combines their outputs.
This resembles a growing pattern in agentic systems: decomposition can outperform asking one model to reason over an entire complex workflow without specialization. Relationship analysis, behavioral analysis and content analysis require different evidence and different reasoning steps.
The Root Agent then becomes the synthesis layer, converting those separate perspectives into one coordinated assessment.
The SEO lesson is architectural, not algorithmic
For search marketers, SAFE is useful precisely when its limits are respected. It should not be treated as a leaked Search ranking factor or a hidden explanation for current SERP movements.
Instead, it shows how sophisticated abuse detection can move beyond evaluating the visible artifact and toward reconstructing the system that produced and distributed it. In an era when generating another unique page, video or localized variation costs almost nothing, the network surrounding the content may contain more durable evidence than the content itself.
Google has now documented one concrete multi-agent architecture built around that principle and says it has early deployment results. What Google has not documented is a direct bridge from SAFE to Search ranking. Keeping those two facts separate produces a more useful conclusion than forcing the research into an SEO update narrative: the future of AI-abuse detection can be network-aware even when the evidence does not show that a particular Search algorithm already works that way.