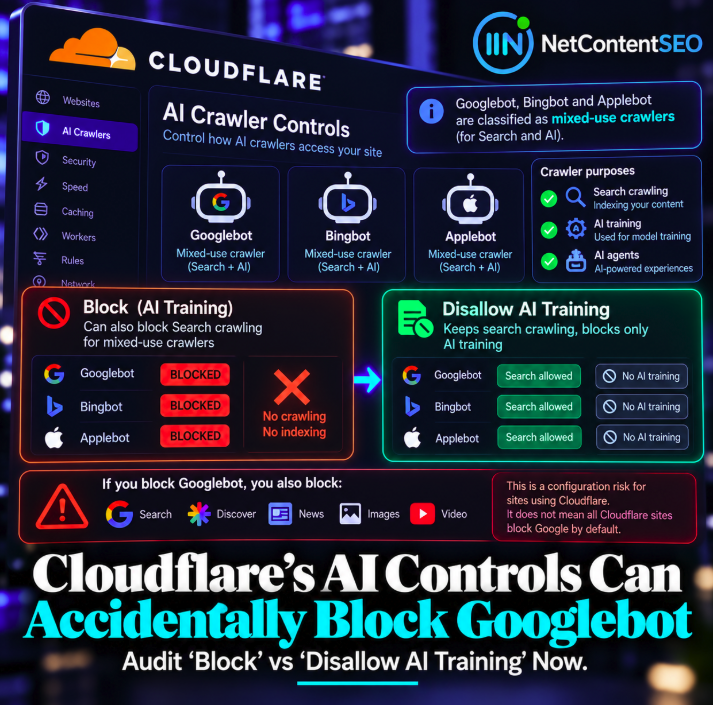
A setting intended to protect content from AI training can become a serious Search crawling problem if the wrong Cloudflare control is selected.
Since September 15, 2026, Cloudflare explicitly treats Googlebot, Bingbot and Applebot as mixed-use crawlers: the same crawler identities can support traditional search while their operators also have AI-related uses and controls.
The important distinction is now between Cloudflare's Block setting and its newer Disallow AI Training setting.
“Block” now means exactly what it sounds like
Cloudflare's September 15 documentation says that Block and Block on pages with ads apply to mixed-use crawlers, including Googlebot, Bingbot and Applebot.
If a site selects Block for these crawlers, Cloudflare can stop them from reaching the site entirely — including their search-crawling function.
This is not merely a robots.txt preference. It is an enforced access decision at Cloudflare's edge.
Googlebot is not just an AI-training crawler
Googlebot is the crawler Google uses for Search.
Google's own documentation states that blocking Googlebot affects Google Search, including Discover and Search features, as well as Google Images, Google Video and Google News.
For a site that depends on organic discovery, an accidental edge-level Googlebot block is therefore potentially much broader than losing eligibility for one AI feature.
Blocking crawling is not identical to instant deindexing
The SEO consequence needs one important qualification.
Blocking Googlebot does not necessarily erase every URL from Google's index immediately. Google explicitly distinguishes crawling from indexing, and an inaccessible URL can sometimes remain known to Search for a period of time.
But Google's technical requirements for normal indexing include Googlebot being able to access the page, and sustained blocking prevents Google from recrawling content, processing changes and reliably maintaining indexed documents.
So “accidental deindexing” is a legitimate long-term risk, but it should not be interpreted as an instantaneous site-wide removal the moment the Cloudflare toggle changes.
Cloudflare created “Disallow AI Training” to solve this conflict
The new Disallow AI Training option is specifically designed for publishers that want to refuse model training without sacrificing search discoverability.
Cloudflare says Google, Apple and Microsoft either honor or have committed to honoring the corresponding training preferences.
Under this configuration, Googlebot, Applebot and Bingbot can continue crawling for Search while the site expresses that its content should not be used for AI training.
For Google, the separation uses Google-Extended
Cloudflare notes that Google allows publishers to express a training preference through Google-Extended.
This lets a publisher restrict certain generative-AI uses without blocking Googlebot's core Search crawling.
Google has also stated that disallowing Google-Extended does not affect traditional Search ranking.
That separation is exactly why blocking Googlebot itself is unnecessarily destructive when the publisher's actual objective is only to refuse AI training.
Bing and Apple have their own mechanisms
Cloudflare's accountable-crawler framework also recognizes controls from Microsoft and Apple.
Apple exposes Applebot-Extended for training preferences, while Microsoft provides AI-related controls through its own systems.
The implementation details differ, but Cloudflare's objective is the same: preserve Search crawling while respecting a publisher's separate AI-training preference.
Why Cloudflare calls them “mixed-use” crawlers
The distinction matters because older bot-control models often categorized a crawler according to a single assumed purpose.
That becomes unreliable when one crawler participates in several workflows.
Cloudflare says mixed-use crawlers represented 36.6% of verified crawler traffic on its network when it introduced the new controls.
A binary “AI bot / not AI bot” classification is therefore no longer precise enough for modern crawler governance.
Search, training and agents are now separate controls
Cloudflare replaced its old broad “Block AI Bots” approach with more granular controls for Search, AI Training and AI Agents.
This is the architectural change SEO teams need to understand.
A publisher may want traditional Search discovery, reject training and separately decide whether AI agents can interact with the site.
Those are three different policy decisions and should not be collapsed into one generic “block AI” rule.
Bot Preference Sync adds another layer
Cloudflare is also replacing Managed Robots.txt with Bot Preference Sync.
The feature can reflect the site's configured crawler preferences through robots.txt and supported content signals.
This helps keep declared preferences and Cloudflare's enforcement configuration aligned.
But teams should still audit the effective result rather than assuming a dashboard label always produces the intended Search behavior.
Existing sites were not simply switched to blocking Google
This point is critical because the September change can easily be misreported.
Cloudflare did not announce that every Cloudflare site, or every site that previously rejected AI training, would suddenly block Googlebot.
Cloudflare says existing customer preferences were migrated, and the new Disallow AI Training setting was introduced precisely to preserve Search access while refusing training.
The risk arises when a site is configured with the enforced Block option for mixed-use crawlers.
Cloudflare’s recommended defaults are also nuanced
For certain new advertising-supported sites, Cloudflare recommends keeping Search crawling enabled while disallowing AI training and blocking AI agents on ad-carrying pages.
For other new sites, Cloudflare's recommended configuration can allow Search, training and agents.
Again, there is no universal “Cloudflare blocks Google” default.
How to audit the setting
Technical SEO teams using Cloudflare should inspect the current AI crawler configuration and identify whether Googlebot, Bingbot or Applebot are subject to an enforced Block rule.
If the objective is only to prevent AI training while preserving organic discovery, the relevant configuration is Disallow AI Training, not a blanket Block.
The effective robots.txt and Bot Preference Sync output should also be reviewed.
Verify Googlebot from Google's side too
After changing crawler controls, do not rely exclusively on Cloudflare's interface.
Use Google Search Console's URL Inspection tool to test a representative live URL and verify that Googlebot can access it.
Search Console's Crawl Stats and Page Indexing reports can help identify wider access anomalies.
Server and Cloudflare logs can provide additional evidence that verified Googlebot requests are receiving successful responses rather than 403s or other blocks.
Watch for false conclusions from robots.txt alone
A robots.txt file can say that Googlebot is allowed while a Cloudflare security rule still rejects the request before the origin serves the page.
Conversely, robots.txt can disallow crawling even when the network layer technically permits the request.
For that reason, crawler auditing needs to cover both declared policy and actual HTTP access.
The broader SEO lesson: AI governance is now technical SEO
AI crawler controls are increasingly being configured by security, infrastructure, legal or privacy teams rather than SEO teams.
But those controls can directly alter crawlability.
A perfectly optimized page cannot rank normally if the infrastructure prevents the search crawler from retrieving it.
AI policy therefore needs an SEO change-management process: document the intended purpose, understand which crawler identities are affected, test before and after deployment and monitor Search Console for unintended consequences.
NetContentSEO take
The dangerous setting is not “refuse AI training.” It is using an enforced crawler Block when you only intended to refuse training.
Cloudflare's September 15 controls finally make that distinction explicit for mixed-use crawlers such as Googlebot, Bingbot and Applebot.
For publishers that want Search visibility but do not want their content used for AI training, Disallow AI Training is the relevant path.
Audit the configuration now — and verify the result with a real Googlebot access test. In crawler governance, one overly broad toggle can become an indexing incident.