Before a publisher builds and maintains a second Markdown version of an entire website for AI crawlers, there is a simpler technical question worth answering: are the crawlers visiting that site actually asking for Markdown?
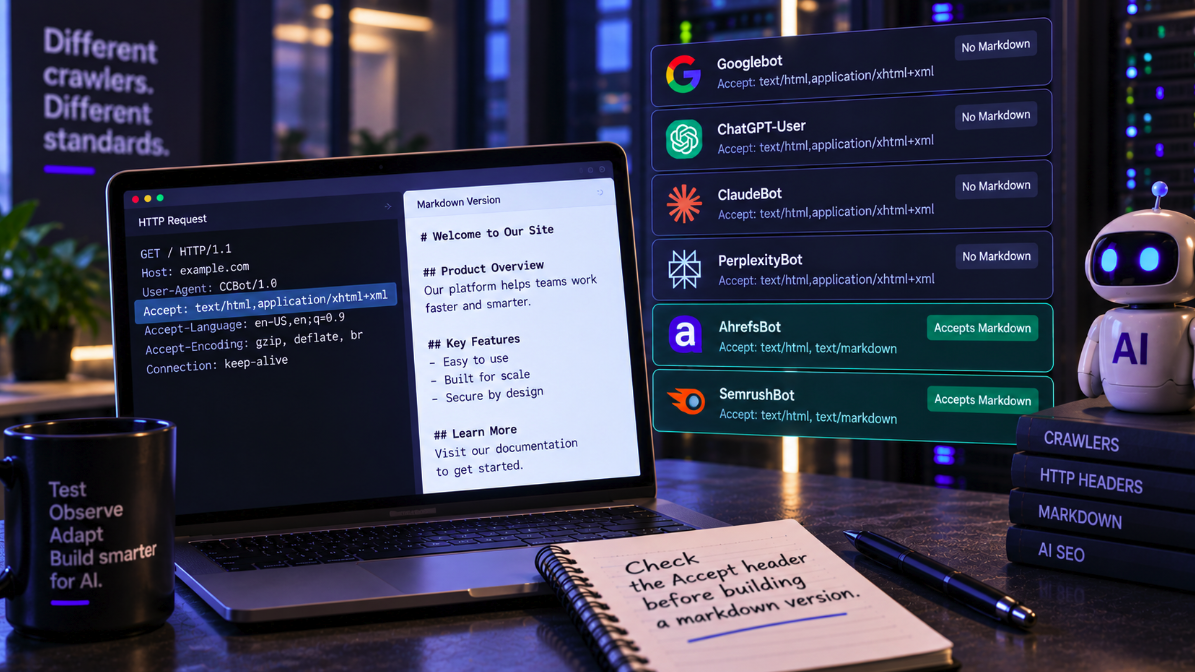
Google’s John Mueller recently checked that question on his own test sites and reported an unexpectedly narrow result. In a discussion covered by Search Engine Journal on August 31, Mueller said that the only crawlers he saw claiming to accept Markdown were SEO tools. He added an important qualifier—results can vary—and recommended that site owners log the HTTP Accept header and inspect their own data before investing in a Markdown delivery layer.
That recommendation is more useful than a blanket verdict about whether Markdown is good or bad for AI SEO. It turns an increasingly fashionable optimization idea into a measurable infrastructure question.
Mueller reported an observation, not a universal rule
The discussion began on Reddit’s TechSEO community, where a site owner asked whether anyone had actually seen a major AI bot request Markdown. The publisher was already caching HTML and considered generating smaller Markdown versions partly to reduce the server load caused by aggressive AI crawling.
In his original Reddit response, Mueller said that on his test sites the crawlers declaring Markdown support were SEO tools. He did not claim to have audited every AI crawler, and he explicitly cautioned that other sites may see different behavior.
That distinction matters. Mueller’s server logs are evidence about his test environment, not a specification for ChatGPT, Claude, Perplexity or every other AI product. The correct takeaway is therefore not “AI bots never request Markdown.” It is that publishers should verify demand on their own infrastructure rather than assuming it exists.
The Accept header can reveal what a crawler says it can consume
HTTP already has a mechanism for a client to tell a server which response formats it is prepared to accept. The Accept request header can contain media types such as text/html, application/json or text/markdown. A server can inspect that preference and, where content negotiation is implemented, choose an appropriate representation.
That makes the header a natural place to investigate whether a bot is expressing a preference for Markdown. If an AI crawler repeatedly requests pages but never advertises text/markdown in the relevant header, building an automatic Markdown response specifically for that crawler becomes harder to justify on content-negotiation grounds.
Mueller noted a practical obstacle: his normal server setups did not log the Accept header by default. He therefore had to configure logging manually just to see which clients claimed to support the format. His recommendation to other site owners was essentially to do that measurement work first and then evaluate the metrics.
Logging before building is a better engineering sequence
The order of operations is important. Generating Markdown versions can sound trivial when a CMS already has structured content, but a production implementation creates additional questions. Which representation is canonical? Are links and structured elements preserved correctly? Will the Markdown remain synchronized with the HTML? How will caches vary by request header? What happens to analytics and debugging when different clients receive different representations?
Those costs may be justified when there is measurable demand. They are harder to defend when the target clients are not requesting the alternative representation in the first place.
A useful first experiment is therefore observational rather than architectural. Add the Accept header to request logs, identify verified crawler user agents carefully, measure the relevant traffic over a representative period and inspect whether text/markdown appears. Only then does it make sense to estimate whether the traffic volume and potential bandwidth savings justify implementation.
Requesting Markdown and fetching a Markdown URL are not identical
There is another technical nuance that can easily get lost in the debate. A crawler can fetch a URL ending in .md without having requested Markdown through content negotiation. Likewise, a client can advertise text/markdown in an Accept header while requesting an ordinary webpage URL.
Those behaviors answer different questions. If a publisher is considering an alternative URL structure such as /page.md, access logs for those URLs matter. If the plan is to serve Markdown dynamically from the same URL when a client requests it, the Accept header becomes central.
Conflating the two can produce misleading conclusions. Seeing a bot fetch one Markdown file does not establish that it prefers Markdown for ordinary crawling, while failing to see requests for explicit .md URLs does not prove that no client would accept the format through negotiation.
Cloudflare has made Markdown delivery easier, but capability is not demand
The topic has become more prominent because infrastructure vendors can now automate much of the conversion. Search Engine Journal notes that Cloudflare offers a Markdown-for-agents capability that can convert HTML into Markdown when a requesting client expresses the appropriate preference through content negotiation.
That reduces the engineering burden, but it does not eliminate Mueller’s measurement question. The fact that a server can generate Markdown efficiently does not show that the crawlers a particular site cares about are asking for it. Availability and demand are separate variables.
This is a recurring pattern in AI optimization. A new technical capability can quickly become a recommended checklist item before evidence exists that the target systems depend on it. Server logs provide a useful corrective because they show what clients actually requested from the site rather than what publishers assume they want.
Google has already urged caution around parallel Markdown sites
Mueller’s latest observation fits a broader pattern of caution from Google around bot-specific Markdown strategies. In June, Search Engine Journal reported comments from Mueller and Google’s Martin Splitt questioning the need to maintain parallel Markdown versions of ordinary webpages for AI SEO. The concern was not that Markdown itself is technically invalid, but that publishers can add complexity without a demonstrated search benefit.
That earlier discussion is covered in Search Engine Journal’s report on Markdown versions for AI SEO. The argument is especially relevant for websites whose normal HTML already exposes the main content cleanly to crawlers. Modern retrieval systems are built to process web pages; a second representation is not automatically a visibility advantage.
There are also synchronization risks. If the HTML page and Markdown representation drift apart, publishers create uncertainty about which version contains the authoritative information. A system introduced to simplify machine consumption can end up increasing operational complexity for the site owner.
Markdown can still be useful without being an AI-ranking tactic
None of this makes Markdown obsolete. It remains an extremely useful format for documentation, repositories, developer workflows and agent instructions. Search Engine Journal has previously reported Mueller’s explanation that Markdown can be helpful for developer documentation consumed by coding tools because a compact text representation can reduce unnecessary processing.
The distinction is between a format being useful to AI systems and a format providing a general AI-search optimization advantage. Those are not the same claim.
Agent frameworks can explicitly define Markdown files as part of their workflow. Coding systems may be designed to read repository instruction files. Developers may prefer Markdown because it is portable and easy to version. None of those use cases proves that public web crawlers need every website to publish a second Markdown edition in order to understand or cite its content.
Bandwidth savings are a separate business case
The original Reddit question also raised a different motivation: server efficiency. A stripped-down Markdown response can be substantially smaller than a webpage containing HTML structure, scripts, styles and interface elements. For a site experiencing heavy automated traffic, reducing transferred bytes could have operational value even if rankings and citations do not improve.
That business case should also begin with measurement. How much traffic comes from the bots in question? How large are current responses? Are those crawlers requesting Markdown? Would caching or compression solve more of the problem with less complexity? Is the bot traffic valuable enough to permit at all?
A publisher may ultimately decide that Markdown delivery is worthwhile for infrastructure reasons. That is a valid outcome, but it should not be mislabeled as proven GEO or AI-ranking optimization.
Logs can replace speculation with site-specific evidence
The strongest part of Mueller’s August 31 comment is methodological. AI-search optimization is developing faster than public crawler documentation, and publishers are frequently asked to implement files, headers and alternative content formats before their practical effects are clear. In that environment, first-party server data becomes unusually valuable.
Instead of asking whether “AI bots” as a single category want Markdown, a site can ask which identifiable clients reach its pages, what they request, how often they return and which media types they declare. The answer may differ by crawler, by site and over time.
That also makes the implementation reversible. If logs later show a meaningful rise in requests advertising text/markdown, a publisher can revisit the decision with evidence. There is little advantage in paying the maintenance cost months in advance merely because a future crawler might eventually use the format.
Measure the request before optimizing the response
Mueller’s test does not settle the Markdown-for-AI debate, and it should not be presented as a formal Google position. It is a personal observation from test sites: the crawlers he saw claiming Markdown support were SEO tools, not the major AI bots the Reddit discussion was concerned about.
But the practical recommendation travels well beyond his sample. Before building a parallel content format for machines, inspect whether those machines are signaling that they want it. Configure the logs, capture the Accept header, verify the crawler identities and quantify the demand.
If the data shows real Markdown requests, publishers can evaluate the cost and benefit of serving them. If it does not, the site has avoided building infrastructure for a theoretical audience. In a field crowded with speculative AI-SEO requirements, that is a useful default: measure the crawler first, then optimize the response.