Marketing agents are moving from answering questions to recommending actions, and that shift changes what “trust” should mean. A chatbot that summarizes a report can be checked after the fact. An agent that proposes an audience, budget decision or campaign action needs a more operational form of transparency: marketers need to see what signals informed the recommendation, what population it would affect and what trade-offs they are accepting before anything is activated.
That is the argument behind a sponsored Search Engine Land article from Rokt mParticle about its new agentic segmentation workflow. The product is presented as an AI assistant that explores a company’s own event and customer data, turns a marketing objective into a proposed audience and exposes enough context for a marketer to inspect the recommendation before approving it. Because the source is sponsored vendor content, it should be read as a product and governance thesis rather than independent evidence that the system improves campaign performance.
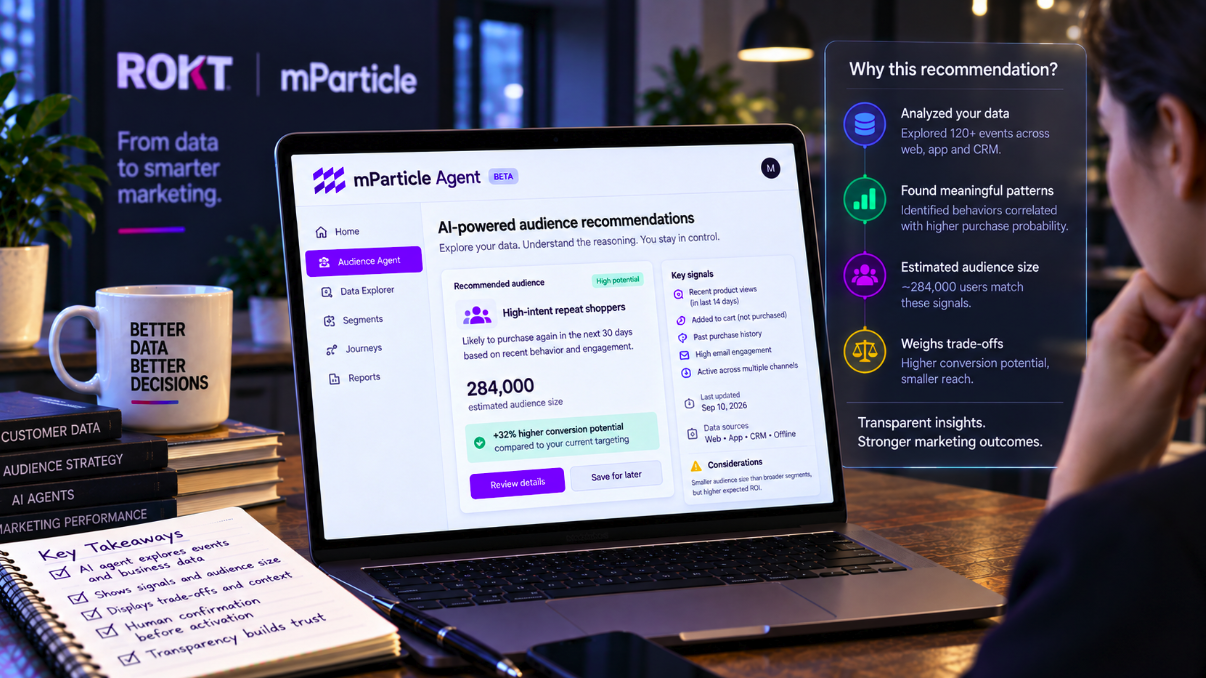
Current mParticle documentation for the Audience Agent makes the mechanics more concrete. A marketer can describe a goal such as reaching users who lapsed after a first purchase, and the agent searches data-catalog metadata, aggregate metrics, saved audience context and data available under that user’s existing permissions. It then proposes audience criteria, explains which signals it selected and why, and can display an estimated audience size when that information is available. The marketer reviews and refines the proposal; nothing is saved until the definition is explicitly confirmed, and activation remains a separate step.
The valuable transparency is in the evidence trail, not hidden model reasoning
There is an important distinction between an inspectable recommendation and an AI system exposing its internal reasoning. A marketer does not need access to a model’s private chain of thought to govern a campaign responsibly. What matters is whether the system surfaces the business evidence that can be challenged: which events and attributes were used, how the segment is defined, how large it may be, whether the data is sufficiently current and what happens to reach when criteria become more precise.
That level of visibility changes the role of the agent from oracle to drafting partner. If an agent proposes “high-intent customers,” the phrase alone is not actionable evidence. If it shows that the definition depends on specific purchase events, recent product behavior and an existing predictive signal, a marketer can ask whether those inputs actually correspond to the campaign objective. The same recommendation can then be rejected, narrowed or broadened without requiring the marketer to accept the agent’s label at face value.
mParticle’s documentation explicitly describes the agent as an assisted drafting tool. It can explore available signals, answer questions about data, review existing audiences, compare candidate criteria and weigh precision against reach. When a relevant value is unavailable or unclear, the documentation says the system asks for clarification rather than guessing. Those are useful product-design choices, but they should not be confused with proof that every recommendation is correct or that an explanation establishes causality between the selected signals and a future conversion.
Human confirmation is meaningful only when the human has something concrete to review
“Human in the loop” has become a standard promise in agentic software, but a confirmation button is weak governance if the person clicking it cannot evaluate the proposed action. A useful approval step needs enough information to support disagreement. Audience size is one example: an apparently attractive segment may become commercially irrelevant if tightening the definition reduces reach too far, while a broad segment may sacrifice precision for scale. Showing that trade-off before activation gives the marketer a decision to make rather than a machine instruction to rubber-stamp.
The same principle applies to data freshness and availability. Audience membership changes as customer behavior changes, and mParticle supports different audience-refresh models depending on the segmentation workflow. Its audience documentation also distinguishes preliminary estimates from more precise calculated sizes and notes that downstream audience counts can depend on available identities and destination platforms. An estimated audience should therefore be treated as decision context, not as a guaranteed number of reachable customers or future conversions.
Governance also extends to what the agent can access. According to mParticle’s data and privacy documentation, the Audience Agent runs under the authenticated user’s existing workspace permissions and remains read-only until a new audience is explicitly saved. The product uses an OpenAI large language model to interpret requests, with relevant prompt and workspace context processed under mParticle’s enterprise arrangement; the documentation says customer prompts and data are not used to train OpenAI models. It also says processing is in the United States by default and advises organizations with regional requirements to confirm that setup, with region-specific processing planned beginning with the European Union.
Agentic marketing needs an audit surface, not just a conversational interface
The broader lesson goes beyond audience building. Marketing agents will increasingly recommend bids, budgets, creative variants, customer segments and campaign changes. In each case, conversational fluency is a poor proxy for reliability. The more consequential the recommendation, the more valuable it becomes to expose the inputs, constraints, expected scope and uncertainty that a human can independently evaluate.
This is especially important when an agent is connected to proprietary company data. Access to richer context can make recommendations more relevant, but it can also make mistakes harder to notice because the system sounds informed. A segment based on the wrong event definition, stale attribute or misleading behavioral proxy can be internally coherent and still be commercially wrong. Transparency is useful precisely because it gives marketers a surface on which to test those assumptions before execution.
The sponsored mParticle example does not demonstrate that this design produces higher return on ad spend, fewer segmentation errors or better decisions than manual audience building. No independent comparative study is presented. What it does illustrate is a sensible standard for evaluating agentic marketing products: recommendation quality should not be judged only by how quickly an agent produces an answer, but by whether the organization can inspect and challenge the evidence behind that answer.
As marketing software becomes more autonomous, the important question will not be whether an AI agent can propose the next action. Many systems will be able to do that. The differentiator will be whether marketers can understand what the action is based on, see the trade-offs before committing and retain clear authority over what enters production. An agent becomes easier to trust not when it sounds more certain, but when its recommendation remains legible enough for a human to disagree.