
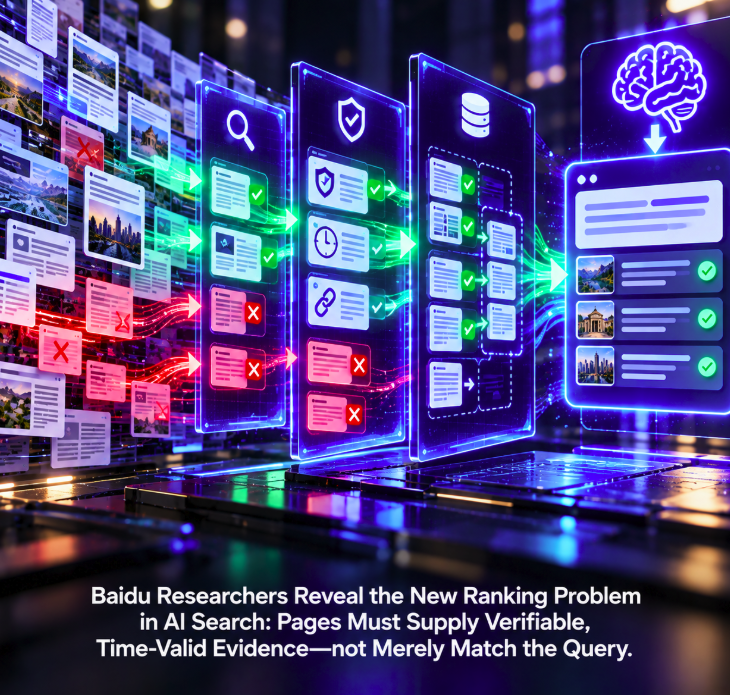
The ranking problem changes when a search engine stops handing documents to a human and starts handing evidence to a model. A new Baidu-linked research paper argues that conventional query-document relevance is no longer enough for AI search because the retrieved page is not necessarily the product the user consumes. It is an intermediate ingredient in a generated answer, and that creates a different requirement: the page must contribute usable evidence, that evidence must be trustworthy and temporally valid, and the final source set must work together inside a limited model context.
The framework appears in the arXiv preprint “From Ranked Documents to Reliable Contexts: An Answer-Oriented Context Construct Framework for AI Search”, whose third revision is dated September 23. Several authors are affiliated with Baidu, alongside researchers from the Chinese Academy of Sciences, the University of Chinese Academy of Sciences and Wuhan University. The paper describes an industrial implementation and production component experiments, but it does not establish that the complete framework is the current source-selection architecture of Baidu Search. The work should therefore be read as a Baidu-linked industrial research proposal with internal experimental results, not a public specification of Baidu’s live ranking system.
Traditional relevance answers the wrong question for a generation model
Classic web search ranks documents for people. A result can be useful because it looks relevant, comes from an authoritative domain, is recent and is well presented; the user then decides what to read, compares sources and resolves contradictions. AI search transfers much of that work from the user to the retrieval and generation pipeline.
The authors argue that this creates a structural mismatch. A page can match a query closely while contributing little evidence needed to construct a good answer. Conversely, a document that looks less directly aligned with the wording of the query can contain facts, premises or context from which the answer can be derived. Their proposed first-stage concept, “Answer Support,” therefore asks a different question from ordinary relevance: does this document actually contribute information the generator can use?
That is a consequential distinction for GEO. A page optimized to mirror the query may still lose to a source that supplies a more useful fact, primary evidence or explanatory premise. The target is no longer merely semantic alignment between query and document; it is informational contribution to the answer.
This fits a retrieval problem NetContentSEO recently examined in Perplexity’s first-stage retrieval benchmark. Getting into the candidate pool is one gate. The Baidu-linked framework describes additional gates after retrieval: whether the document can support the answer, whether its evidence can be trusted and whether it deserves scarce space in the final generation context.
Authority becomes source-to-claim fitness rather than a site-wide badge
The second stage, Content Trustworthiness, breaks reliability into source, temporal and information dimensions. The source component is particularly interesting because the authors explicitly move beyond static site-category authority. Their industrial upgrade considers whether the producer is actually appropriate for the information being supplied.
A prestigious domain is not automatically the best source for every claim it contains. A lower-category source can sometimes have first-hand access, specialist expertise or stronger domain alignment for a specific piece of information. In the paper’s component evaluation, replacing static site-category authority with source-role assessment improved the automatic answer pass rate by 5.2 percentage points and produced a 2.7% human-evaluated Net Gain.
Those are internal results from the authors’ experimental environment, not independently replicated effects or universal ranking weights. But the conceptual change is important: authority in AI retrieval can be claim-dependent. The system needs to ask not only whether a website is trusted in general, but whether this source is qualified to support this particular evidence.
A new page can still contain old information
The paper’s treatment of time is even more directly relevant to publishers. Traditional freshness signals commonly use publication date as a proxy for whether information is current. The researchers argue that publication recency and information validity are different variables. A newly published article can describe an expired policy, superseded software version or obsolete event state.
The industrial implementation therefore introduces “content-time” identification: instead of asking only when the page was published, it attempts to determine the temporal state represented by the information itself. In the reported experiment, moving from publication time to content time increased the automatic answer pass rate by 4.1 percentage points and produced a 3.5% human Net Gain.
The researchers go further with query-conditioned expiration modeling. A fixed freshness threshold cannot work equally well for a live sports score, a tax rule, a product specification and a historical fact. Their system attempts to estimate when information should stop being considered applicable to the query. That upgrade produced a 3.0-point increase in automatic answer pass rate and a 2.4% human Net Gain in the study.
For publishers, the implication is sharper than “update old articles.” A visible 2026 date cannot by itself make a page temporally reliable. The claims inside the page need to make their applicable version, period, policy state or event stage legible enough for a retrieval system to distinguish current evidence from merely recent publishing.
Claim verification adds another gate after authority and freshness
The framework’s third trust dimension asks whether consequential factual claims can be corroborated by traceable evidence. The authors add claim-level verification before information is allowed to feed generation. In their component experiment, that upgrade raised the high-quality result-set rate by 4.8 percentage points, increased the automatic answer pass rate by 3.9 points and delivered a 4.2% human-evaluated Net Gain.
This is where AI source optimization diverges most clearly from conventional page ranking. A document can be topically relevant, well written, recently published and hosted on a credible domain, yet still introduce an unsupported factual assertion. In a traditional SERP, a human reader may notice the weakness after opening the page. In AI search, the model can absorb the claim and repeat it before the user ever sees the underlying source.
The researchers therefore treat verifiability as a pre-generation retrieval property, not merely a citation feature added after the answer is written. The evidence has to survive scrutiny before it becomes model context.
The largest human gain came from removing the rest of the page
Perhaps the most practical result in the paper concerns passage extraction. The authors inserted an extractive refinement stage that removes non-contributing material while preserving source-faithful passages that support the answer. It produced a 4.1-percentage-point increase in automatic answer pass rate and an 8.9% human-evaluated Net Gain—the largest human gain among the individual component upgrades reported in the table.
The result suggests that retrieving the correct URL is not the end of the source-selection problem. A long page can contain excellent evidence buried inside navigation, background material, repeated explanations or sections irrelevant to the current question. Giving all of that text to a generator consumes context and makes the useful evidence harder to locate.
The authors describe extraction as more than compression. By increasing the density of answer-supporting information while preserving the original passages, the system can make evidence easier for the generator to use without first rewriting it. That source-faithful property also preserves provenance better than immediately converting every document into a synthetic summary.
This provides a useful counterweight to simplistic GEO formatting advice. NetContentSEO recently covered a controlled experiment in which headings and lists changed citation distribution without reliably getting a source selected. The Baidu-linked work points to a deeper optimization target: not cosmetic structure by itself, but the ability of retrieval systems to isolate dense, source-faithful evidence that genuinely contributes to the answer.
AI search ranks a set of evidence, not just a list of pages
The framework’s third stage, Context Organization, moves from evaluating documents individually to deciding how they work together. A model has a finite context budget, so the system cannot simply append every highly ranked page. It must remove redundant material, preserve complementary evidence, cover different aspects of the query and decide how to order what remains.
The paper reports that adding a set-wise organizer improved query-level usability by 7.2 percentage points, although the downstream automatic answer pass rate rose by a more modest 1.8 points and human Net Gain by 1.0%. A later unified extractor-organizer, which jointly decides which documents and passages to retain, produced a 1.5-point automatic answer gain and 2.8% human Net Gain.
That gap is informative. Better evidence organization creates better conditions for generation, but the model can still fail to synthesize the evidence correctly. Retrieval quality and answer quality are connected without being identical.
For publishers, set-wise selection creates a competitive dynamic different from ten blue links. A page can be individually useful but redundant once another source already covers the same fact. Another page may survive because it contributes one complementary piece of evidence that completes the answer. The unit of competition becomes contribution to an evidence portfolio.
Citation visibility is downstream of several invisible decisions
The framework also helps explain why visible citations are an incomplete measure of AI-search visibility. Before a source can appear next to an answer, it may need to pass first-stage retrieval, demonstrate answer support, satisfy trustworthiness checks, survive passage extraction and win a place in a jointly constructed context.
Even then, visible citation behavior can diverge from actual influence. NetContentSEO has previously examined research distinguishing citation selection from citation absorption: appearing in the source list does not necessarily mean a page materially shaped the generated response. The Baidu-linked framework approaches the same problem from upstream. It tries to make the context itself answer-oriented before the generator begins writing.
Together, those views suggest that GEO measurement needs more than citation counts. Source visibility is the output of a chain of hidden competitions, and the most important one may be whether the system considers a page useful evidence at all.
The paper does not reveal Baidu Search’s live ranking algorithm
The industrial language in the paper deserves careful interpretation. The authors describe production component upgrades and online experiments, and six authors list Baidu affiliations. That is stronger evidence than a purely theoretical retrieval proposal. But the paper does not say that the entire three-stage architecture is currently deployed as the end-to-end ranking system for Baidu Search, nor does it expose the full candidate-generation or source-selection stack of a commercial product.
The experiments also come from the authors’ own implementation and evaluation protocol. Automatic evaluation uses model-based judgments under standardized rubrics, complemented by human pairwise evaluation at the answer level. The reported improvements have not yet been independently replicated, and the arXiv paper remains a preprint rather than a peer-reviewed publication.
Those limitations matter especially for SEO interpretation. The numbers should not be converted into supposed Baidu ranking-factor weights, and there is no basis for claiming that adding a particular timestamp, citation format or page structure will produce the reported gains on a publisher’s site.
The new optimization target is evidence fitness
The paper’s larger contribution is not a checklist. It is a different model of what ranking means once search becomes answer generation. Traditional relevance asks whether a document matches the information need. Answer-oriented retrieval asks whether the document contributes something useful, whether that contribution can be trusted now, and whether it improves the collective evidence available to the model.
That reframes several familiar SEO concepts. Freshness becomes temporal validity. Authority becomes fitness of the source for the claim. Content quality becomes the density and extractability of useful evidence. Ranking becomes set construction under a context budget. And the ultimate optimization signal moves closer to whether the generated answer is actually correct.
For publishers, that does not make traditional SEO irrelevant; AI systems still need to discover and retrieve pages before they can evaluate their evidence. But it suggests a second competition begins after retrieval. A page that merely matches the query may reach the candidate set and still lose its place in the answer context.
The stronger target is a page that supplies facts a model can use, evidence it can verify, temporal states it can interpret and passages that add something the rest of the source set does not. If the Baidu-linked framework captures the direction of industrial AI search, the next ranking problem is not simply “Which page is most relevant?” It is “Which combination of evidence gives the model the best chance of being right?”