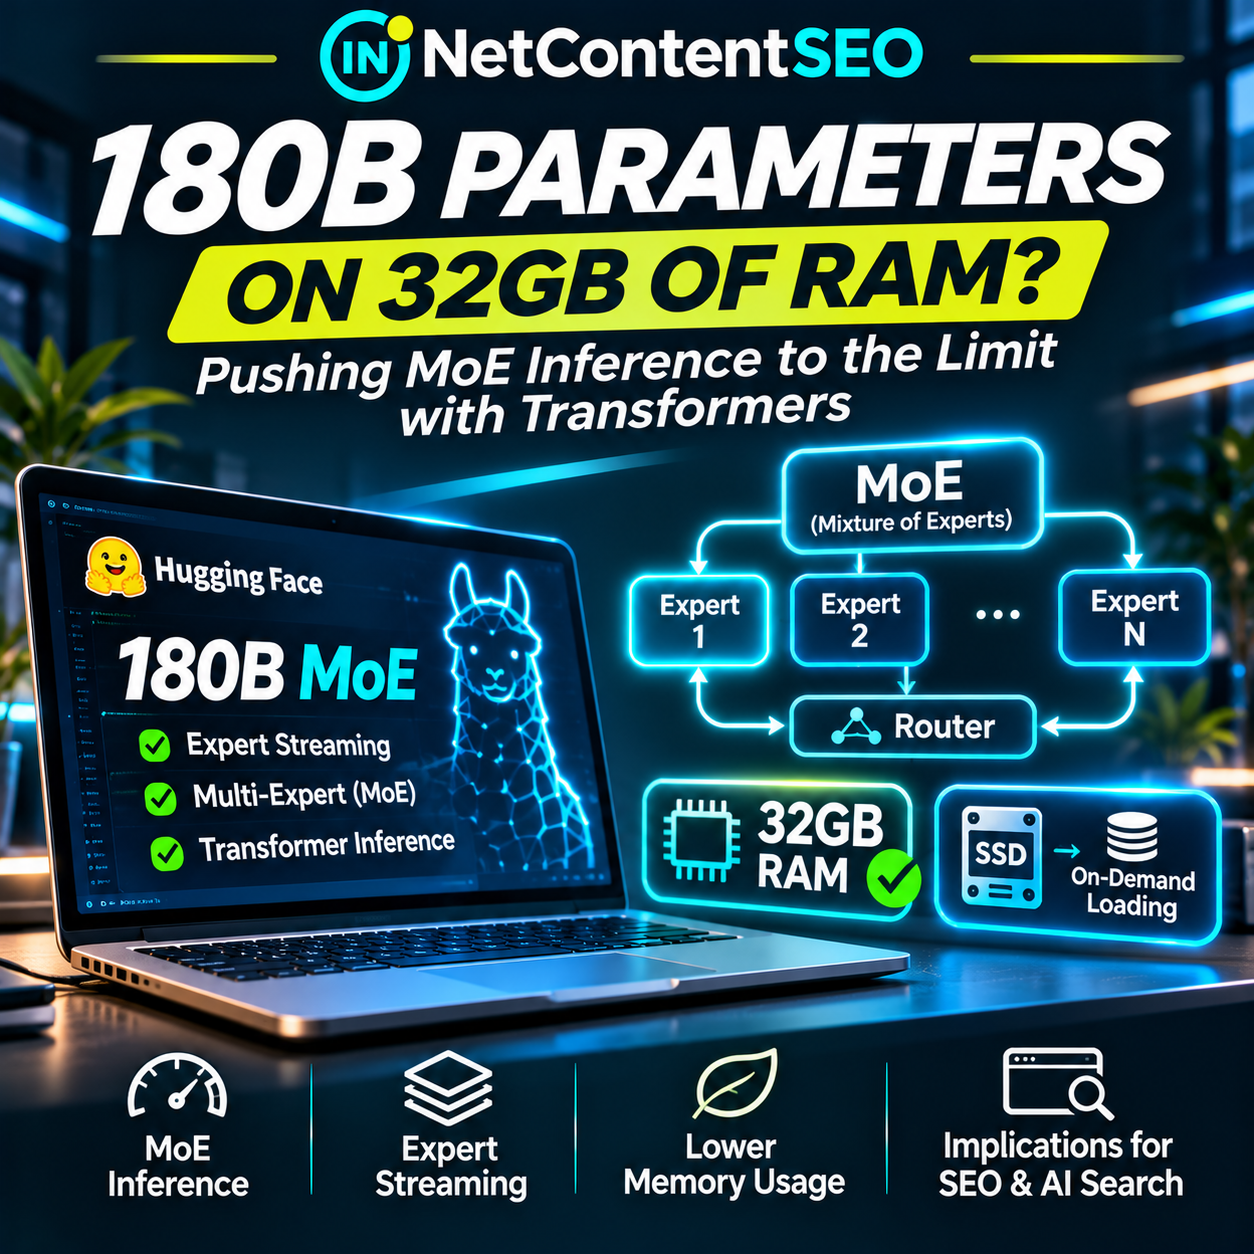
Could a 180-billion-parameter AI model run on a machine with only 32 GB of RAM? A new Hugging Face article, titled “180B Parameters, 32GB of RAM: Pushing MoE Inference to the Limit with Transformers”, puts this provocative engineering question in the spotlight. The title was indexed on November 18, 2026, but the full original article could not be retrieved during our research. As a result, the exact model, implementation, storage configuration, benchmark numbers and speed are not independently verified here. The headline should be treated as a reported demonstration, not evidence that any 180B model will run well on an ordinary 32 GB computer.
What can be explained with confidence is the underlying idea: mixture-of-experts (MoE) models activate only a subset of their parameters for each token. If expert weights can be loaded or streamed on demand rather than kept entirely in RAM or VRAM, the maximum model size a machine can address may become much larger than its memory capacity. But that shifts the bottleneck toward storage bandwidth, caching and latency. For local AI, RAG and AI Search infrastructure, the distinction between can run and can serve useful requests efficiently is critical.
What has actually been verified?
Hugging Face's official February 2026 technical overview of MoEs in Transformers explains sparse expert routing and the library's weight-loading and execution abstractions. Its Experts Interface documentation describes execution backends such as eager, batched_mm and grouped_mm, including memory-performance trade-offs. These sources establish the general engineering foundations, but they do not independently verify the new article's 180B-on-32GB experimental results.
| Claim | Verification status | What it means |
|---|---|---|
| New Hugging Face article describes 180B parameters and 32 GB RAM | Headline indexed; full article inaccessible in this research session | Reported experiment, details pending verification |
| MoE activates only selected experts per token | Confirmed by Hugging Face documentation | Compute can be sparse even when total parameter count is large |
| Expert backends have different memory and performance characteristics | Confirmed by official documentation | Execution strategy affects practical performance |
| Specific 180B model, tokens per second and hardware configuration | Not verified | No benchmark figures should be invented |
| Any 32 GB PC can run this setup at interactive speed | Not established | Hardware, storage and software compatibility still matter |
Why 180 billion parameters do not necessarily mean 180 billion active calculations
In a dense transformer, most model parameters participate in processing each token. A mixture-of-experts architecture replaces selected feed-forward layers with collections of expert networks and a router. For each token, the router chooses a subset of experts. Total parameter count measures the full model's capacity; active parameters more closely indicate the computational work required for a token.
Hugging Face illustrates this with gpt-oss-20b: approximately 21 billion total parameters, but about 3.6 billion active parameters per token. Its technical overview reports around 115 tokens per second on an M3 Ultra Mac under the specified setup, illustrating how active-parameter count and memory bandwidth influence generation speed. That example is not a performance measurement of the newly announced 180B experiment.
Sparsity does not make inactive expert weights disappear. A router may select different experts for the next token, and those weights must remain available somewhere: accelerator memory, system RAM, storage or a distributed system. This is the core challenge behind expert streaming.
The memory arithmetic behind the headline
A hypothetical dense 180B-parameter model stored in 16-bit precision would require approximately 360 GB just for weights, before runtime overhead. At eight bits, raw weights would require about 180 GB; at four bits, roughly 90 GB. These are decimal approximations, not actual measured footprints. Quantization metadata, scales, shared layers, temporary tensors, KV cache and framework allocations add overhead.
| Illustrative weight format | Raw storage for 180B parameters | Fits wholly in 32 GB RAM? |
|---|---|---|
| 16-bit | 360 GB | No |
| 8-bit | 180 GB | No |
| 4-bit | 90 GB | No |
| 2-bit theoretical minimum | 45 GB | No |
These values are calculated from parameter count and nominal bit width. They do not prove the article's storage precision or model architecture. The point is that even aggressive quantization does not trivially fit all 180 billion weights into 32 GB. Some form of offloading, selective loading, compression beyond these simple examples or another memory-management technique would be required.
How expert streaming can change the equation
In an expert-streaming design, a system retains essential shared layers and frequently used experts in fast memory while storing less frequently used expert weights in a larger, slower tier. When the router selects an expert that is not resident, the runtime fetches its weights, performs the computation and may retain or evict them according to a cache policy.
The concept is straightforward; implementation is not. Expert selection can change token by token and layer by layer. If the runtime must wait for an SSD read every time a new expert is selected, storage latency can dominate generation. Useful implementations need to minimize transferred bytes, reuse resident experts, overlap I/O with computation where possible and avoid excessive memory fragmentation. The actual new Hugging Face article's specific implementation cannot be confirmed without access to its full text.
RAM, VRAM and SSD are not interchangeable
VRAM is designed for high-throughput accelerator computation. System RAM is generally larger and cheaper but may be separated from the GPU by a slower interconnect. SSD storage offers much greater capacity but typically has substantially higher access latency and lower effective bandwidth than RAM. Streaming moves the capacity limit, but it does not remove the hierarchy.
For example, transferring a hypothetical 1 GB of weights at an effective 3 GB/s requires at least about 0.33 seconds for the transfer alone, excluding software overhead, random-access effects and compute. That is an illustrative calculation, not a benchmark from Hugging Face. A model that repeatedly moves several gigabytes of expert weights per generated token could become too slow for interactive chat, even if it technically produces correct output.
What Transformers already provides for MoE execution
Hugging Face's official documentation describes multiple experts backends. eager processes selected experts through a straightforward reference implementation, useful for correctness checks. batched_mm can accelerate small GPU-heavy workloads but duplicates selected expert parameters and therefore consumes more memory. grouped_mm groups tokens by expert and uses grouped matrix multiplication, often providing better memory efficiency. Other backends support specialized GPU architectures and quantized formats.
These abstractions matter because expert streaming needs a clean separation between where weights live, how selected experts are gathered and how their matrix operations are executed. However, the existence of the Experts Interface does not establish that the new 180B experiment uses a particular backend or that every model supports identical offloading behavior.
What performance numbers should we demand?
Any claim of large-model inference on consumer hardware should include more than parameter count and RAM capacity. A reproducible report should identify the exact model and checkpoint, weight precision, storage footprint, CPU and GPU configuration, available VRAM, SSD type, runtime version, context length, prompt-processing speed, decode tokens per second, peak resident memory and time to first token.
It should also test more than a single short prompt. Different prompts may activate different experts and create different cache-hit rates. Longer contexts increase KV-cache requirements. Multi-user serving changes batching behavior and cache pressure. If a model uses approximations that skip experts or modify routing, output quality must be compared against a suitable reference. None of those details can safely be inferred from the 180B/32GB headline alone.
Why this matters for local AI and independent infrastructure
For an organization building an independent AI server, expert streaming could eventually expand the range of models available on hardware that cannot hold every weight in memory. This is attractive for document analysis, retrieval-assisted research, editorial assistance and scheduled AI agents where occasional slow responses may be acceptable.
But a larger parameter count is not automatically a better deployment choice. A smaller model that responds quickly, uses reliable tools and cites current documents may outperform a much larger but severely storage-bound model in a real workflow. Local inference capacity must be evaluated alongside retrieval quality, latency, energy use, concurrency and maintenance complexity.
For a 32 GB machine, the prudent engineering approach is to start with supported small and mid-sized models, measure realistic workloads and treat large MoE streaming as an experiment until the exact model and software requirements are confirmed. An article about Transformers does not automatically imply that the same setup works unchanged in Ollama, llama.cpp, MLX or another runtime.
The implications for SEO and AI Search
This is an infrastructure development, not a Google Search or Naver Search ranking announcement. It does not introduce a new SEO ranking factor, AI Overview reporting feature or guaranteed improvement in search visibility. Its relevance to AI Search is indirect but potentially important: lower hardware barriers could make specialized retrieval and answer-generation systems more accessible to publishers, agencies and independent developers.
For a publisher, that could mean more private analysis of Search Console exports, content inventories, server logs and multilingual source documents. A local assistant could use retrieval to locate relevant material and then generate a structured explanation. The usefulness of such a system would depend on verified data, robust citations, domain-specific evaluation and the time needed to produce an answer—not merely on the size printed in the model name.
It is also important to separate expert streaming from retrieval-augmented generation (RAG). Expert streaming fetches model weights needed for computation; RAG fetches external information needed to answer a question. Both involve retrieval and caching, but they solve fundamentally different problems. Streaming does not automatically make a model aware of today's search algorithm changes or market prices.
A practical experiment for teams with limited hardware
- Identify a compatible MoE checkpoint, license and exact runtime implementation.
- Record total weights, quantization format, resident RAM/VRAM and storage requirements.
- Establish a no-streaming baseline with a smaller model on the same hardware.
- Measure first-token latency, prompt throughput, decode speed, memory peaks and SSD activity.
- Test short and long contexts, repeated and varied prompts, and at least two concurrency levels.
- Evaluate answer quality on a fixed task set, especially if routing or quantization is modified.
- Compare total latency and power usage with smaller models using verified retrieval tools.
- Publish reproducible configurations and clearly distinguish successful execution from practical production readiness.
Frequently asked questions
Does 180B parameters on 32 GB mean the full model fits in RAM?
Not necessarily. The headline does not establish that all weights are resident. A streaming or offloading design may keep substantial model data on storage and fetch weights as needed.
What is a mixture-of-experts model?
An architecture that routes each token through a subset of specialized learned subnetworks, reducing active computation relative to the model's total parameter count.
Is expert streaming the same as RAG?
No. Expert streaming retrieves neural-network weights for inference; RAG retrieves external documents or other knowledge to support an answer.
How fast is the reported 180B model?
The specific tokens-per-second measurement could not be verified from the accessible source material. No speed claim is made here.
Can this be reproduced with Ollama and 32 GB of RAM?
Compatibility is unverified. It depends on the model format, streaming implementation, runtime support, storage capacity and hardware. The Transformers headline alone is not evidence of an Ollama-ready configuration.
Does this change Google rankings or AI Overview citations?
No such change is documented. The development concerns local inference engineering rather than search ranking or citation measurement.
Conclusion: memory capacity is only one part of usable AI
The reported 180B-on-32GB experiment captures a genuine direction in AI systems engineering: using sparse computation and hierarchical memory to make very large models accessible beyond conventional multi-GPU servers. Hugging Face's existing MoE documentation supports the underlying principles. But until the new experiment's complete methodology and results can be inspected, its practical performance and reproducibility remain open questions. For AI Search and local infrastructure, the important metric is not the largest model that can technically start. It is the most reliable, evidence-grounded result a system can deliver within acceptable time and resource limits.
Sources and verification: Hugging Face, “180B Parameters, 32GB of RAM: Pushing MoE Inference to the Limit with Transformers” (headline indexed November 18, 2026; full page unavailable during research); Hugging Face, “Mixture of Experts (MoEs) in Transformers,” February 26, 2026; Hugging Face Experts Interface documentation. Memory calculations and proposed experiments are NetContentSEO analysis, not unverified claims about the newly reported implementation. Barry Schwartz coverage: NOT CHECKED.