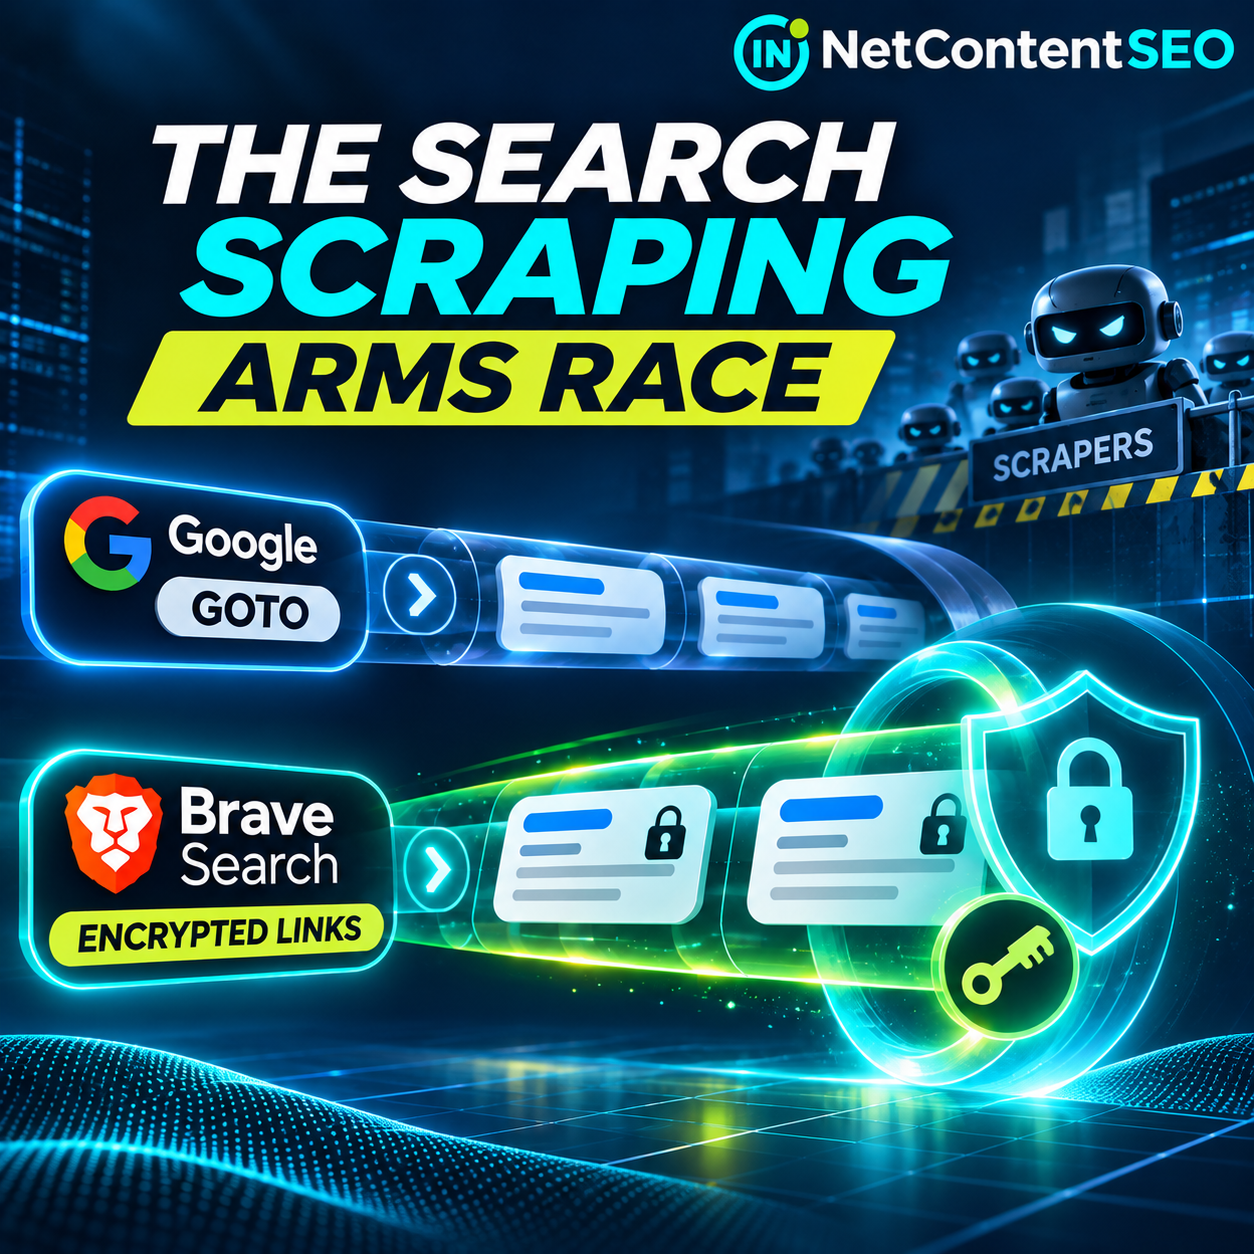
Search engines are entering a new anti-scraping arms race, and the consequences reach far beyond the companies collecting results. Brave Search says Google's rollout of google.com/goto redirects has displaced automated scraping toward independent search engines. Brave's response is an unusual one: encrypt result destinations and let browsers privately obtain the key needed to open the link, without telling Brave which result was clicked.
The development raises three distinct questions for SEO and AI Search professionals. Why are search engines making result URLs harder to extract? Can privacy-preserving redirects discourage large-scale scraping without monitoring individual clicks? And how can ranking and AI visibility platforms avoid mistaking redirect URLs for the actual pages that rank?
What Brave announced
In its technical explanation, Brave says Search result links will begin using a URL-cloaking system. Users clicking a result should still reach the destination site, but the link visible on the results page is a search.brave.com/go/v1#… address containing an encrypted destination rather than the destination URL itself.
Brave attributes this change to a surge of scraping activity after Google deployed its own GOTO redirect mechanism. Brave says it has seen spikes of several thousand requests per second and that defending against this traffic has increased infrastructure pressure and caused more aggressive anti-bot checks for legitimate users. These traffic figures and the claimed causal connection are Brave's own account; independent measurements of Brave's infrastructure load were not available for this analysis.
Google's GOTO redirects: what is independently documented?
Google's use of google.com/goto links is not merely a Brave allegation. Search Engine Roundtable documented the rollout in August 2026, including a Google spokesperson's confirmation that Google regularly deploys technical measures against abuse. Barry Schwartz also reported earlier tests in July and later problems affecting third-party SERP tracking providers.
Google's public statement confirmed a defensive rollout but did not establish Brave's interpretation of Google's commercial motives. Brave argues that Google's changed incentives reflect AI assistants and agents increasingly relying on search results supplied by intermediaries. That is Brave's analysis, not a verified explanation from Google.
How Brave's privacy-preserving redirect works
Most ordinary redirect services can observe the destination a user visits, because the request passes through a server that knows where to send the browser. Brave says it deliberately designed a different approach using a partially oblivious pseudorandom function, or POPRF.
The destination URL is encrypted in the link. When the user selects a result, browser-side code requests the decryption material through a blinded cryptographic exchange. Brave can process the request without learning which specific link was selected. The browser unblinds the result, decrypts the destination locally and navigates directly to the website.
Brave says the system still exposes some context, such as the results page involved and the timing of a request. It is therefore more accurate to describe the design as hiding the particular clicked result from Brave than as making all user activity completely unobservable.
Why this makes mass scraping more expensive
A human searcher normally opens only a few results. A scraper collecting full search-result inventories may want every destination URL from many pages. Under Brave's design, each encrypted link needs its own key-retrieval operation. The search engine can count those operations per results page without identifying which individual link a particular user clicked.
This changes the economics of extraction: collecting hundreds of destination URLs requires additional interactions instead of simply parsing plain-text links from the HTML. It does not prove that scraping becomes impossible, and Brave does not claim that a cryptographic redirect alone will eliminate automated collection.
Brave also points to its official Search API as the supported route for applications and agents needing results at scale. Its API is a product with its own pricing, usage and licensing conditions; it is not a blanket permission to republish arbitrary results.
Important limitations for users
Brave acknowledges several trade-offs. Copying a search result link may copy the redirect URL instead of the actual destination, and redirect links may expire, making them unsuitable as durable bookmarks. A trusted-looking redirect domain can also be abused for phishing, so Brave describes mitigations including expiration, revocation and warning interstitials.
JavaScript-disabled users face another privacy limitation. Brave says the browser-side oblivious exchange cannot run in that setting, so a conventional server-side redirect is used and Brave can then see the destination URL. The privacy guarantee is therefore conditional on the supported client-side flow.
Why SEO rank trackers may record the wrong URLs
For ranking tools, the key technical distinction is between the URL presented in a SERP's link element and the actual canonical destination. If an extractor records only the link attribute, it may save a Google or Brave redirect rather than the publisher's page.
This is not theoretical for Google. Search Engine Roundtable reported difficulties for third-party rank tracking in October amid Google's anti-scraping changes. However, those reports do not quantify how many providers currently misattribute redirect destinations, and no specific vendor should be presumed broken without testing.
A tool that cannot reliably resolve a destination should flag the record as unresolved instead of treating google.com/goto or search.brave.com/go as a new ranking domain.
What AI agents and search API buyers should understand
Many AI applications use a search retrieval layer to find current information, then fetch selected pages to support an answer. The retrieval layer might use a licensed search API, an independent index or an intermediary provider. Changes in SERP extraction can affect which URLs the application receives, the freshness of its results and whether it can retrieve the underlying content.
That does not mean Google or Brave has changed the ranking criteria of its organic results, nor that either company's anti-scraping measures directly change AI citation algorithms. The immediate risk is data acquisition and measurement quality. Any downstream change in answer quality or citation selection needs to be tested separately.
Brave's independent index is particularly relevant because an agent developer can choose its API rather than depending on scraped Google result pages. But independence, licensing and accuracy are different properties; teams should evaluate all three.
A practical audit for SEO and GEO data teams
- Identify the source of every SERP dataset. Record whether results come from a first-party API, a licensed provider, browser observation or automated extraction.
- Separate observed link URLs from destination URLs. Store both when legally and technically available, with a resolution status and timestamp.
- Detect intermediary links. Flag Google GOTO, Brave GO and other redirect patterns as intermediary URLs rather than treating them as ranking destinations.
- Check data completeness. Measure missing destinations, unresolved redirects, bot challenges, timeouts and differences in result counts over time.
- Validate with controlled samples. Compare a modest, representative set of manually observed results with vendor exports, respecting applicable terms and access rules.
- Monitor vendor methodology changes. Ask providers how they handle redirects and whether their collection method changed during the measurement period.
- Segment trends by engine and provider. A sudden rise in unknown URLs from one source may indicate extraction trouble rather than a real visibility collapse.
- Use first-party signals where available. Search Console, Bing Webmaster Tools, referral analytics and platform-native reporting can complement third-party observations, though none offers a complete view of all AI citations.
- Document uncertainty. Mark gaps in ranking or citation data explicitly; avoid inventing missing destinations or interpolating a supposedly precise share-of-voice number.
What publishers should do
For most publishers, no special technical action is required solely because Brave or Google changes how outbound result links are encoded. Maintain crawlable, useful content and ensure destination pages respond correctly when visitors arrive. Monitor referral traffic and landing pages, but do not assume a search-engine redirect will always appear in the final browser address.
If analytics attribution changes, compare referrer information, landing-page sessions and server-side logs before concluding that search visibility declined. Redirect design can affect the path a visitor takes, while the browser's privacy rules and referral policies can affect what analytics receives. Those effects must be observed in the actual implementation rather than guessed.
Does Brave's new scheme affect indexing?
Brave's announcement concerns the links shown on its search results pages, not a newly announced change to how Brave crawls or indexes websites. Its crawler documentation describes a separate indexing process. Likewise, Google's GOTO links should not be confused with a publisher changing its own 301 or 302 redirects.
Frequently asked questions
Why is Brave encrypting search result links?
Brave says it wants to make large-scale result extraction more costly while avoiding a conventional click-tracking redirect that reveals the specific destination to its servers.
Did Google confirm its GOTO rollout?
Yes. Google confirmed the rollout to Search Engine Roundtable in August 2026, describing its anti-abuse work in general terms.
Did Google cause Brave's traffic spike?
Brave attributes the spike to scrapers shifting away from Google. That causal explanation is not independently established by the sources reviewed.
Can Brave see which result I clicked?
Brave says its browser-side POPRF design hides the particular selected result, while some request context remains visible. The protection differs when JavaScript is disabled.
Will copied Brave result links work forever?
Not necessarily. Brave says its redirect links can expire and should not be treated as permanent bookmarks.
Does this make SEO rank tracking impossible?
No. It can make automated collection harder and increase uncertainty. Providers using legitimate data access and robust quality checks can still measure results, subject to the data they can obtain.
Is this a new ranking factor or an AI citation update?
No evidence in the announcement establishes either. The confirmed subject is result-link handling and anti-scraping infrastructure.
What should an AI developer use instead of scraping?
Evaluate authorized search APIs, including Brave Search API, for coverage, cost, licensing, freshness and reliability.
The bigger picture: search data is becoming strategic infrastructure
Google and Brave are responding to a world in which search results power not only human browsing but also automated research, chatbots and agents. The resulting controls may protect infrastructure and commercial interests while creating new challenges for independent measurement.
For SEO and GEO, the most defensible conclusion is not that ranking has changed. It is that the reliability of the data used to describe ranking and AI visibility can change suddenly when the underlying search engine changes how results are delivered. Treat collection integrity as a first-class metric alongside impressions, clicks and citations.
Sources
- Brave — How Google's anti-scraping move became our problem (and how we solved it in a user-first way)
- Search Engine Roundtable — Google confirms GOTO rollout, August 26, 2026
- Search Engine Roundtable — Third-party rank tracking difficulties, October 12, 2026
- Brave Search API — official product information
- Brave Search — crawler documentation